为智能体编写有效的工具——借助智能体
Writing effective tools for agents — with agents
段落导航
The Model Context Protocol (MCP) can empower LLM agents with potentially hundreds of tools to solve real-world tasks.
Model Context Protocol(MCP)可以为 LLM 智能体提供可能多达数百个工具,用来解决真实世界的任务。
But how do we make those tools maximally effective?
但我们怎样才能让这些工具发挥最大效用?
In this post, we describe our most effective techniques for improving performance in a variety of agentic AI systems1.
在这篇文章中,我们介绍我们为多种智能体式 AI 系统1提升性能时最有效的技术。
We begin by covering how you can:
我们首先介绍如何:
Build and test prototypes of your tools
构建并测试工具的原型
Create and run comprehensive evaluations of your tools with agents
借助智能体,为你的工具创建并运行全面的评测(eval)
Collaborate with agents like Claude Code to automatically increase the performance of your tools
与 Claude Code 这样的智能体协作,自动提升你的工具的性能
We conclude with key principles for writing high-quality tools we’ve identified along the way:
最后,我们总结在过程中发现的编写高质量工具的关键原则:
Choosing the right tools to implement (and not to implement)
选择该实现哪些工具(以及不该实现哪些工具)
Namespacing tools to define clear boundaries in functionality
对工具做命名空间划分,以定义清晰的功能边界
Returning meaningful context from tools back to agents
从工具向智能体返回有意义的上下文
Optimizing tool responses for token efficiency
针对 token 效率优化工具响应
Prompt-engineering tool descriptions and specs
为工具描述和规范做提示词工程(prompt engineering)
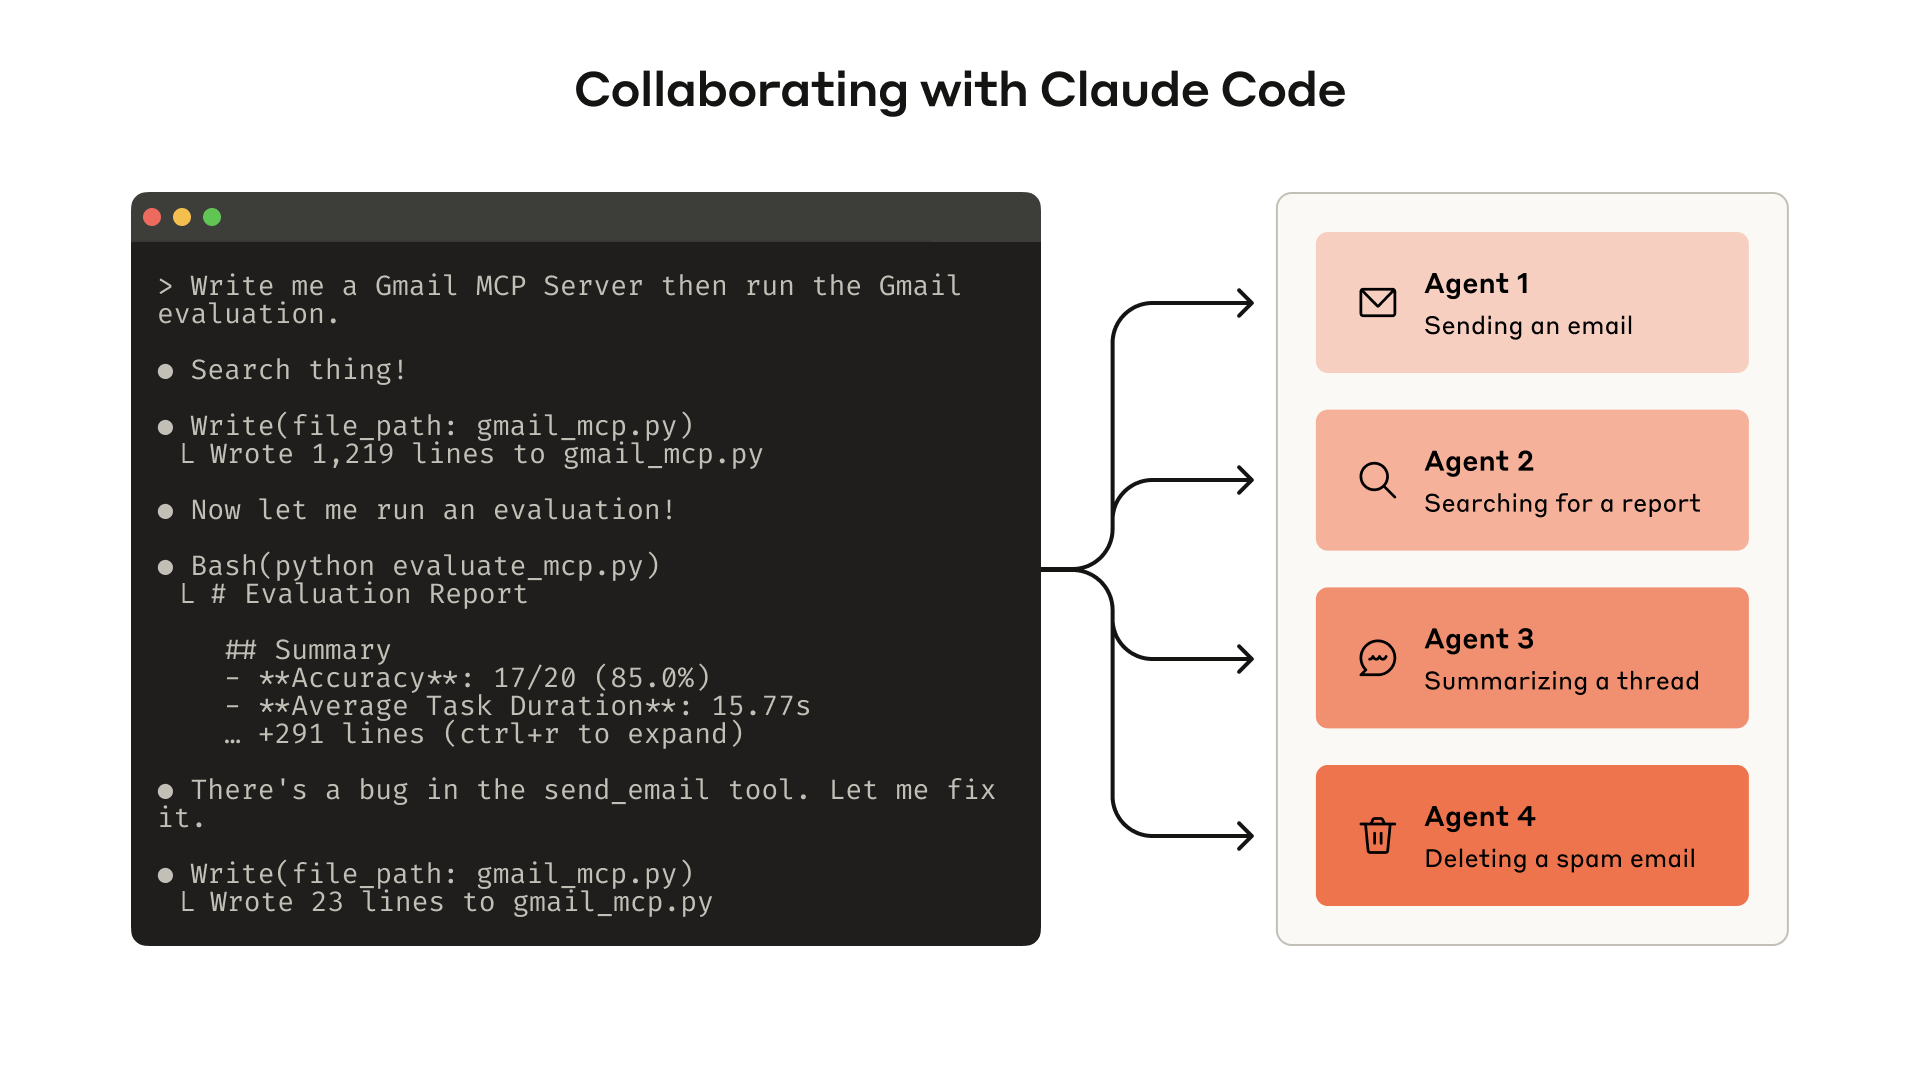
Building an evaluation allows you to systematically measure the performance of your tools.
构建一个评测可以让你系统地衡量你的工具的性能。
You can use Claude Code to automatically optimize your tools against this evaluation.
你可以使用 Claude Code 针对这个评测自动优化你的工具。
In computing, deterministic systems produce the same output every time given identical inputs, while non-deterministic systems—like agents—can generate varied responses even with the same starting conditions.
在计算领域,确定性系统在给定相同输入时每次都会产生相同的输出,而非确定性系统——比如智能体——即使在相同的起始条件下也能生成不同的响应。
When we traditionally write software, we’re establishing a contract between deterministic systems.
当我们以传统方式编写软件时,我们是在确定性系统之间建立一种契约。
For instance, a function call like getWeather(“NYC”) will always fetch the weather in New York City in the exact same manner every time it is called.
例如,像 getWeather(“NYC”) 这样的函数调用,每次被调用时都会以完全相同的方式获取纽约市的天气。
Tools are a new kind of software which reflects a contract between deterministic systems and non-deterministic agents.
工具是一种新型软件,它体现了确定性系统与非确定性智能体之间的契约。
When a user asks "Should I bring an umbrella today?,” an agent might call the weather tool, answer from general knowledge, or even ask a clarifying question about location first.
当用户问“我今天该带伞吗?”,智能体可能会调用天气工具、根据通用知识回答,甚至先询问关于地点的澄清问题。
Occasionally, an agent might hallucinate or even fail to grasp how to use a tool.
有时,智能体可能会产生幻觉,甚至无法理解如何使用某个工具。
This means fundamentally rethinking our approach when writing software for agents: instead of writing tools and MCP servers the way we’d write functions and APIs for other developers or systems, we need to design them for agents.
这意味着在为智能体编写软件时,我们要从根本上重新思考方法:不是像为其他开发者或系统编写函数和 API 那样来编写工具和 MCP 服务器,而是需要为智能体设计它们。
Our goal is to increase the surface area over which agents can be effective in solving a wide range of tasks by using tools to pursue a variety of successful strategies.
我们的目标是扩大智能体能够有效发挥作用的覆盖面:通过使用工具采取各种成功的策略,解决广泛的任务。
Fortunately, in our experience, the tools that are most “ergonomic” for agents also end up being surprisingly intuitive to grasp as humans.
幸运的是,根据我们的经验,对智能体来说最“符合工效学”的工具,最终对人类来说也出奇地直观易懂。
In this section, we describe how you can collaborate with agents both to write and to improve the tools you give them.
在本节中,我们描述如何与智能体(agent)协作,既编写也改进你提供给它们的工具。
Start by standing up a quick prototype of your tools and testing them locally.
先从快速搭建你的工具原型并在本地测试它们开始。
Next, run a comprehensive evaluation to measure subsequent changes.
接下来,运行全面的评测,以衡量后续的更改。
Working alongside agents, you can repeat the process of evaluating and improving your tools until your agents achieve strong performance on real-world tasks.
与智能体并肩工作,你可以重复评估和改进工具的流程,直到你的智能体在真实世界任务上取得强劲性能。
It can be difficult to anticipate which tools agents will find ergonomic and which tools they won’t without getting hands-on yourself.
如果不亲自上手,就很难预判智能体会觉得哪些工具用起来顺手、哪些不顺手。
Start by standing up a quick prototype of your tools.
先从快速搭建你的工具原型开始。
If you’re using Claude Code to write your tools (potentially in one-shot), it helps to give Claude documentation for any software libraries, APIs, or SDKs (including potentially the MCP SDK) your tools will rely on.
如果你使用 Claude Code 编写你的工具(可能一次完成),为 Claude 提供你的工具所依赖的任何软件库、API 或 SDK(可能包括 MCP SDK)的文档会很有帮助。
LLM-friendly documentation can commonly be found in flat llms.txt files on official documentation sites (here’s our API’s).
对 LLM 友好的文档通常可以在官方文档站点上的扁平 llms.txt 文件中找到(这里是我们 API 的)。
Wrapping your tools in a local MCP server or Desktop extension (DXT) will allow you to connect and test your tools in Claude Code or the Claude Desktop app.
将你的工具封装在本地 MCP 服务器或桌面扩展(DXT)中,将使你能够在 Claude Code 或 Claude Desktop 应用中连接并测试你的工具。
To connect your local MCP server to Claude Code, run claude mcp add <name> <command> [args...].
要将本地 MCP 服务器连接到 Claude Code,请运行 claude mcp add <name> <command> [args...]。
To connect your local MCP server or DXT to the Claude Desktop app, navigate to Settings > Developer or Settings > Extensions, respectively.
要将本地 MCP 服务器或 DXT 连接到 Claude Desktop 应用,请分别导航到 Settings > Developer 或 Settings > Extensions。
Tools can also be passed directly into Anthropic API calls for programmatic testing.
工具也可以直接传入 Anthropic API 调用中,以进行程序化测试。
Test the tools yourself to identify any rough edges.
亲自测试这些工具,找出任何不完善之处。
Collect feedback from your users to build an intuition around the use-cases and prompts you expect your tools to enable.
从用户那里收集反馈,围绕你期望工具支持的用例和提示词(prompt)建立直觉。
Next, you need to measure how well Claude uses your tools by running an evaluation.
接下来,你需要通过运行评测来衡量 Claude 使用你的工具的效果。
Start by generating lots of evaluation tasks, grounded in real world uses.
首先从生成大量基于真实世界用法的评测任务开始。
We recommend collaborating with an agent to help analyze your results and determine how to improve your tools.
我们建议与一个智能体协作,帮助分析你的结果并确定如何改进你的工具。
See this process end-to-end in our tool evaluation cookbook.
在我们的工具评测 cookbook 中端到端地查看这个过程。
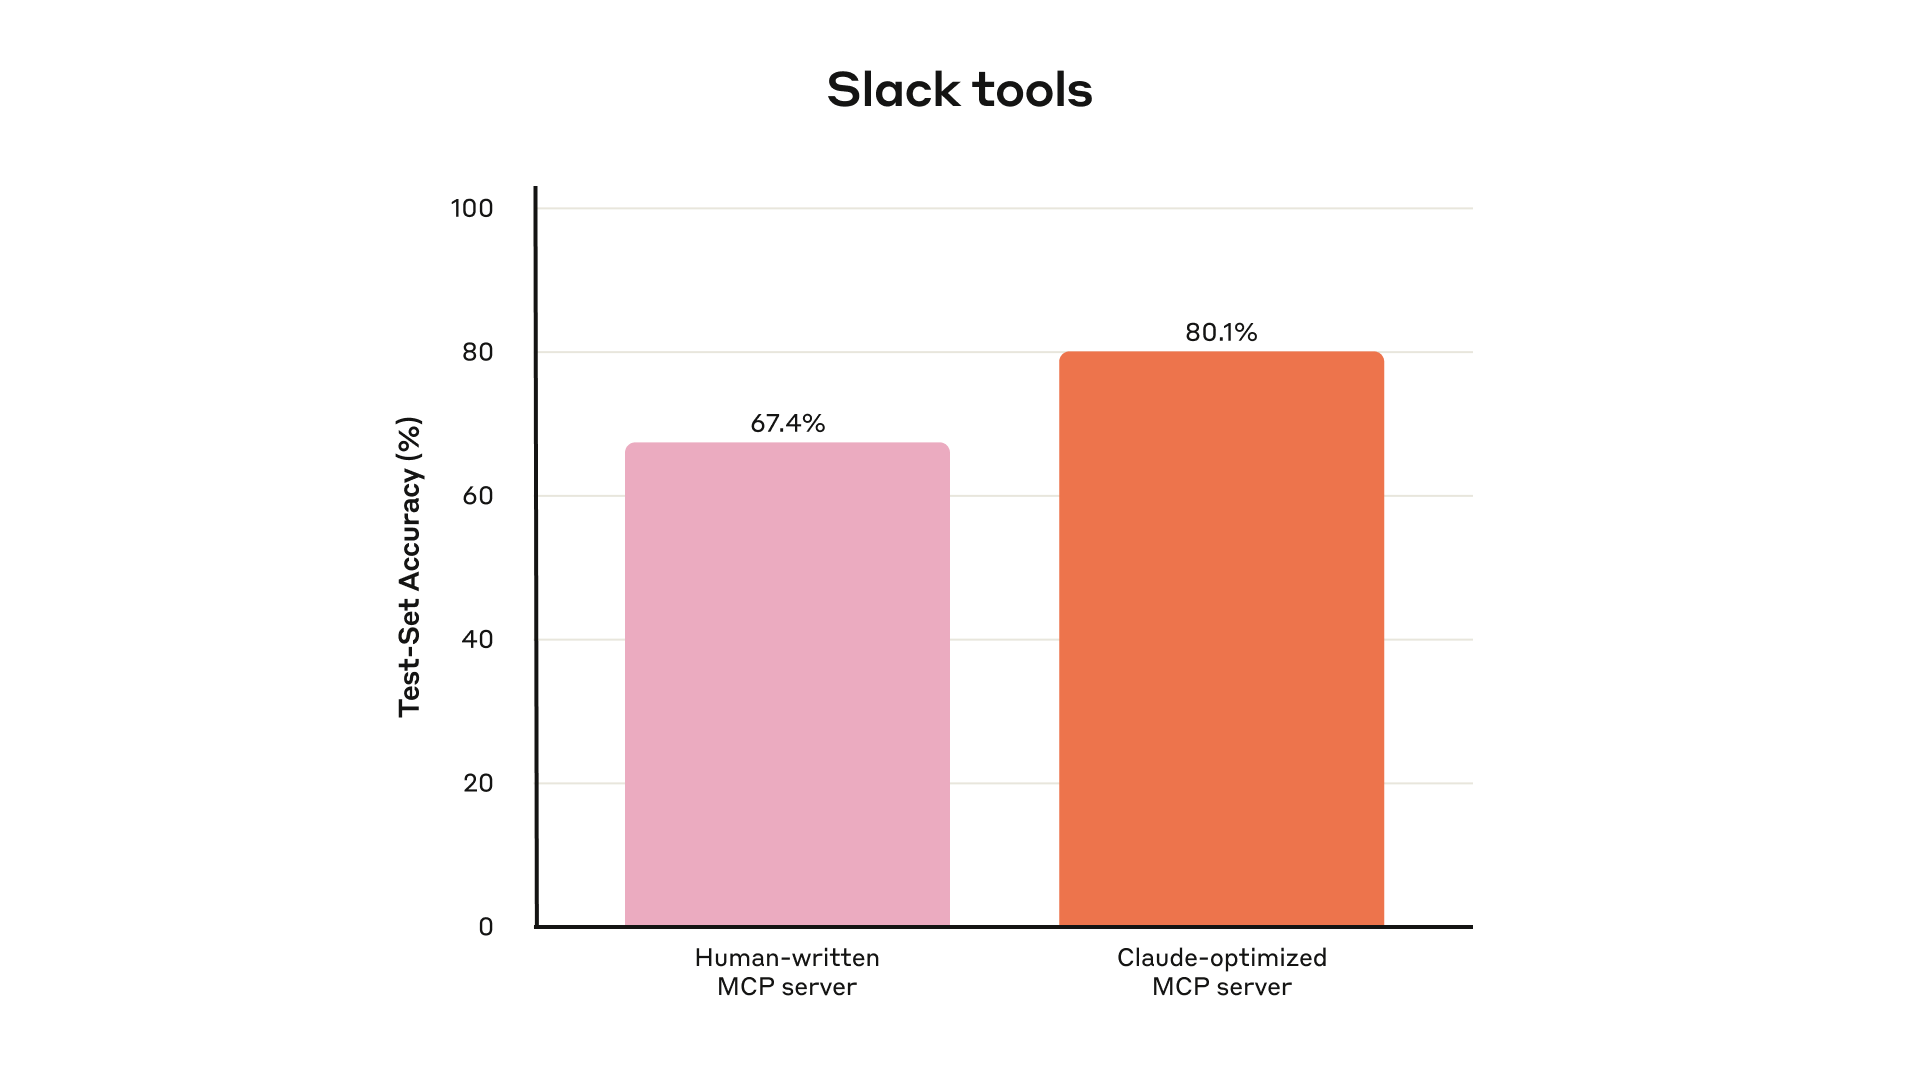
Held-out test set performance of our internal Slack tools
我们内部 Slack 工具的留出测试集(held-out test set)性能
Generating evaluation tasks
生成评测任务
With your early prototype, Claude Code can quickly explore your tools and create dozens of prompt and response pairs.
有了你的早期原型,Claude Code 可以快速探索你的工具并创建数十个提示词和响应对。
Prompts should be inspired by real-world uses and be based on realistic data sources and services (for example, internal knowledge bases and microservices).
提示词应该受到真实世界用法的启发,并基于真实的数据源和服务(例如内部知识库和微服务)。
We recommend you avoid overly simplistic or superficial “sandbox” environments that don’t stress-test your tools with sufficient complexity.
我们建议你避免过于简单或肤浅的“沙箱(sandbox)”环境,这些环境没有用足够的复杂性对你的工具进行压力测试。
Strong evaluation tasks might require multiple tool calls—potentially dozens.
强大的评测任务可能需要多次工具调用(tool calls)——可能多达数十次。
Here are some examples of strong tasks:
以下是一些强任务的示例:
Schedule a meeting with Jane next week to discuss our latest Acme Corp project.
安排下周与 Jane 开个会,讨论我们最新的 Acme Corp 项目。
Attach the notes from our last project planning meeting and reserve a conference room.
附上我们上次项目规划会议的笔记,并预订一间会议室。
Customer ID 9182 reported that they were charged three times for a single purchase attempt.
客户 ID 9182 报告称,他们在一次购买尝试中被扣款了三次。
Find all relevant log entries and determine if any other customers were affected by the same issue.
找出所有相关日志条目,并确定是否有其他客户受到同一问题的影响。
Customer Sarah Chen just submitted a cancellation request.
客户 Sarah Chen 刚刚提交了取消请求。
Prepare a retention offer.
准备一个挽留优惠。
Determine: (1) why they're leaving, (2) what retention offer would be most compelling, and (3) any risk factors we should be aware of before making an offer.
确定:(1) 他们为什么流失,(2) 什么样的挽留优惠最具吸引力,以及 (3) 在提出挽留优惠之前我们应注意的任何风险因素。
And here are some weaker tasks:
下面是一些较弱的任务:
Schedule a meeting with jane@acme.corp next week.
安排下周与 jane@acme.corp 开个会。
Search the payment logs for purchase_complete and customer_id=9182.
在支付日志中搜索 purchase_complete 和 customer_id=9182。
Find the cancellation request by Customer ID 45892.
按 Customer ID 45892 查找取消请求。
Each evaluation prompt should be paired with a verifiable response or outcome.
每个评测提示词都应配有一个可验证的响应或结果。
Your verifier can be as simple as an exact string comparison between ground truth and sampled responses, or as advanced as enlisting Claude to judge the response.
你的验证器(verifier)可以简单到对真实答案与采样响应进行精确字符串比较,也可以复杂到让 Claude 来评判响应。
Avoid overly strict verifiers that reject correct responses due to spurious differences like formatting, punctuation, or valid alternative phrasings.
避免使用过于严格的验证器,它们会因为格式、标点或合法的替代表述等无关差异而拒绝正确响应。
For each prompt-response pair, you can optionally also specify the tools you expect an agent to call in solving the task, to measure whether or not agents are successful in grasping each tool’s purpose during evaluation.
对于每个提示词-响应对,你也可以选择额外指定你期望智能体在解决任务时调用的工具,以衡量智能体在评测期间是否成功掌握每个工具的用途。
However, because there might be multiple valid paths to solving tasks correctly, try to avoid overspecifying or overfitting to strategies.
然而,因为正确解决任务可能存在多条有效路径,尽量避免过度指定或对策略过拟合。
Running the evaluation
运行评测
We recommend running your evaluation programmatically with direct LLM API calls.
我们建议通过直接的 LLM API 调用以编程方式运行你的评测。
Use simple agentic loops (while-loops wrapping alternating LLM API and tool calls): one loop for each evaluation task.
使用简单的智能体循环(用 while 循环包裹交替的 LLM API 和工具调用):每个评测任务一个循环。
Each evaluation agent should be given a single task prompt and your tools.
每个评测智能体应被给予单个任务提示词和你的工具。
In your evaluation agents’ system prompts, we recommend instructing agents to output not just structured response blocks (for verification), but also reasoning and feedback blocks.
在你的评测智能体的系统提示词中,我们建议指示智能体不仅输出结构化响应块(用于验证),还输出推理和反馈块。
Instructing agents to output these before tool call and response blocks may increase LLMs’ effective intelligence by triggering chain-of-thought (CoT) behaviors.
指示智能体在工具调用和响应块之前输出这些内容,可能会通过触发思维链(chain-of-thought, CoT)行为来提高 LLMs 的有效智能。
If you’re running your evaluation with Claude, you can turn on interleaved thinking for similar functionality “off-the-shelf”.
如果你用 Claude 运行评测,你可以打开交错思考(interleaved thinking)以获得类似的“开箱即用”功能。
This will help you probe why agents do or don’t call certain tools and highlight specific areas of improvement in tool descriptions and specs.
这将帮助你探究智能体为什么调用或不调用某些工具,并突出工具描述和规范中需要改进的具体领域。
As well as top-level accuracy, we recommend collecting other metrics like the total runtime of individual tool calls and tasks, the total number of tool calls, the total token consumption, and tool errors.
除了顶层准确率,我们还建议收集其他指标,例如单个工具调用和任务的总运行时间、工具调用的总数、总 token 消耗量以及工具错误。
Tracking tool calls can help reveal common workflows that agents pursue and offer some opportunities for tools to consolidate.
跟踪工具调用有助于揭示智能体追求的常见工作流,并为工具整合提供一些机会。

Held-out test set performance of our internal Asana tools
我们内部 Asana 工具的留出测试集性能
Analyzing results Agents are your helpful partners in spotting issues and providing feedback on everything from contradictory tool descriptions to inefficient tool implementations and confusing tool schemas.
分析结果:智能体是你发现问题的得力伙伴,能提供从矛盾的工具描述到低效的工具实现以及令人困惑的工具模式等各方面的反馈。
However, keep in mind that what agents omit in their feedback and responses can often be more important than what they include.
然而,请记住,智能体在反馈和响应中省略的内容往往比包含的内容更重要。
LLMs don’t always say what they mean.
LLM 并不总是说出它们的真实意思。
Observe where your agents get stumped or confused.
观察你的智能体在哪里卡住或困惑。
Read through your evaluation agents’ reasoning and feedback (or CoT) to identify rough edges.
通读你评测智能体的推理和反馈(或 CoT),以识别粗糙之处。
Review the raw transcripts (including tool calls and tool responses) to catch any behavior not explicitly described in the agent’s CoT.
审阅原始记录(包括工具调用和工具响应),以捕捉智能体 CoT 中未明确描述的任何行为。
Read between the lines; remember that your evaluation agents don’t necessarily know the correct answers and strategies.
读懂言外之意;记住,你的评测智能体不一定知道正确答案和策略。
Analyze your tool calling metrics.
分析你的工具调用指标。
Lots of redundant tool calls might suggest some rightsizing of pagination or token limit parameters is warranted; lots of tool errors for invalid parameters might suggest tools could use clearer descriptions or better examples.
大量冗余的工具调用可能表明有必要对分页或 token 限制参数进行适当调整;大量因无效参数导致的工具错误可能表明工具可以使用更清晰的描述或更好的示例。
When we launched Claude’s web search tool, we identified that Claude was needlessly appending 2025 to the tool’s query parameter, biasing search results and degrading performance (we steered Claude in the right direction by improving the tool description).
当我们推出 Claude 的网页搜索工具时,我们发现 Claude 不必要地将 2025 附加到工具的 query 参数后,使搜索结果产生偏差并降低性能(我们通过改进工具描述将 Claude 引导到了正确方向)。
You can even let agents analyze your results and improve your tools for you.
你甚至可以让智能体分析你的结果,并为你改进工具。
Simply concatenate the transcripts from your evaluation agents and paste them into Claude Code.
只需将评测智能体的转录记录拼接起来,粘贴到 Claude Code 中。
Claude is an expert at analyzing transcripts and refactoring lots of tools all at once—for example, to ensure tool implementations and descriptions remain self-consistent when new changes are made.
Claude 擅长分析转录记录并一次性重构大量工具——例如,确保在进行新更改时,工具实现与描述保持自洽。
In fact, most of the advice in this post came from repeatedly optimizing our internal tool implementations with Claude Code.
事实上,本文中的大部分建议都来自我们使用 Claude Code 反复优化内部工具实现的过程。
Our evaluations were created on top of our internal workspace, mirroring the complexity of our internal workflows, including real projects, documents, and messages.
我们的评测建立在我们内部工作区之上,模拟了我们内部工作流的复杂性,包括真实项目、文档和消息。
We relied on held-out test sets to ensure we did not overfit to our “training” evaluations.
我们依赖留出测试集来确保我们没有对「训练」评测过拟合。
These test sets revealed that we could extract additional performance improvements even beyond what we achieved with "expert" tool implementations—whether those tools were manually written by our researchers or generated by Claude itself.
这些测试集表明,我们还能获得额外的性能提升,甚至超过我们通过「专家」工具实现所达到的水平——无论这些工具是由我们的研究人员手动编写,还是由 Claude 本身生成的。
In the next section, we’ll share some of what we learned from this process.
在下一节中,我们将分享从这一过程中学到的一些内容。
In this section, we distill our learnings into a few guiding principles for writing effective tools.
在本节中,我们将把所学提炼成几条编写有效工具的指导原则。
More tools don’t always lead to better outcomes.
更多工具并不总能带来更好的结果。
A common error we’ve observed is tools that merely wrap existing software functionality or API endpoints—whether or not the tools are appropriate for agents.
我们观察到的一个常见错误是,工具仅仅封装现有的软件功能或 API 端点——而不考虑这些工具是否适合智能体。
This is because agents have distinct “affordances” to traditional software—that is, they have different ways of perceiving the potential actions they can take with those tools
这是因为智能体与传统软件具有不同的「可供性(affordance)」——也就是说,它们感知自己能用这些工具采取的潜在行动的方式不同。
LLM agents have limited "context" (that is, there are limits to how much information they can process at once), whereas computer memory is cheap and abundant.
LLM 智能体的「上下文(context)」有限(也就是说,它们一次能处理的信息量有上限),而计算机内存既便宜又充裕。
Consider the task of searching for a contact in an address book.
设想在通讯录中查找联系人的任务。
Traditional software programs can efficiently store and process a list of contacts one at a time, checking each one before moving on.
传统软件程序可以高效地存储并逐个处理联系人列表,检查完一个再继续下一个。
However, if an LLM agent uses a tool that returns ALL contacts and then has to read through each one token-by-token, it's wasting its limited context space on irrelevant information (imagine searching for a contact in your address book by reading each page from top-to-bottom—that is, via brute-force search).
然而,如果 LLM 智能体使用的工具(tool)返回全部联系人,然后必须逐个 token 读完每一个,它就把有限的上下文空间浪费在无关信息上(想象一下,你在通讯录里查找联系人时,从上到下逐页阅读——也就是暴力搜索)。
The better and more natural approach (for agents and humans alike) is to skip to the relevant page first (perhaps finding it alphabetically).
更好、也更自然的做法(对智能体和人类都一样)是先跳到相关页面(也许按字母顺序找到它)。
We recommend building a few thoughtful tools targeting specific high-impact workflows, which match your evaluation tasks and scaling up from there.
我们建议先针对特定的高影响力工作流构建少量经过深思熟虑的工具,使其与你评测任务相匹配,再从这里逐步扩展。
In the address book case, you might choose to implement a search_contacts or message_contact tool instead of a list_contacts tool.
在通讯录这个例子里,你可以选择实现 search_contacts 或 message_contact 工具,而不是 list_contacts 工具。
Tools can consolidate functionality, handling potentially multiple discrete operations (or API calls) under the hood.
工具可以整合功能,在底层处理可能多个彼此独立的操作(或 API 调用)。
For example, tools can enrich tool responses with related metadata or handle frequently chained, multi-step tasks in a single tool call.
例如,工具可以用相关元数据充实工具响应,或在单次工具调用中处理经常串联的多步任务。
Here are some examples:
以下是一些示例:
Instead of implementing a list_users, list_events, and create_event tools, consider implementing a schedule_event tool which finds availability and schedules an event.
与其实现 list_users、list_events 和 create_event 工具,不如考虑实现一个 schedule_event 工具,由它查找可用时间并安排事件。
Instead of implementing a read_logs tool, consider implementing a search_logs tool which only returns relevant log lines and some surrounding context.
与其实现一个 read_logs 工具,不如考虑实现一个 search_logs 工具,它只返回相关的日志行和一些周围的上下文。
Instead of implementing get_customer_by_id, list_transactions, and list_notes tools, implement a get_customer_context tool which compiles all of a customer’s recent & relevant information all at once.
与其实现 get_customer_by_id、list_transactions 和 list_notes 工具,不如实现一个 get_customer_context 工具,它一次性汇总客户所有近期且相关的信息。
Make sure each tool you build has a clear, distinct purpose.
确保你构建的每个工具都有清晰、独特的目的。
Tools should enable agents to subdivide and solve tasks in much the same way that a human would, given access to the same underlying resources, and simultaneously reduce the context that would have otherwise been consumed by intermediate outputs.
工具应当使智能体能够像人类在获得相同底层资源时那样对任务进行细分和解决,同时减少原本会被中间输出消耗的上下文。
Too many tools or overlapping tools can also distract agents from pursuing efficient strategies.
太多工具或重叠的工具也可能分散智能体追求高效策略的注意力。
Careful, selective planning of the tools you build (or don’t build) can really pay off.
对你构建(或不构建)的工具进行仔细、有选择性的规划确实能带来回报。
Your AI agents will potentially gain access to dozens of MCP servers and hundreds of different tools–including those by other developers.
你的 AI 智能体可能获得对数十个 MCP 服务器和数百个不同工具(包括其他开发者提供的工具)的访问权限。
When tools overlap in function or have a vague purpose, agents can get confused about which ones to use.
当工具在功能上重叠或目的模糊时,智能体会困惑于该使用哪些工具。
Namespacing (grouping related tools under common prefixes) can help delineate boundaries between lots of tools; MCP clients sometimes do this by default.
命名空间(namespacing,将相关工具分组在共同前缀下)可以帮助划定大量工具之间的边界;MCP 客户端有时会默认这样做。
For example, namespacing tools by service (e.g., asana_search, jira_search) and by resource (e.g., asana_projects_search, asana_users_search), can help agents select the right tools at the right time.
例如,按服务(如 asana_search、jira_search)和按资源(如 asana_projects_search、asana_users_search)对工具进行命名空间划分,可以帮助智能体在正确的时间选择正确的工具。
We have found selecting between prefix- and suffix-based namespacing to have non-trivial effects on our tool-use evaluations.
我们发现,在基于前缀和基于后缀的 namespacing 之间做选择,会对我们的工具调用评测产生不小的影响。
Effects vary by LLM and we encourage you to choose a naming scheme according to your own evaluations.
影响因 LLM 而异,我们鼓励你根据自己的评测来选择命名方案。
Agents might call the wrong tools, call the right tools with the wrong parameters, call too few tools, or process tool responses incorrectly.
智能体可能调用错误的工具、用错误的参数调用正确的工具、调用的工具过少,或错误地处理工具响应。
By selectively implementing tools whose names reflect natural subdivisions of tasks, you simultaneously reduce the number of tools and tool descriptions loaded into the agent’s context and offload agentic computation from the agent’s context back into the tool calls themselves.
通过有选择地实现名称反映任务自然细分的工具,你同时减少了加载到智能体上下文中的工具和工具描述数量,并将智能体计算从智能体的上下文卸载回工具调用本身。
This reduces an agent’s overall risk of making mistakes.
这降低了智能体犯错的总风险。
In the same vein, tool implementations should take care to return only high signal information back to agents.
同样,工具实现应注意只向智能体返回高信号的信息。
They should prioritize contextual relevance over flexibility, and eschew low-level technical identifiers (for example: uuid, 256px_image_url, mime_type).
它们应优先考虑上下文相关性而非灵活性,并避免使用低层技术标识符(例如:uuid、256px_image_url、mime_type)。
Fields like name, image_url, and file_type are much more likely to directly inform agents’ downstream actions and responses.
像 name、image_url 和 file_type 这样的字段更有可能直接为智能体的下游行动和响应提供信息。
Agents also tend to grapple with natural language names, terms, or identifiers significantly more successfully than they do with cryptic identifiers.
智能体处理自然语言名称、术语或标识符时,往往比处理晦涩的标识符成功得多。
We’ve found that merely resolving arbitrary alphanumeric UUIDs to more semantically meaningful and interpretable language (or even a 0-indexed ID scheme) significantly improves Claude’s precision in retrieval tasks by reducing hallucinations.
我们发现,仅将任意的字母数字 UUID 解析为语义上更有意义、更可解释的语言(甚至只是 0 索引的 ID 方案),就能通过减少幻觉显著提高 Claude 在检索任务中的精确度。
In some instances, agents may require the flexibility to interact with both natural language and technical identifiers outputs, if only to trigger downstream tool calls (for example, search_user(name=’jane’) → send_message(id=12345)).
在某些情况下,智能体可能需要灵活性,以便同时与自然语言和技术标识符输出交互,哪怕只是为了触发下游工具调用(例如,search_user(name=’jane’) → send_message(id=12345))。
You can enable both by exposing a simple response_format enum parameter in your tool, allowing your agent to control whether tools return “concise” or “detailed” responses (images below).
你可以通过在工具中暴露一个简单的 response_format 枚举参数来同时启用两者,让智能体控制工具返回 “concise” 还是 “detailed” 响应(见下图)。
You can add more formats for even greater flexibility, similar to GraphQL where you can choose exactly which pieces of information you want to receive.
你可以添加更多格式以获得更大的灵活性,类似于 GraphQL,你可以精确选择想要接收哪些信息。
Here is an example ResponseFormat enum to control tool response verbosity:
下面是一个用于控制工具响应详细程度的 ResponseFormat 枚举示例:
enum ResponseFormat {
   DETAILED = "detailed",
   CONCISE = "concise"
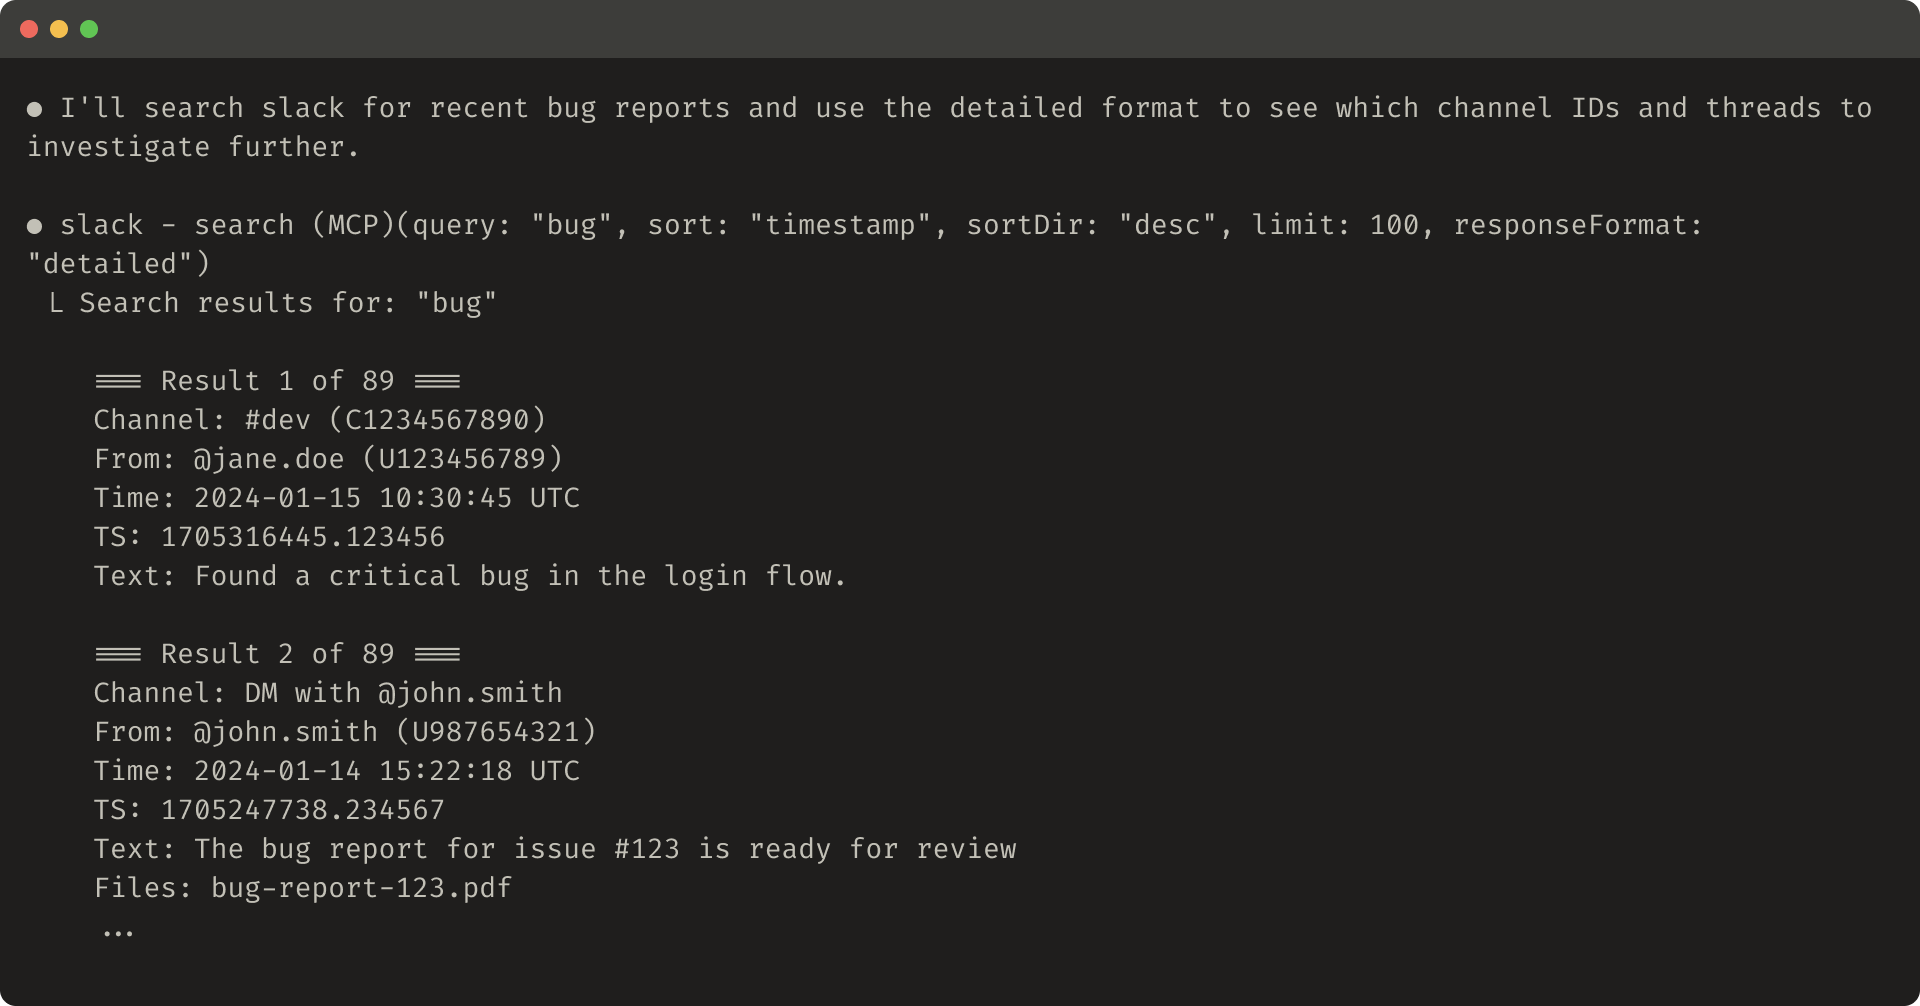
}Here’s an example of a detailed tool response (206 tokens):
这是一个详细工具响应的示例(206 个 token):
Here’s an example of a concise tool response (72 tokens):
这是一个简洁工具响应的示例(72 个 token):
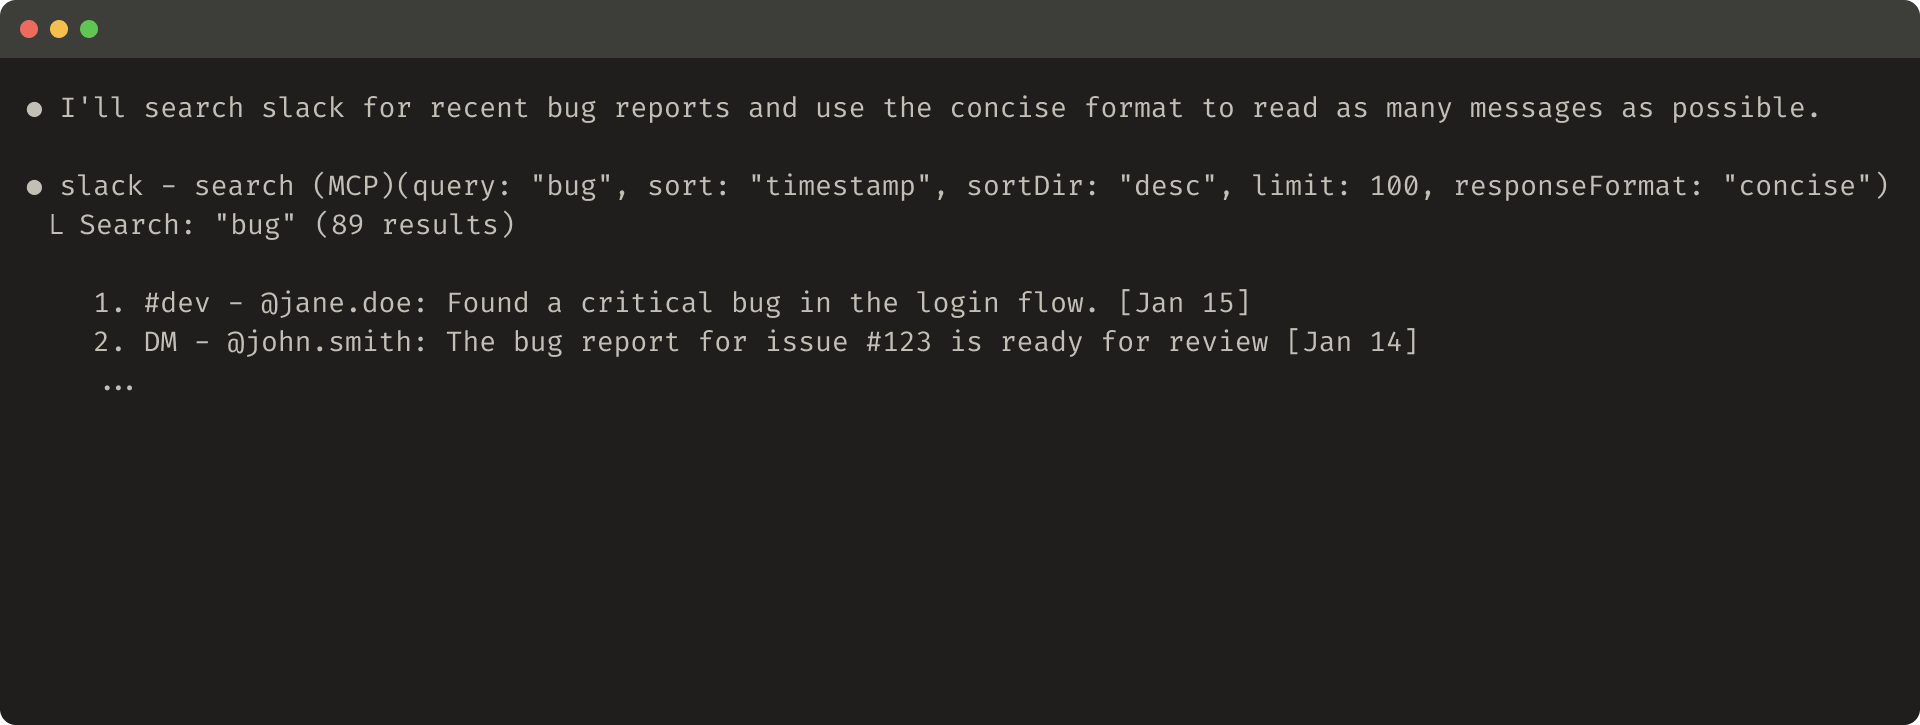
Slack threads and thread replies are identified by unique thread_ts which are required to fetch thread replies. thread_ts and other IDs (channel_id, user_id) can be retrieved from a “detailed” tool response to enable further tool calls that require these. “concise” tool responses return only thread content and exclude IDs.
Slack 线程和线程回复由唯一的 thread_ts 标识,获取线程回复需要它。可以从 “detailed” 工具响应中检索 thread_ts 和其他 ID(channel_id、user_id),以便启用需要这些 ID 的进一步工具调用。“concise” 工具响应只返回线程内容,并排除 ID。
In this example, we use ~⅓ of the tokens with “concise” tool responses.
在这个示例中,使用 “concise” 工具响应时,我们只用了约 ⅓ 的 token。
Even your tool response structure—for example XML, JSON, or Markdown—can have an impact on evaluation performance: there is no one-size-fits-all solution.
甚至你的工具响应结构——例如 XML、JSON 或 Markdown——也会影响评测表现:不存在放之四海而皆准的解决方案。
This is because LLMs are trained on next-token prediction and tend to perform better with formats that match their training data.
这是因为 LLM 基于下一 token 预测进行训练,并且往往在与其训练数据匹配的格式上表现更好。
The optimal response structure will vary widely by task and agent.
最优响应结构会因任务和智能体而有很大差异。
We encourage you to select the best response structure based on your own evaluation.
我们鼓励你根据自己的评测选择最佳响应结构。
Optimizing the quality of context is important.
优化上下文的质量很重要。
But so is optimizing the quantity of context returned back to agents in tool responses.
但优化工具响应中返回给智能体的上下文数量同样重要。
We suggest implementing some combination of pagination, range selection, filtering, and/or truncation with sensible default parameter values for any tool responses that could use up lots of context.
我们建议,对于任何可能消耗大量上下文的工具响应,实现分页、范围选择、过滤和/或截断的某种组合,并设置合理的默认参数值。
For Claude Code, we restrict tool responses to 25,000 tokens by default.
对于 Claude Code,我们默认将工具响应限制为 25,000 个 token。
We expect the effective context length of agents to grow over time, but the need for context-efficient tools to remain.
我们预计智能体的有效上下文长度会随时间增长,但对上下文高效工具的需求仍将存在。
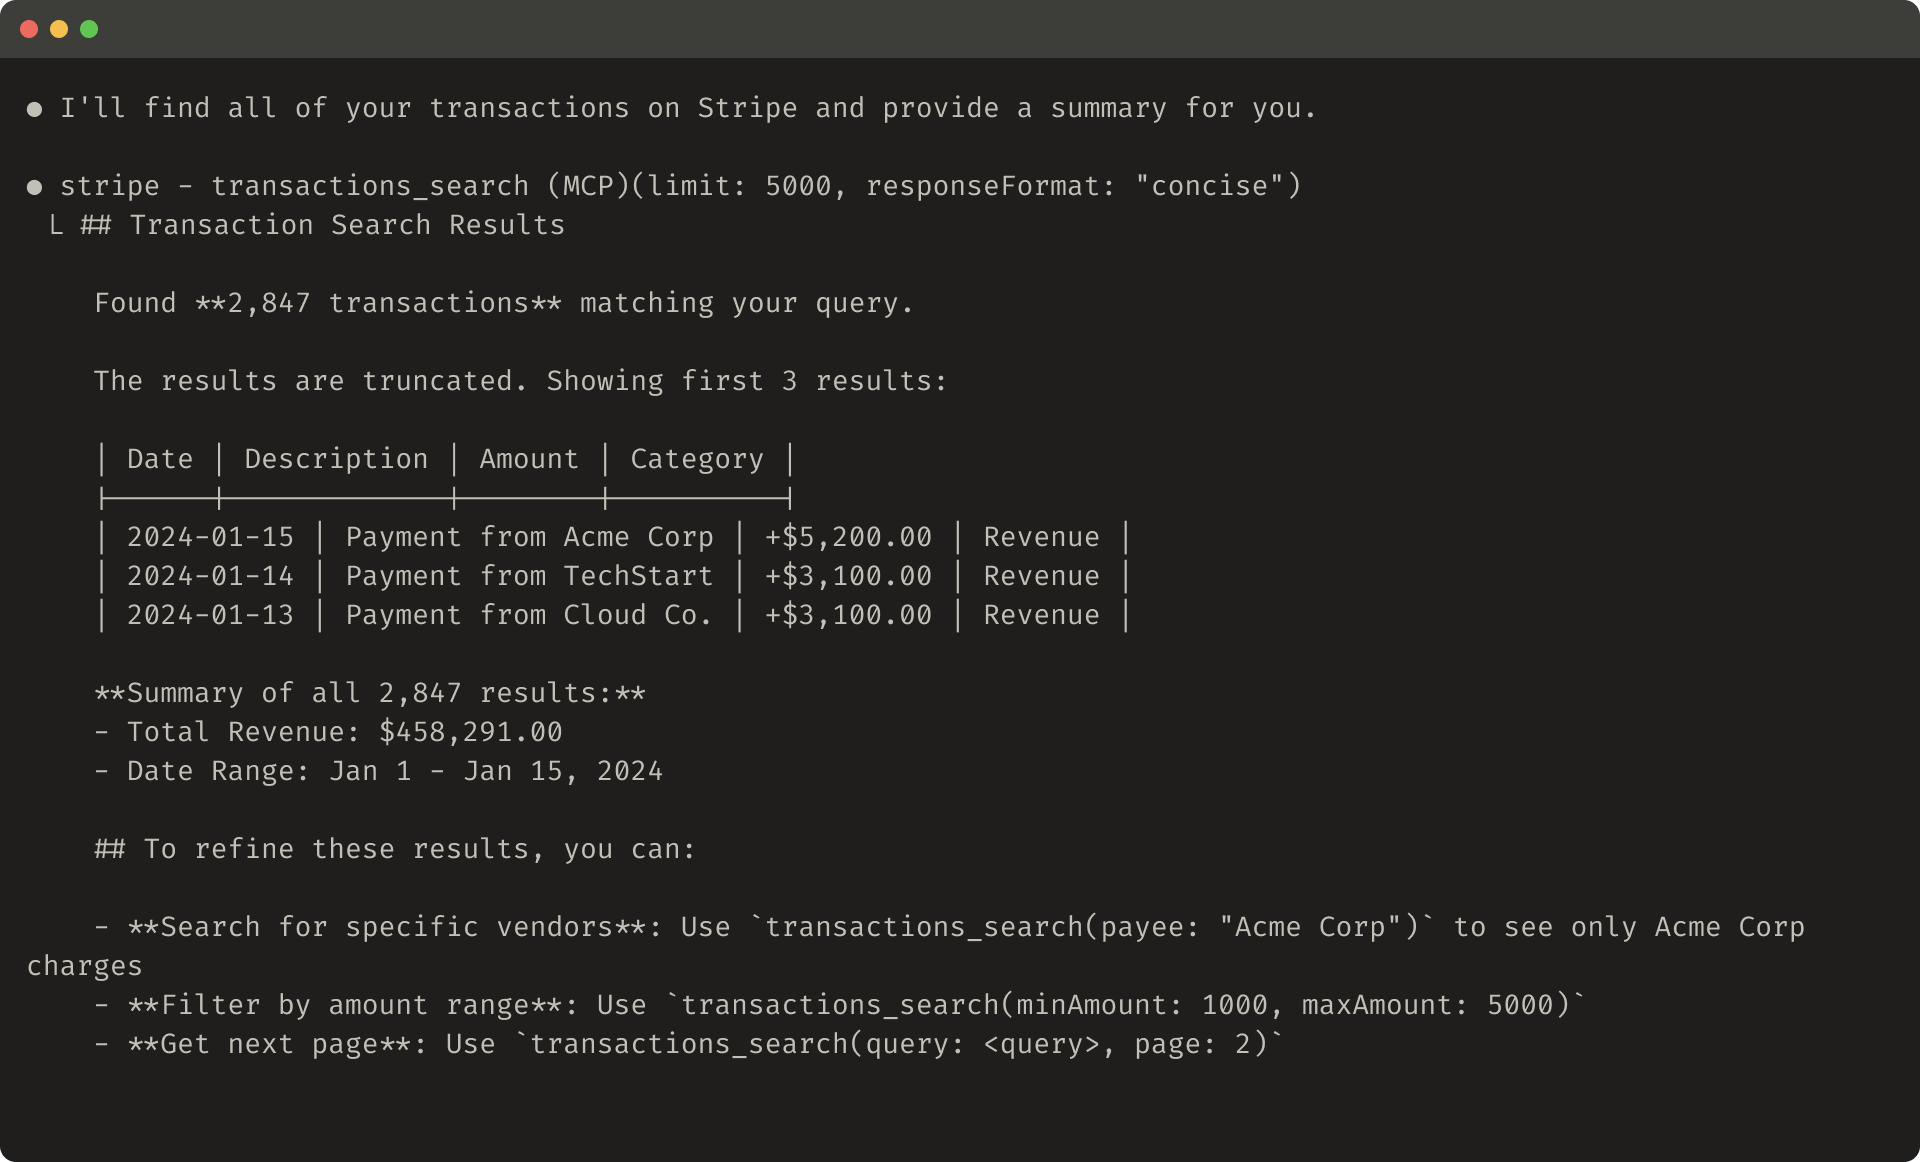
If you choose to truncate responses, be sure to steer agents with helpful instructions.
如果你选择截断响应,一定要用有帮助的指令来引导智能体。
You can directly encourage agents to pursue more token-efficient strategies, like making many small and targeted searches instead of a single, broad search for a knowledge retrieval task.
你可以直接鼓励智能体采用更省 token 的策略,例如对于知识检索任务,进行多次小型且有针对性的搜索,而不是一次宽泛的搜索。
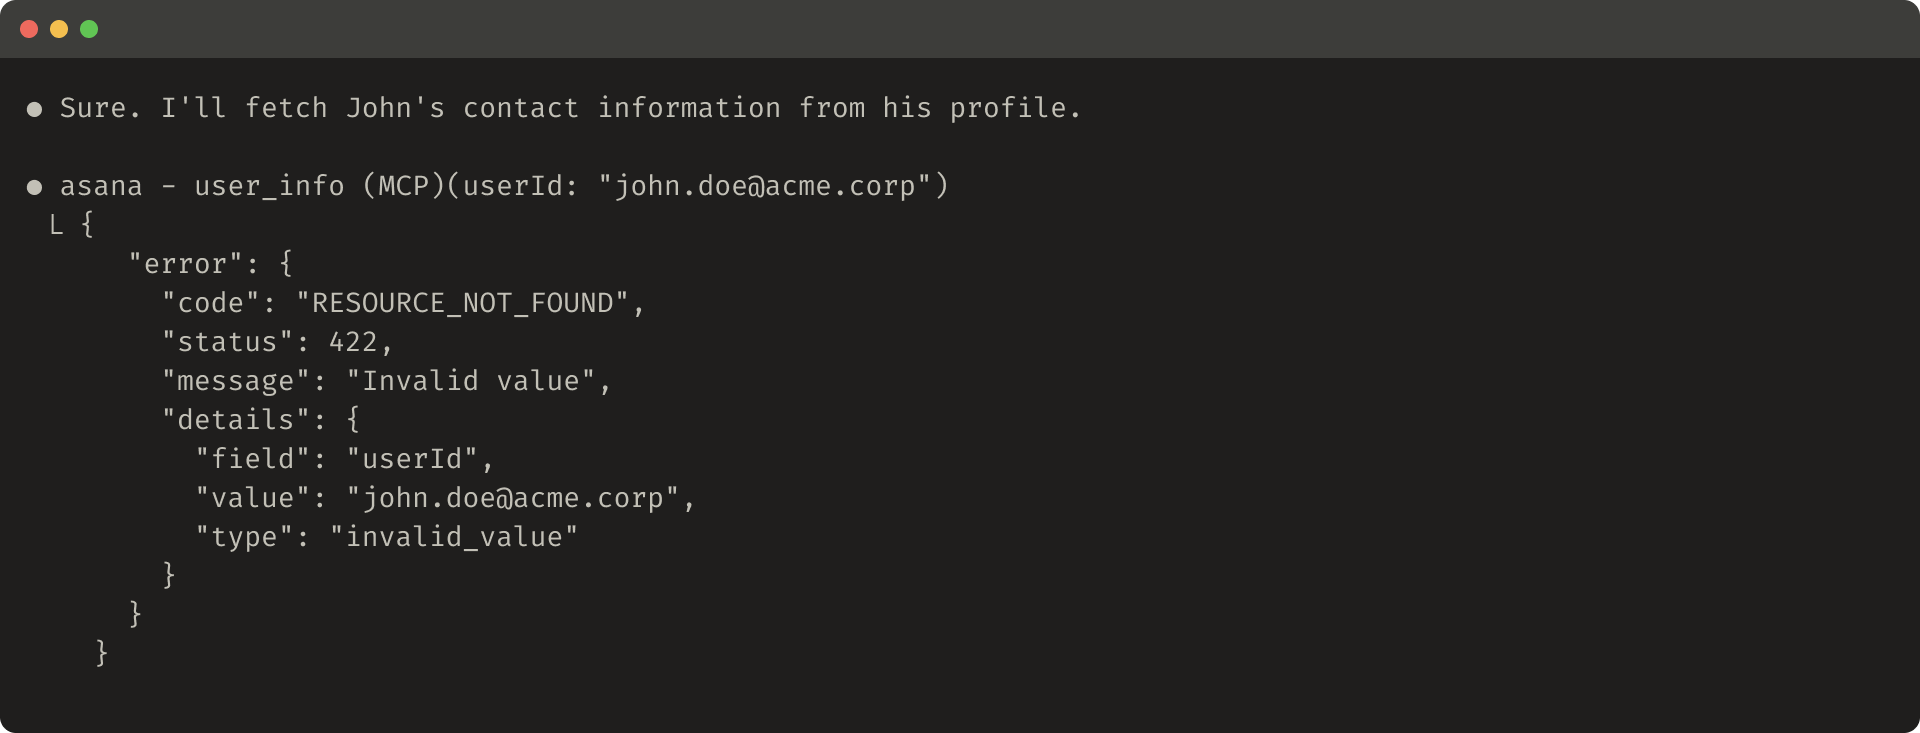
Similarly, if a tool call raises an error (for example, during input validation), you can prompt-engineer your error responses to clearly communicate specific and actionable improvements, rather than opaque error codes or tracebacks.
类似地,如果工具调用抛出错误(例如在输入验证期间),你可以对错误响应进行提示词工程,以清晰传达具体且可操作的改进方向,而不是不透明的错误码或回溯信息。
Here’s an example of a truncated tool response:
以下是一个截断的工具响应示例:
Here’s an example of an unhelpful error response:
以下是一个无帮助的错误响应示例:
Here’s an example of a helpful error response:
以下是一个有帮助的错误响应示例:

Tool truncation and error responses can steer agents towards more token-efficient tool-use behaviors (using filters or pagination) or give examples of correctly formatted tool inputs.
工具截断和错误响应可以引导智能体采取更省 token 的工具使用行为(使用过滤器或分页),或者给出格式正确的工具输入示例。
We now come to one of the most effective methods for improving tools: prompt-engineering your tool descriptions and specs.
现在我们来到改进工具最有效的方法之一:对你的工具描述和规格进行提示词工程。
Because these are loaded into your agents’ context, they can collectively steer agents toward effective tool-calling behaviors.
因为这些内容会被加载到你的智能体的上下文中,它们可以共同引导智能体采取有效的工具调用行为。
When writing tool descriptions and specs, think of how you would describe your tool to a new hire on your team.
在编写工具描述和规格时,想想你会如何向你团队中新加入的成员描述你的工具。
Consider the context that you might implicitly bring—specialized query formats, definitions of niche terminology, relationships between underlying resources—and make it explicit.
考虑你可能会隐含带入的上下文——专用查询格式、小众术语的定义、底层资源之间的关系——并把它们明确表达出来。
Avoid ambiguity by clearly describing (and enforcing with strict data models) expected inputs and outputs.
通过清晰描述(并用严格数据模型强制约束)预期的输入和输出,避免歧义。
In particular, input parameters should be unambiguously named: instead of a parameter named user, try a parameter named user_id.
特别是,输入参数应命名得无歧义:不要用名为 user 的参数,而应试试名为 user_id 的参数。
With your evaluation you can measure the impact of your prompt engineering with greater confidence.
有了你的评测,你可以更有信心地衡量提示词工程带来的影响。
Even small refinements to tool descriptions can yield dramatic improvements.
即使对工具描述做很小的改进,也可能带来显著提升。
Claude Sonnet 3.5 achieved state-of-the-art performance on the SWE-bench Verified evaluation after we made precise refinements to tool descriptions, dramatically reducing error rates and improving task completion.
在我们对工具描述做出精确改进后,Claude Sonnet 3.5 在 SWE-bench Verified 评测上达到了最先进的性能,大幅降低了错误率并提高了任务完成率。
You can find other best practices for tool definitions in our Developer Guide.
你可以在我们的 Developer Guide 中找到工具定义的其他最佳实践。
If you’re building tools for Claude, we also recommend reading about how tools are dynamically loaded into Claude’s system prompt.
如果你正在为 Claude 构建工具,我们还建议阅读工具是如何动态加载到 Claude 的系统提示词中的。
Lastly, if you’re writing tools for an MCP server, tool annotations help disclose which tools require open-world access or make destructive changes.
最后,如果你正在为 MCP 服务器编写工具,工具注解有助于说明哪些工具需要开放世界访问,或会做出破坏性更改。
To build effective tools for agents, we need to re-orient our software development practices from predictable, deterministic patterns to non-deterministic ones.
要为智能体构建有效的工具,我们需要重新调整软件开发实践,从可预测、确定性的模式转向非确定性的模式。
Through the iterative, evaluation-driven process we’ve described in this post, we've identified consistent patterns in what makes tools successful: Effective tools are intentionally and clearly defined, use agent context judiciously, can be combined together in diverse workflows, and enable agents to intuitively solve real-world tasks.
通过我们在本文中描述的迭代式、评测驱动的流程,我们识别出了工具成功背后的一致模式:有效的工具被有意且清晰地定义,审慎地使用智能体上下文,能够在多样工作流中组合在一起,并使智能体能直观地解决现实世界任务。
In the future, we expect the specific mechanisms through which agents interact with the world to evolve—from updates to the MCP protocol to upgrades to the underlying LLMs themselves.
未来,我们预计智能体与世界交互的具体机制会演进——从 MCP 协议更新到底层 LLM 本身的升级。
With a systematic, evaluation-driven approach to improving tools for agents, we can ensure that as agents become more capable, the tools they use will evolve alongside them.
通过系统化、评测驱动的方法改进智能体的工具,我们可以确保随着智能体能力增强,它们使用的工具也会随之演进。
Written by Ken Aizawa with valuable contributions from colleagues across Research (Barry Zhang, Zachary Witten, Daniel Jiang, Sami Al-Sheikh, Matt Bell, Maggie Vo), MCP (Theodora Chu, John Welsh, David Soria Parra, Adam Jones), Product Engineering (Santiago Seira), Marketing (Molly Vorwerck), Design (Drew Roper), and Applied AI (Christian Ryan, Alexander Bricken).
作者 Ken Aizawa,并得到来自 Research(Barry Zhang、Zachary Witten、Daniel Jiang、Sami Al-Sheikh、Matt Bell、Maggie Vo)、MCP(Theodora Chu、John Welsh、David Soria Parra、Adam Jones)、Product Engineering(Santiago Seira)、Marketing(Molly Vorwerck)、Design(Drew Roper)以及 Applied AI(Christian Ryan、Alexander Bricken)等各团队同事的宝贵贡献。
1Beyond training the underlying LLMs themselves.
1超越对底层 LLM 本身的训练。