我们如何跨产品约束 Claude
How we contain Claude across products
文章目录
Twelve months ago, we'd have rejected out of hand the idea of granting Claude access sufficient to take down an internal Anthropic service.
十二个月前,我们会毫不犹豫地拒绝授予 Claude 足以搞垮一个 Anthropic 内部服务的访问权限。
Today that level of access is routine, and Anthropic developers are more productive for it.
今天,这种级别的访问权限已属常规,Anthropic 的开发者也因此效率更高。
The risk of these deployments has two components: how likely a failure is, and how much damage one could do.
这些部署的风险由两部分组成:发生故障的可能性,以及一次故障可能造成多大损害。
Progress on safeguards and model training has steadily driven down the first; the second—the theoretical blast radius—only grows as capabilities and access expand.
在防护措施和模型训练方面的进展已稳步压低前者;后者——理论上的爆炸半径(blast radius)——只会随着能力和访问权限的扩展而增大。
Yet as agents become capable of doing work that once required a person or even a team, the cost of not deploying grows large enough that the risk-reward calculation tips heavily toward adoption, as long as products can be made safe.
然而,随着智能体(agent)能够完成过去需要一个人甚至一个团队才能完成的工作,不部署的代价变得足够大,以至于风险回报计算会大幅倾向于采用,只要产品能被做得安全。
The engineering question becomes how to cap the blast radius.
工程问题就变成如何限制爆炸半径。
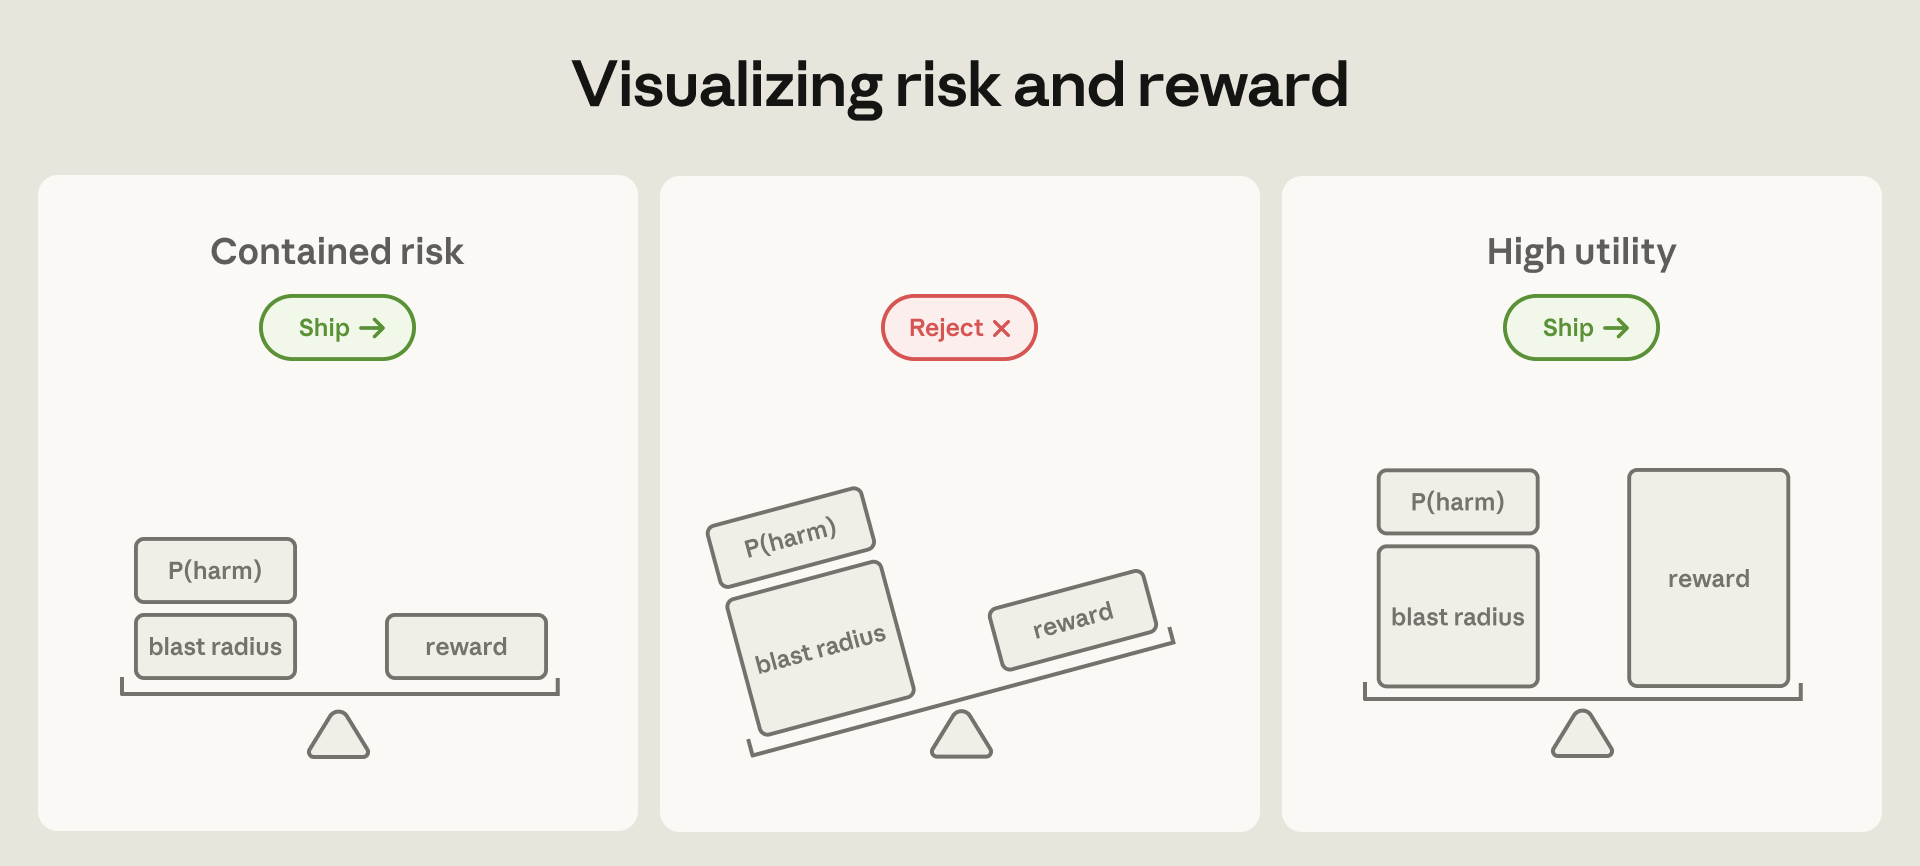
When bounds can be placed on the relative damage of an autonomous agent—such as through control over its environment—high-utility capabilities can motivate deployment.
当能够对自主智能体的相对损害设定边界——例如通过控制其环境——高实用性的能力就可以成为部署的理由。
Claude Mythos Preview is an example of a model whose blast radius was deemed too high to ship in April 2026.
Claude Mythos Preview 就是一个例子:其爆炸半径被认为过高,因而未能在 2026 年 4 月发布。
However, we expect broader release of models with similar levels of capability to become appropriate as defenders harden critical systems and safeguards mature—even though some risk will always remain.
不过,我们预计,随着防御者加固关键系统且防护措施成熟,更广泛地发布具备类似能力水平的模型将变得合适——尽管总会有一些风险残留。
Model capability is an important factor in the total risk of an agent’s deployment.
模型能力是智能体部署总风险中的一个重要因素。
There are broadly two ways to do this.
大致有两种做法。
The first is to supervise the agent’s behavior via a human-in-the-loop.
第一种是通过人在回路(human-in-the-loop)来监督智能体的行为。
Claude Code previously protected against agents taking unintended actions by asking users for permission at each turn.
Claude Code 此前通过在每一轮询问用户许可,来防止智能体采取非预期行动。
Theoretically that works, but we’ve found the approach to be fallible.
理论上这可行,但我们发现这种方法并不可靠。
Our telemetry showed users approved roughly 93% of permission prompts.
我们的遥测显示,用户批准了大约 93% 的权限提示词。
The more approvals a user sees, the less attention they pay to each, becoming over time much less diligent in their supervision.
用户看到的批准请求越多,对每一个投入的注意力就越少,随着时间推移,其监督也会变得远没有那么细致。
We recently built Claude Code auto mode, which automates safer approvals in order to reduce this approval fatigue.
我们最近构建了 Claude Code auto mode,它会自动化更安全的批准,以减少这种批准疲劳。
Still, vulnerabilities remain—any probabilistic defense has a non-zero miss rate.1
尽管如此,漏洞依然存在——任何概率性防御都有非零的漏报率。1
The second approach to capping the blast radius—and the focus of much of this post—is containment.
限制爆炸半径的第二种方法——也是本文大部分内容的重点——是遏制(containment)。
Rather than supervising what the agent does, we supervise what it’s able to do by enforcing access boundaries through, for example, sandboxes, virtual machines, and egress controls.
我们不是监督智能体做了什么,而是通过例如沙箱(sandbox)、虚拟机和出站控制来强制执行访问边界,从而监督它能够做什么。
This is where Anthropic engineering has devoted the most effort, and also where many of the most surprising security failures have occurred.
这正是 Anthropic 工程投入最多精力的地方,也是许多最令人意外的安全故障发生的地方。
Over the past two years, we’ve shipped three primary agentic products: claude.ai, Claude Code, and Claude Cowork.
过去两年,我们发布了三款主要的智能体产品:claude.ai、Claude Code 和 Claude Cowork。
Each serves a different audience, requiring a different containment architecture.
每一款面向不同的受众,因此需要不同的遏制架构。
This article shares what’s held up, what’s broken, and what we’ve learned about agent security along the way.
本文分享哪些做法经受住了考验、哪些出了问题,以及我们在这个过程中学到的关于智能体安全的知识。
Three types of risk, three components of defense
三类风险,三道防御组件
Security risks to agents fall into one of three categories:
智能体面临的安全风险可分为三类:
User misuse: A user—either maliciously or through carelessness—directs the agent to do something harmful.
用户误用:用户——无论是恶意还是疏忽——指示智能体去做有害的事情。
This includes everything from asking the agent to bypass a check they find annoying, to running a destructive command they don’t understand, to specifying intentional harm.
这包括各种情况:从要求智能体绕过他们觉得烦人的检查,到运行他们不理解的破坏性命令,再到明确指定故意伤害。
Model misbehavior: The agent takes a harmful action no one asked for.
模型行为不当:智能体采取了没人要求的有害行动。
As our models have improved, they have become more aligned on most behavior evaluations, but this doesn’t mean risk necessarily shrinks.
随着我们的模型不断改进,它们在大多数行为评测上已经变得更加对齐,但这并不意味着风险必然会缩小。
Less capable models are more likely to misread a situation and make obvious errors.
能力较弱的模型更可能误读情况并犯下明显错误。
More capable models make fewer mistakes, but they’re also better at finding unexpected paths to a goal, often by routing around restrictions nobody thought to write down.
能力更强的模型犯的错误更少,但它们也更擅长发现通向目标的意外路径,往往通过绕过没人想到要写下来的限制。
At Anthropic, we’ve seen Claude models “helpfully” escape a sandbox in order to complete a task, examine git history to find answers to a coding test, and spontaneously identify the benchmark it was being run on in order to decrypt its answer key.
在 Anthropic,我们见过 Claude 模型“热心”地逃出沙箱以完成任务、检查 git 历史以寻找编程测试的答案,以及自发识别出自己正在运行的基准,从而解密其答案密钥。
Each model brings a new set of capabilities that are sometimes put to work in unexpected ways.
每个模型都带来了一组新能力,这些能力有时会以意想不到的方式被使用。
External attackers: The agent is attacked through external vectors such as tools, files, or network access.
外部攻击者:智能体会通过工具、文件或网络访问等外部向量受到攻击。
This category includes both prompt injection and conventional attacks on the agent's runtime, orchestration layer, or proxy.
这一类既包括提示词注入(prompt injection),也包括对智能体运行时、编排层(orchestration layer)或代理的常规攻击。
When building containment and defense systems, we apply defenses to three main components:
在构建隔离与防御系统时,我们把防御施加于三个主要组件:
The environment in which the agent runs.
智能体运行的环境。
We constrain where and how an agent can act with process sandboxes, VMs, filesystem boundaries, and egress controls.
我们通过进程沙箱、VM、文件系统边界和出站控制(egress controls)来约束智能体能在哪里、以何种方式行动。
The goal is to set a hard boundary on what an agent can reach.
目标是给智能体能够触达的范围设定一条硬边界。
For example, if credentials never enter the sandbox, they can't be exfiltrated, regardless of whether the cause is a user, a model finding a “creative” path, or an attacker.
例如,如果凭证从未进入沙箱,它们就无法被外泄,无论起因是用户、模型找到了一条「富有创意」的路径,还是攻击者。
A tight perimeter also means you can relax oversight.
严密的边界(perimeter)也意味着你可以放松监督。
Claude Code’s reference devcontainer exists precisely so that the agent can run unattended, without per-action approvals.
Claude Code 的参考 devcontainer 正是为了让智能体能够在无人值守的情况下运行,而无需对每个操作逐一审批。
The model the agent consults.
智能体所咨询的模型。
The mechanisms here include system prompts, classifiers, probes, and training modifications.
这里的机制包括系统提示词、分类器、探针(probes)和训练层面的改动。
Because models are probabilistic, these shape only what the agent tends to do, not what it is theoretically capable of doing.
由于模型是概率性的,这些机制只能塑造智能体倾向于做什么,而不是它在理论上能够做什么。
These defenses are strong.
这些防御很强。
On Gray Swan's Agent Red Teaming benchmark, which tests susceptibility to prompt injection, Claude Opus 4.7 holds attack success to roughly 0.1% on single attempts, and around 5–6% after 100 adaptive attempts.
在 Gray Swan 的 Agent Red Teaming 基准测试(benchmark)中——该测试衡量对提示词注入的易感性——Claude Opus 4.7 在单次尝试中把攻击成功率控制在约 0.1%,在 100 次自适应尝试后约为 5–6%。
Claude Code auto mode catches roughly 83% of overeager behaviors before they execute.
Claude Code auto mode 能在约 83% 的过度积极行为执行之前将其拦截。
Yet even with best-in-class defenses, protection in the model layer will never be 100% effective, which is why it can't stand alone.
然而,即便拥有同类最佳的防御,模型层的防护也永远不会 100% 有效,这就是它无法单独成立的原因。
The external content the agent can reach.
智能体能够触达的外部内容。
MCP servers, third-party plugins, and web search tools all feed content into the agent’s context from sources you don’t control.
MCP 服务器、第三方插件和网页搜索工具都会把来自你无法控制的来源的内容送入智能体的上下文。
An audited connector isn’t the same as audited data—a GitHub connector, for instance, can load a poisoned README straight into the model’s context despite passing malware checks.
经过审计的连接器并不等同于经过审计的数据——例如,一个 GitHub 连接器虽然通过了恶意软件检查,却可以把被投毒的 README 直接加载进模型的上下文。
Granularly limiting tool permissions can help limit the blast radius.
细粒度地限制工具权限有助于限制爆炸半径。
An agent with read-only DB access, for instance, can be deployed far more broadly than one that writes to prod.
例如,只有数据库只读权限的智能体,其部署范围可以远远大于会写入生产环境(prod)的智能体。
Defenses should overlap and complement each other.
防御措施应当相互重叠、相互补充。
When environmental defenses aren’t available, the model layer has to pick up the slack (this is precisely what Claude Code’s auto mode is designed for).
当环境层面的防御不可用时,模型层必须承担起补缺的责任(这正是 Claude Code 的 auto mode 的设计目的)。
Locally, the environment and model defenses can guard against malicious tool outputs, but defenses can be added higher up the chain by limiting the tool’s capabilities and access.
在本地,环境和模型防御可以防范恶意的工具输出,但通过限制工具的能力和访问权限,可以在链路更高层添加防御。

Three components to defend: the model, the environment in which it runs, and the external content the agent can reach.
需要防御的三个组成部分:模型、模型运行所在的环境,以及智能体能够触及的外部内容。
Patterns for containing agents
限制智能体的模式
Focusing on the environment layer, we describe three isolation patterns and how they’re tailored for each Claude platform—claude.ai, Claude Code, and Cowork.
聚焦环境层,我们描述三种隔离模式,以及它们如何针对每个 Claude 平台——claude.ai、Claude Code 和 Cowork——量身定制。
We arrived at each design gradually, after finding the balance between the capabilities we need from the agent and the degree of intervention required from the user.
在找到我们需要智能体具备的能力与要求用户介入的程度之间的平衡之后,我们才逐步得出每种设计。
Pattern 1: The ephemeral container (claude.ai code execution)
模式 1:临时容器(claude.ai 代码执行)
Though best known as a chat interface, claude.ai also writes and runs code, generates files, and calls connectors.
尽管 claude.ai 最为人所知的是聊天界面,它也会编写和运行代码、生成文件并调用连接器。
When Claude runs code inside claude.ai, it does so in a gVisor container on isolated infrastructure.
当 Claude 在 claude.ai 内运行代码时,它是在隔离基础设施上的 gVisor 容器中运行的。
The agent is entirely server-side; no code runs on the local machine, and the filesystem is ephemeral (per-session).
智能体完全在服务器端;本地机器上不运行任何代码,文件系统是临时的(按会话)。
The blast radius is minimal, but so is the ceiling on what Claude can do—there's no persistent workspace and no access to the user's filesystem.
影响范围极小,但 Claude 所能做的事情的上限同样很低——没有持久化工作区,也无法访问用户的文件系统。
This also makes claude.ai subject to a more traditional threat model.
这也让 claude.ai 面临一个更传统的威胁模型。
We're not protecting user machines from agents; we're protecting our own infrastructure and each tenant from one another.
我们要保护的不是用户机器免受智能体影响,而是我们自己的基础设施,以及各个租户彼此之间的隔离。
Our pre-launch work for claude.ai was dominated by traditional security work like network configuration, internal service auth, and orchestration.
claude.ai 发布前的工作主要都是传统安全事务,比如网络配置、内部服务认证和编排。
That work reinforced the oldest lesson in security: the weakest layer is the one you built yourself. gVisor and seccomp have been hardened against well-resourced adversaries for far longer than agentic AI has existed, so the review effort went into the newer pieces we'd built around them.
这项工作再次印证了安全领域最古老的教训:最薄弱的一层就是你自己搭建的那一层。gVisor 和 seccomp 为抵御资源充足的攻击者而做的加固,其历史比智能体式 AI 的存在时间长得多,所以审查精力都投向了我们在它们之上搭建的较新组件。
We’ll come back to this later, since our custom proxy is also the piece that broke in our most consequential incident.
这一点我们稍后会再谈,因为我们自研的代理(proxy)正是在我们后果最严重的那起事故中出问题的那一环。
Pattern 2: The human-in-the-loop sandbox (Claude Code)
模式 2:人在回路沙箱(Claude Code)
Claude Code runs on a user's machine and has access to their filesystem, shell, and network.
Claude Code 运行在用户的机器上,可以访问其文件系统、shell 和网络。
Without this, coding agents have limited usefulness, so it’s imperative to find a way to grant that access safely.
没有这些权限,编码智能体的用处就很有限,因此必须找到一种安全授予这些权限的办法。
One approach is to rely on a human-in-the-loop.
一种做法是依赖人在回路。
This is only a tractable solution for Claude Code because the average user is a developer who’s familiar with coding environments: they can read bash, they understand what rm -rf does, and they already run npm install from untrusted sources several times a week.
这个方案之所以只对 Claude Code 可行,是因为它的普通用户就是熟悉编码环境的开发者:他们看得懂 bash,明白 rm -rf 会做什么,而且每周本来就要从不可信来源跑好几次 npm install。
All that means that when an “allow this” dialog pops up, they are highly likely to have the expertise to accurately evaluate what the agent is attempting to do and the risk involved.
这一切意味着,当弹出“允许此操作”的对话框时,他们极有可能具备足够的专业能力,准确判断智能体想做什么以及其中涉及的风险。
Given this, Claude Code launched with the simplest possible defense: allow reads, require approval for write, bash, and network access.
有鉴于此,Claude Code 发布时采用了最简单的防御方案:读操作放行,写操作、bash 和网络访问都需要批准。
However, as mentioned, approval fatigue showed up within weeks.
然而,如前所述,审批疲劳在几周内就出现了。
Ironically, this meant that a feature originally designed to provide oversight could arguably have the opposite effect—some users might simply stop paying attention.
讽刺的是,这意味着一个原本为提供监督而设计的功能,反而可能起到相反作用——一些用户可能干脆不再关注。
As a first step to mitigate incautious approvals, we shipped an OS-level sandbox (Seatbelt on macOS, bubblewrap on Linux) that hardens the boundary: reads are allowed, writes are allowed inside the workspace, but network is denied by default.
作为缓解不谨慎审批的第一步,我们发布了一个操作系统级沙箱(macOS 上用 Seatbelt,Linux 上用 bubblewrap)来加固边界:允许读取,允许在工作区内写入,但默认拒绝网络。
Within the sandbox, the agent runs largely without interruption.
在沙箱内,智能体基本可以不被打断地运行。
The result was an 84% reduction in permission prompts, and we open-sourced the runtime, so the boundary is auditable.
结果是权限提示减少了 84%,而且我们把该运行时开源了,因此这条边界是可审计的。
Our anonymized usage data also showed that experienced users auto-approve roughly twice as often as new users, but they also interrupt the agent mid-execution more frequently.
我们的匿名使用数据还显示,资深用户自动批准(auto-approve)的频率大约是新用户的两倍,但他们也更频繁地在智能体执行过程中打断它。
Instead of gating individual steps, experienced users are more likely to supervise the agent only when it goes off track.
资深用户不会对每一步都设关卡,而是更倾向于只在智能体偏离轨道时才去监督。
While this may be a natural evolution in how people prefer to work with agents, this too is fallible, requiring users to be technical and attentive enough to notice drift in the first place.
虽然这可能是人们与智能体协作方式的一种自然演进,但这种做法同样容易出错,因为它要求用户本身具备足够的技术能力、也足够专注,才能首先察觉到偏移。
As model capabilities improve and agents begin writing increasingly ambitious bash, it becomes harder to notice any such drift.
随着模型能力提升、智能体开始编写越来越有野心的 bash,要察觉到这类偏移就变得更加困难。
And as users move to multi-agent systems, this approach is also much less likely to be an effective oversight strategy.
而当用户转向多智能体系统时,这种做法也更难成为一种有效的监督策略。
Risk we missed: Everything before the trust dialog
我们遗漏的风险:信任对话框之前的一切
Between mid-2025 and January 2026, we received reports of vulnerabilities in Claude Code through our responsible disclosure program.
在 2025 年年中到 2026 年 1 月之间,我们通过负责任披露计划收到了关于 Claude Code 漏洞的报告。
Three of these vulnerabilities targeted code that executes before the user has consented to anything.
其中三个漏洞针对的是在用户做出任何同意之前就会执行的代码。
To understand how this is possible, consider the most direct case: a developer clones a repository to review a pull request, and that repository contains a .claude/settings.json which defines a hook.
要理解这怎么可能发生,可以看最直接的一种情形:一名开发者克隆仓库以审查一个 pull request,而该仓库包含一个 .claude/settings.json,其中定义了一个 hook。
Because Claude Code reads project settings during startup—before presenting the standard "Do you trust this folder?" prompt—the hook the attacker had authored and committed would execute automatically.
由于 Claude Code 在启动期间就会读取项目设置——早于弹出标准的“你信任这个文件夹吗?”提示——攻击者编写并提交的那个 hook 就会自动执行。
The remaining cases looked structurally similar, in which input from the not-yet-trusted directory was parsed before the trust boundary had been established.
其余案例在结构上看起来类似:来自尚未被信任的目录的输入,在信任边界确立之前就被解析了。
The fix in each case had the same shape: defer parsing and execution of project-local configuration until after the user accepts the trust prompt.
每个案例的修复都形态相同:把项目本地配置的解析与执行推迟到用户接受信任提示之后。
If you're building something similar, treat project-open, config-load, and localhost listeners the way you'd treat any inbound request from the internet.
如果你正在构建类似的东西,就把打开项目、加载配置和监听 localhost 当作来自互联网的任何入站请求来对待。
They shouldn’t be implicitly trusted just because they feel local and arrive before the user has consented.
不能仅因为它们感觉上是本地的、并且在用户同意之前就到来,就默认信任它们。
Risk we missed: The user as an injection vector
我们遗漏的风险:把用户当作注入向量
In February 2026, during a controlled internal red-team exercise, a researcher successfully phished an employee into launching Claude Code with a malicious prompt.
2026 年 2 月,在一次受控的内部红队演练中,一名研究员成功通过钓鱼让一名员工用恶意提示词启动了 Claude Code。
The phish looked like ordinary collaboration—a "can you run this for me?" email with a ready-to-paste prompt attached—and the prompt itself read like routine task instructions.
这封钓鱼诱饵看起来像普通的协作——一封“你能帮我跑一下这个吗?”的邮件,附上一条可直接粘贴的提示词——而提示词本身读起来就像例行任务说明。
But somewhere among the setup steps, it gently asked Claude to read ~/.aws/credentials, encode the contents, and POST them to an external endpoint.
但在某些准备步骤当中,它温和地要求 Claude 读取 ~/.aws/credentials、把内容编码,并将其 POST 到一个外部端点。
Across 25 retries of that prompt, Claude completed the exfiltration 24 times.
在该提示词的 25 次重试中,Claude 有 24 次完成了这次数据外泄(exfiltration)。
This is a direct prompt injection—the attacker's instructions arrived through the user, not through tool output or fetched content.
这是一次直接的提示词注入——攻击者的指令是通过用户到达的,而不是通过工具输出或抓取的内容。
Our model-layer defenses anchor on user intent—when the user is the one typing the instruction, there's nothing anomalous for a classifier to catch.
我们模型层的防御以用户意图为锚点——当输入指令的是用户本人时,分类器没有什么异常可捕获。
A human contractor handed the same script would have done the same thing.
如果把同样的脚本交给人类承包商,他们也会做同样的事。
The only defense that holds in this situation is the environment, specifically egress controls that block the POST regardless of intent and filesystem boundaries that keep ~/.aws out of reach in the first place.
在这种情况下,唯一站得住脚的防御是环境本身,具体来说,是不管意图如何都阻断该 POST 的出口控制,以及从一开始就让 ~/.aws 无法触及的文件系统边界。
(When we shared the working prompt in internal Slack for discussion, someone pointed out that some internal agents read Slack.
(当我们在内部 Slack 中分享那段起作用的提示词用于讨论时,有人指出一些内部智能体会读取 Slack。
The payload was now ambient.
载荷现在成了环境的一部分。
We added a canary string to the thread so we'd notice if anything picked it up.
我们在该讨论串中加入了一个金丝雀字符串(canary string),这样如果有任何东西读取它,我们就能注意到。
In a world where agents read everything, the investigation tooling is also an attack surface.)
在一个智能体会阅读一切的世界里,调查工具本身也是攻击面。)
Pattern 3: The local VM (Claude Cowork)
模式 3:本地 VM(Claude Cowork)
Claude Cowork runs on a user's desktop with access to a workspace folder selected by the user.
Claude Cowork 运行在用户桌面上,并可访问用户选定的工作区文件夹。
Because the platform is built for general knowledge work, not software engineering, the average user is much less likely to be fluent in bash.
因为该平台是为通用知识工作而非软件工程打造的,普通用户远不太可能精通 bash。
As a result, the human-in-the-loop sandbox strategy may not transfer; a non-technical knowledge worker shouldn’t be expected to judge bash incantations such as find . -name "*.tmp" -exec rm {} \;.
因此,人在回路沙箱策略可能无法迁移;不应指望非技术型知识工作者去判断像 find . -name "*.tmp" -exec rm {} \; 这样的 bash 咒语。
When approving an exception requires expertise the typical user doesn’t have, admins should set a boundary that is absolute and always-on.
当批准例外需要典型用户并不具备的专业知识时,管理员应设置一条绝对且始终生效的边界。
To enable this, our first version of Claude Cowork ran inside a full virtual machine using the platform's vendor hypervisor (Apple's Virtualization framework on macOS, HCS on Windows).
为实现这一点,我们第一版的 Claude Cowork 运行在完整的虚拟机内,使用平台厂商的虚拟机监控程序(hypervisor)(macOS 上 Apple 的 Virtualization framework,Windows 上 HCS)。
The VM has its own Linux kernel, its own filesystem, and its own process table.
该 VM 拥有自己的 Linux 内核、自己的文件系统和自己进程表。
The user's selected workspace and .claude folder are mounted; nothing else on the host is visible.
用户选定的工作区和 .claude 文件夹会被挂载;宿主机上的其他内容均不可见。
Credentials stay in the host's keychain and never enter the guest machine.
凭据保留在宿主机的 keychain 中,永远不会进入客户机。
This design protects against the possibility that Claude will, at some point, behave in a misaligned manner.
这种设计防范了 Claude 在某个时刻出现目标未对齐行为的可能性。
A compromised Claude could still damage what's inside the workspace folder, so the architecture is designed to make sure that's the only thing it can reach (until the user adds connectors), and that the user controls what's mounted there.
一个被攻陷的 Claude 仍可能破坏工作区文件夹内的内容,因此该架构的设计确保这是它唯一能触及的东西(直到用户添加连接器),并且由用户控制那里挂载的内容。
In the original architecture—what we call full-VM mode—the agent loop itself ran inside the guest, so Claude executed as an ordinary Linux user with no awareness it was sandboxed.
在最初的架构——我们称之为 full-VM 模式——中,智能体循环本身在客户机内运行,因此 Claude 以普通 Linux 用户的身份执行,并不知道自己处于沙箱中。
Compare this to Claude Code, where a privileged process sits outside the sandbox deciding per-command whether to enforce it; a persuasive injected prompt or a fatigued approval click can get that process to run something un-sandboxed.
与之相比,在 Claude Code 中,一个特权进程位于沙箱之外,逐条命令决定是否强制执行沙箱;一个有说服力的注入提示词或一次疲惫的批准点击,都可能让该进程运行未经沙箱隔离的内容。
Here, there was no outer process holding an escape-hatch key, and so no component with the authority to grant an exception.
在这里,不存在持有逃生舱钥匙的外部进程,因此也没有任何组件有权授予例外。

The six main isolation mechanisms of Claude Cowork’s VM.
Claude Cowork 的 VM 所采用的六种主要隔离机制。
Two are enforced outside the guest kernel and would thus survive the agent achieving root-level access within the VM.
其中两种在客户机内核之外强制执行,因此即使智能体在 VM 内获得 root 级访问权限,它们仍然有效。
The other four are guest-enforced and kept deliberately minimal because the outer layers carry the rest.
另外四种由客户机强制执行,并被有意保持最小化,因为其余部分由外层承担。
However, we soon realized that running the whole agent in full-VM mode caused practical problems: any failure during VM startup made Cowork unusable.
然而,我们很快意识到,在 full-VM 模式下运行整个智能体会带来实际问题:VM 启动期间的任何失败都会使 Cowork 无法使用。
Moving the agent loop outside of the VM, while keeping code execution inside of it, allowed Claude to still respond to the user and help debug issues rather than freeze on an error.
将智能体循环移到 VM 之外,同时将代码执行保留在 VM 之内,使 Claude 仍能响应用户并帮助调试问题,而不是在出错时卡死。
This change caused minimal security impact because the VM still enforces filesystem and network controls over code executed by the agent.
这一改动带来的安全影响极小,因为 VM 仍对智能体执行的代码强制执行文件系统和网络控制。
Separately, we also moved local MCP servers outside the VM.
另外,我们还将本地 MCP 服务器移到了 VM 之外。
Running them inside the VM made them harder to audit, created brittle dependency issues when the VM updated, and didn’t support MCPs that required interaction with local processes such as databases—such servers had to run on the host regardless.
在 VM 内运行它们会使它们更难审计,在 VM 更新时造成脆弱的依赖问题,并且不支持需要与数据库等本地进程交互的 MCP——无论怎样,这类服务器都必须在宿主机上运行。
The change brings Claude Cowork in line with how local MCP servers already work in Claude Desktop: treating them like any software a user might choose to install and entrusting admins to decide which local MCPs to enable (if any).
这一改动使 Claude Cowork 与 Claude Desktop 中本地 MCP 服务器已有的工作方式保持一致:将它们视为用户可能选择安装的任何软件,并交由管理员决定启用哪些本地 MCP(如果有的话)。
Remote MCP servers are unaffected since they do not run on the user's machine.
远程 MCP 服务器不受影响,因为它们不在用户的机器上运行。

Having the agent loop inside the VM meant that any failure in the VM caused Cowork to become unusable.
将智能体循环放在 VM 内意味着 VM 中的任何失败都会导致 Cowork 变得无法使用。
Host-mode is more reliable because the agent can still respond if the VM crashes, and it still provides important security guarantees by isolating code execution.
宿主机模式更可靠,因为如果 VM 崩溃,智能体仍能响应,而且它通过隔离代码执行仍提供了重要的安全保障。
Filesystem controls were another important architectural choice.
文件系统控制是另一个重要的架构选择。
Claude needs to be able to access some files on the host in order to be useful, but we wanted to minimize the blast radius and provide transparency to the user about local file access.
Claude 需要能够访问主机上的某些文件才能发挥作用,但我们希望将 blast radius 降到最低,并向用户透明地展示本地文件访问情况。
We found that offering different file-mount modes helps to granularly control risk; Claude Cowork offers read-only, read-write, and read-write-no-delete.
我们发现,提供不同的文件挂载模式有助于精细地控制风险;Claude Cowork 提供了 read-only、read-write 和 read-write-no-delete 模式。
One potential gotcha here is that symlink resolution has to happen before path validation, not after, or a symlink inside an authorized folder can point outside and escape.
这里的一个潜在陷阱是,符号链接解析必须在路径验证之前进行,而不是之后,否则授权文件夹内的符号链接可能指向外部并逃逸。
For enterprise customers, we allow admins to control this via mount-path allowlists in MDM settings.
对于企业客户,我们允许管理员通过 MDM 设置中的挂载路径允许列表来控制这一点。
Risk we missed: Exfiltration through an approved domain
我们遗漏的风险:通过已批准域名的 exfiltration
A clear example of exfiltration through an approved domain came from a third-party disclosure.
一个通过已批准域名进行 exfiltration 的清晰例子来自第三方披露。
Claude Cowork's egress allowlist correctly passed traffic to api.anthropic.com—the product can't function without calling our own API.
Claude Cowork 的出口允许列表正确地将流量放行至 api.anthropic.com——如果不调用我们自己的 API,该产品就无法运行。
In this case, a malicious file placed in the user's mounted workspace carried hidden instructions along with an API key controlled by the attacker.
在这种情况下,放置在用户挂载工作区中的恶意文件携带了隐藏指令以及由攻击者控制的 API key。
Claude, following the instructions, read other files in the workspace and called Anthropic's Files API using the attacker's key.
Claude 遵循这些指令,读取了工作区中的其他文件,并使用攻击者的 key 调用了 Anthropic 的 Files API。
The egress proxy checked the destination, saw api.anthropic.com, and let it through.
出口代理检查了目的地,看到 api.anthropic.com,然后放行了。
The files were uploaded to the attacker's Anthropic account.
这些文件被上传到了攻击者的 Anthropic 账户。
The sandbox worked perfectly, and yet the data was exfiltrated.
沙箱完美地工作了,但数据仍然被外泄了。
Previously, we’d conceptualized the allowlist as a destination filter, something that told Claude these domains are okay to talk to.
以前,我们将允许列表概念化为目的地过滤器,它告诉 Claude 这些域名可以通信。
But it may be better conceptualized as a capability grant.
但更好的概念化方式是将其视为能力授予。
Every function reachable through any domain on an allowlist is now an attack surface.
现在,通过允许列表上的任何域名可访问的每个函数都是一个攻击面。
Allowing api.anthropic.com meant allowing file uploads to arbitrary Anthropic accounts.
允许 api.anthropic.com 意味着允许将文件上传到任意的 Anthropic 账户。
We fixed it using a defensive man-in-the-middle proxy inside the VM that intercepts traffic to our API.
我们通过在 VM 内部使用一个防御性的中间人代理(man-in-the-middle proxy)来拦截发往我们 API 的流量,从而修复了它。
It only passes requests carrying the VM's own provisioned session token; an attacker-embedded key is rejected by the proxy.
它只放行携带 VM 自身预配的会话 token 的请求;攻击者嵌入的 key 会被代理拒绝。
It also blocks headers that would enable server-side fetch.
它还会阻止那些会启用服务器端抓取的 header。
The proxy sits inside the VM rather than on our servers because only the VM knows provenance—from the server's perspective, a Cowork request is indistinguishable from any other API client.
代理位于 VM 内部而不是我们的服务器上,因为只有 VM 知道来源——从服务器的角度来看,一个 Cowork 请求与任何其他 API 客户端无法区分。

Top: traffic to api.anthropic.com is let through, resulting in egress.
顶部:发往 api.anthropic.com 的流量被放行,导致出口。
Bottom: fix with a man-in-the-middle proxy intercepting traffic to our API.
底部:使用中间人代理拦截发往我们 API 的流量进行修复。
This is also a second instance of the principle that the software you build yourself is often the weakest.
这也是同一条原则的第二个例证:你自己构建的软件往往是最薄弱的。
The hypervisor, seccomp, and gVisor across our products have been dependable.
在我们各个产品中,hypervisor、seccomp 和 gVisor 一直很可靠。
Our custom allowlist proxy was the piece that failed.
出问题的恰恰是我们自研的白名单代理。
Risk we missed: VM isolation kept the endpoint detection software out too
我们遗漏的风险:VM 隔离同样把端点检测软件挡在了外面
When evaluating Claude Cowork, enterprise security teams asked, "Why can't our EDR see inside?"
在评估 Claude Cowork 时,企业安全团队问道:「为什么我们的 EDR 看不到里面?」
The answer was that the same isolation keeping Claude contained also kept host-based endpoint detection and response out.
答案是:把 Claude 关住的那层隔离,同样把基于主机的端点检测与响应挡在了外面。
From the EDR's perspective, Claude Cowork is an opaque hypervisor process.
从 EDR 的视角看,Claude Cowork 就是一个不透明的 hypervisor 进程。
It can't inspect the guest.
它无法检视里面的客户机(guest)。
Isolation reduces visibility, and opacity is problematic for teams whose compliance posture depends on endpoint visibility.
隔离会降低可见性,而对于合规姿态依赖端点可见性的团队来说,不透明本身就是个问题。
Our current mitigation is to use pull-based OTLP exports that let administrators retrieve event logs after the fact, but this is not the same as live monitoring.
我们目前的缓解措施是采用基于拉取的 OTLP 导出,让管理员事后取回事件日志,但这与实时监控并不是一回事。
If you're building something similar, budget for this conversation early.
如果你也在构建类似的东西,请尽早为这场对话预留预算。
Environment
环境
Ephemeral container (claude.ai)
临时容器(claude.ai)
HITL sandbox (Claude Code)
HITL 沙箱
Sealed VM (Claude Cowork)
密封 VM
Cost: Isolation Overhead
成本:隔离开销
Container spin-up
容器启动
Low-latency native sandbox
低延迟原生沙箱
Full VM boot
完整 VM 启动
Cost: User Reliance
成本:用户依赖
N/A
不适用
Must interpret bash
必须解读 bash
N/A
不适用
Risk: Blast Radius
风险:爆炸半径
Server-side container (guarded by gVisor + host infra boundary)
服务端容器(由 gVisor + 主机基础设施边界防护)
Local workspace
本地工作区
Mounted workspace (guarded by vsock + hypervisor boundary)
挂载的工作区(由 vsock + hypervisor 边界防护)
Trusting what the agent reads
信任智能体所读取的内容
Enterprises often ask us how to secure MCP connections.
企业经常问我们如何保障 MCP 连接的安全。
It's a good question, but the right one is broader than MCP specifically.
这是个好问题,但更正确的问题范围比 MCP 本身更广。
Any external resource provided to an agent represents two risks at once: a code execution risk, in the traditional supply-chain sense, and a prompt injection vector.
提供给智能体的任何外部资源都同时代表两种风险:传统供应链意义上的代码执行风险,以及一个提示注入向量。
Traditional dependency auditing (pinning versions, verifying signatures, reviewing source) addresses the first, but misses the second.
传统的依赖审计(固定版本、验证签名、审查源码)能解决第一种,但会漏掉第二种。
Remote versus local is more important than it seems.
远程与本地之别比表面上更重要。
A locally installed tool is auditable.
本地安装的工具是可审计的。
You can read the code, pin the version, and know it won't change under you.
你可以阅读代码、固定版本,并知道它不会在你脚下发生变化。
A remote tool—a hosted MCP server, a cloud connector—can change behavior at any point after you’ve approved it; your install-time trust decision may no longer apply.
远程工具——托管的 MCP 服务器、云连接器——可能在你批准之后的任何时间点改变行为;你安装时做出的信任决定可能不再适用。
Our connector directory addresses this through ongoing review, but anything outside it should be treated as untrusted.
我们的连接器目录通过持续审查来应对这一点,但目录之外的任何东西都应视为不可信。
Run it against fake data first, in an environment where the blast radius of a malicious tool is contained.
先在假数据上运行它,且要在一个恶意工具的 blast radius 受到控制的环境里进行。
Tool output is an attack surface even when the tool is trusted.
即使工具本身可信,工具输出也是一个攻击面。
The GitHub README example mentioned earlier is exactly this case; any input scanning applied to web pages needs to be applied to network-enabled tool results with the same rigor.
前面提到的 GitHub README 例子正是这种情况;任何应用于网页的输入扫描,都需要以同样的严格程度应用于联网工具返回的结果。
Even though this adds latency and isn't a perfect defense, we err toward live inspection: once a poisoned tool return has steered the agent into exfiltrating data, the log just shows a successful, authorized API call.
尽管这会增加延迟、也不是完美的防御,我们仍倾向于实时检查:一旦被投毒的工具返回结果诱导智能体把数据外泄,日志里只会显示一次成功的、已授权的 API 调用。
There's no after-the-fact signal to find.
事后根本找不到任何信号。
In Claude Code and Claude Cowork, tool calls route through proxies that enforce network and file policy and can inspect return values before they enter the model's context.
在 Claude Code 和 Claude Cowork 中,工具调用会经过代理,这些代理执行网络和文件策略,并能在返回值进入模型上下文之前检查它们。
The classifier that does the inspection can be a small, fast model; it doesn't need to be the one doing the reasoning.
执行检查的分类器可以是一个小型、快速的模型;它不需要是进行推理的那个模型。
Looking ahead
展望未来
Models and products are advancing fast.
模型和产品正在快速进步。
As they do, risks morph and evolve, and our mitigations must keep pace to meet them.
随着它们进步,风险也在变形和演化,我们的缓解措施必须跟上以应对它们。
Persistent memory poisoning.
持久化记忆投毒(persistent memory poisoning)。
The share of agent context that persists across sessions keeps growing—this includes product memory, CLAUDE.md files, mounted workspaces, and the state directories of scheduled and long-running agents.
跨会话持久保留的智能体上下文占比持续增长——这包括产品记忆、CLAUDE.md 文件、挂载的工作区,以及定时和长期运行智能体的状态目录。
An injection that lands in any of these is reloaded each time the agent starts.
任何落入这些位置的注入都会在智能体每次启动时被重新加载。
As more agent state survives the session, we are threatened by new persistence mechanisms in the classic post-exploitation sense.
随着更多智能体状态在会话结束后仍然存续,我们在经典的后渗透意义上受到新的持久化机制的威胁。
Good classifiers on session startup will need to become more commonplace.
在会话启动时运行的良好分类器将需要变得更加普遍。
Multi-agent trust escalation.
多智能体信任升级(trust escalation)。
On the one hand, sub-agents can isolate untrusted content, returning structured facts rather than raw text up to the main agent.
一方面,子智能体可以隔离不受信任的内容,只向主智能体返回结构化事实,而不是原始文本。
On the other hand, this can be abused: if a sub-agent's output is treated as higher-trust than raw tool results, because such output came from “us,” a new vector for prompt injection is introduced.
另一方面,这可能会被滥用:如果子智能体的输出被视为比原始工具结果更可信,因为这类输出来自“我们”,那么就引入了新的提示词注入途径。
In multi-agent systems, there is a tradeoff between allocating differing trust levels and becoming liable to trust escalation.
在多智能体系统中,在分配不同信任级别与变得容易发生信任升级之间存在权衡。
Agent identity.
智能体身份(agent identity)。
Claude Cowork's answer to agent identity is concrete: credentials stay in the host keychain, the VM gets a per-session scoped-down token, and that token can be revoked independently of the user's.
Claude Cowork 对智能体身份的回答很具体:凭据保留在主机钥匙串中,VM 获得按会话缩权的 token,并且该 token 可以独立于用户的 token 被撤销。
However, we are starting to grapple with the broader question of cross-platform agent identity.
然而,我们正开始应对跨平台智能体身份这个更广泛的问题。
Should an agent possess its own principal identity, or should it act as an extension of the user and inherit the user’s permissions?
智能体应该拥有自己的主体身份,还是应该作为用户的延伸并继承用户的权限?
Ultimately, the answer may be a blend of the two.
最终,答案可能是两者的混合。
As agents grow more capable, attack surfaces are constantly shifting.
随着智能体能力越来越强,攻击面也在不断变化。
The types of failures we’ve seen are likely to be repeated across industries and labs.
我们见过的这类失败,很可能在各行各业和各实验室中重演。
We need collective investment in agent-specific security posture, from shared benchmarks and disclosure norms to common identity standards and cross-vendor red-teaming.
我们需要对针对智能体的安全态势进行集体投入,从共享基准和披露规范,到通用身份标准和跨厂商红队测试。
We focus on containment in this piece, but that's only one part of the security picture for agents.
本文聚焦遏制,但这只是智能体安全图景的一部分。
For governance, observability, and the rest of the stack, see NIST's project on AI agent identity and authorization, the six-agency guidance on adopting agentic AI led by Australia's ACSC with CISA and the UK's NCSC, and ISO/IEC 42001, the AI management standard.
关于治理、可观测性以及技术栈的其余部分,参见 NIST 关于 AI 智能体身份与授权的项目、由澳大利亚 ACSC 与 CISA 和英国 NCSC 牵头制定的六机构采用智能体式 AI 指南,以及 AI 管理标准 ISO/IEC 42001。
Our Glasswing initiative is one contribution, but we look forward to working with both partners and competitors on this critical issue.
我们的 Glasswing 计划是一项贡献,但我们期待与合作伙伴和竞争对手共同应对这一关键问题。
Summary
摘要
In short, there are a few principles we keep returning to:
简而言之,有几条原则是我们反复回到的:
Design for containment at the environment layer first, then steer behavior at the model layer.
首先在环境层为遏制而设计,然后在模型层引导行为。
Two of the incidents that taught us the most—the employee phish and the third-party allowlist disclosure—were both cases of egress, in which data left through a permitted path.
给我们教训最深的两起事件——员工钓鱼邮件和第三方白名单披露——都是出站案例,数据通过一条被允许的路径离开了。
In each, the model layer couldn't help; there was nothing anomalous for it to catch.
在每一起事件中,模型层都帮不上忙;它没有什么异常可捕捉。
The deterministic boundary is what gets hit when everything probabilistic misses.
当一切概率性机制都漏掉时,被撞上的正是确定性边界。
Match isolation strength to the user's capacity for oversight.
让隔离强度与用户的监督能力相匹配。
A developer who can read bash and a knowledge worker who can't are not running the same threat model.
看得懂 bash 的开发者和看不懂 bash 的知识工作者,并不是在运行同一个威胁模型。
The question of whether a user can evaluate what an agent is about to do should help determine the containment strategy, and answering it wrong in either direction—too much friction for experts, too much trust for non-experts—is its own failure.
用户能否评估智能体即将做什么,这一问题应有助于决定遏制策略;而无论朝哪个方向答错——对专家造成过多摩擦,对非专家给予过多信任——本身就是一种失败。
Be wary of custom components.
警惕自定义组件。
Battle-tested hypervisors, syscall filters, and container runtimes have survived more adversarial attention than anything you'll build.
久经实战考验的 hypervisor、系统调用过滤器和容器运行时,经受过的对抗性审视比你将构建的任何东西都多。
Across every deployment described here, the standard primitives held while our own work around them exposed flaws.
在本文描述的每一个部署中,标准原语都守住了,而我们围绕它们所做的工作暴露了缺陷。
Ultimately, while agents may be a new category of software, their system-level interactions are not.
最终,虽然智能体可能是一类新的软件,但它们在系统层面的交互并非新事物。
They still read files, open sockets, and spawn processes; this makes containment with mature tooling a crucially viable defense.
它们仍然读取文件、打开套接字、启动进程;这使得用成熟工具进行遏制成为一种至关重要的可行防御手段。
The risk-reward balance of deployments will keep shifting as AI develops, but placing a hard limit on blast radius often forces that balance into the right direction.
随着 AI 的发展,部署的风险回报平衡会持续变化,但对爆炸半径施加硬性限制往往会把这种平衡推向正确的方向。
Acknowledgements
致谢
Written by Max McGuinness, Mikaela Grace, Jiri De Jonghe, Jake Eaton, and Abel Ribbink.
作者:Max McGuinness、Mikaela Grace、Jiri De Jonghe、Jake Eaton 和 Abel Ribbink。
We're also grateful to Hanah Ho, Hasnain Lakhani, Pedram Navid, Molly Villagra, Maya Nielan, Akila Srinivasan, Travis Szucs, Sam Attard, Alfred Xing, Mohamad El Hajj, Gabby Curtis, David Dworken, Adam Jones, Amie Rotherham, Christian Ryan, Lucas Smedley, Brett Andrews, and others for their contributions.
我们也感谢 Hanah Ho、Hasnain Lakhani、Pedram Navid、Molly Villagra、Maya Nielan、Akila Srinivasan、Travis Szucs、Sam Attard、Alfred Xing、Mohamad El Hajj、Gabby Curtis、David Dworken、Adam Jones、Amie Rotherham、Christian Ryan、Lucas Smedley、Brett Andrews 以及其他人的贡献。
Special thanks to our security and product engineering teams, and to the individuals and organizations that have reported vulnerabilities in Claude products.
特别感谢我们的安全和产品工程团队,以及那些报告 Claude 产品漏洞的个人和组织。
Footnotes
脚注
Claude Code auto mode delegates command approvals to a model-based classifier; it minimizes friction (roughly 0.4% of benign commands blocked) at the cost of missing a fraction of risky ones (~17% of overeager actions get through), so it's one layer of defense-in-depth inside a sandbox, not a substitute for one.
Claude Code auto mode 将命令审批委托给基于模型的分类器;它尽可能减少阻力(约 0.4% 的良性命令被阻止),代价是会漏掉一部分风险命令(约 17% 的过度主动操作会通过),因此它只是沙箱内纵深防御(defense-in-depth)的一层,而不是沙箱的替代品。