揭开 AI 智能体评测的面纱
Demystifying evals for AI agents
段落导航
Good evaluations help teams ship AI agents more confidently.
好的评测(eval)能帮助团队更自信地交付 AI 智能体。
Without them, it’s easy to get stuck in reactive loops—catching issues only in production, where fixing one failure creates others.
没有它们,团队很容易陷入被动反应的循环——只有在生产环境中才发现问题,而在那里修复一个故障又会制造其他故障。
Evals make problems and behavioral changes visible before they affect users, and their value compounds over the lifecycle of an agent.
评测让问题和行为变化在影响用户之前就变得可见,而且其价值会在智能体的整个生命周期中不断累积。
As we described in Building effective agents, agents operate over many turns: calling tools, modifying state, and adapting based on intermediate results.
正如我们在《Building effective agents》中所述,智能体会在多轮中运行:调用工具、修改状态,并根据中间结果进行调整。
These same capabilities that make AI agents useful—autonomy, intelligence, and flexibility—also make them harder to evaluate.
让 AI 智能体变得有用的那些能力——自主性、智能和灵活性——也使它们更难被评测。
Through our internal work and with customers at the frontier of agent development, we’ve learned how to design more rigorous and useful evals for agents.
通过我们的内部工作以及与处于智能体开发前沿的客户合作,我们学会了如何为智能体设计更严谨且更有用的评测。
Here's what's worked across a range of agent architectures and use cases in real-world deployment.
以下是在真实世界部署中,跨多种智能体架构和用例行之有效的做法。
An evaluation (“eval”) is a test for an AI system: give an AI an input, then apply grading logic to its output to measure success.
评测(“eval”)是对 AI 系统的一种测试:给 AI 一个输入,然后对其输出应用评分逻辑来衡量是否成功。
In this post, we focus on automated evals that can be run during development without real users.
在本文中,我们聚焦于可以在开发期间运行、无需真实用户的自动化评测。
Single-turn evaluations are straightforward: a prompt, a response, and grading logic.
单轮评测很直接:一个提示词、一个响应和评分逻辑。
For earlier LLMs, single-turn, non-agentic evals were the main evaluation method.
对于早期的 LLM,单轮、非智能体评测是主要的评测方法。
As AI capabilities have advanced, multi-turn evaluations have become increasingly common.
随着 AI 能力不断提升,多轮评测变得越来越常见。
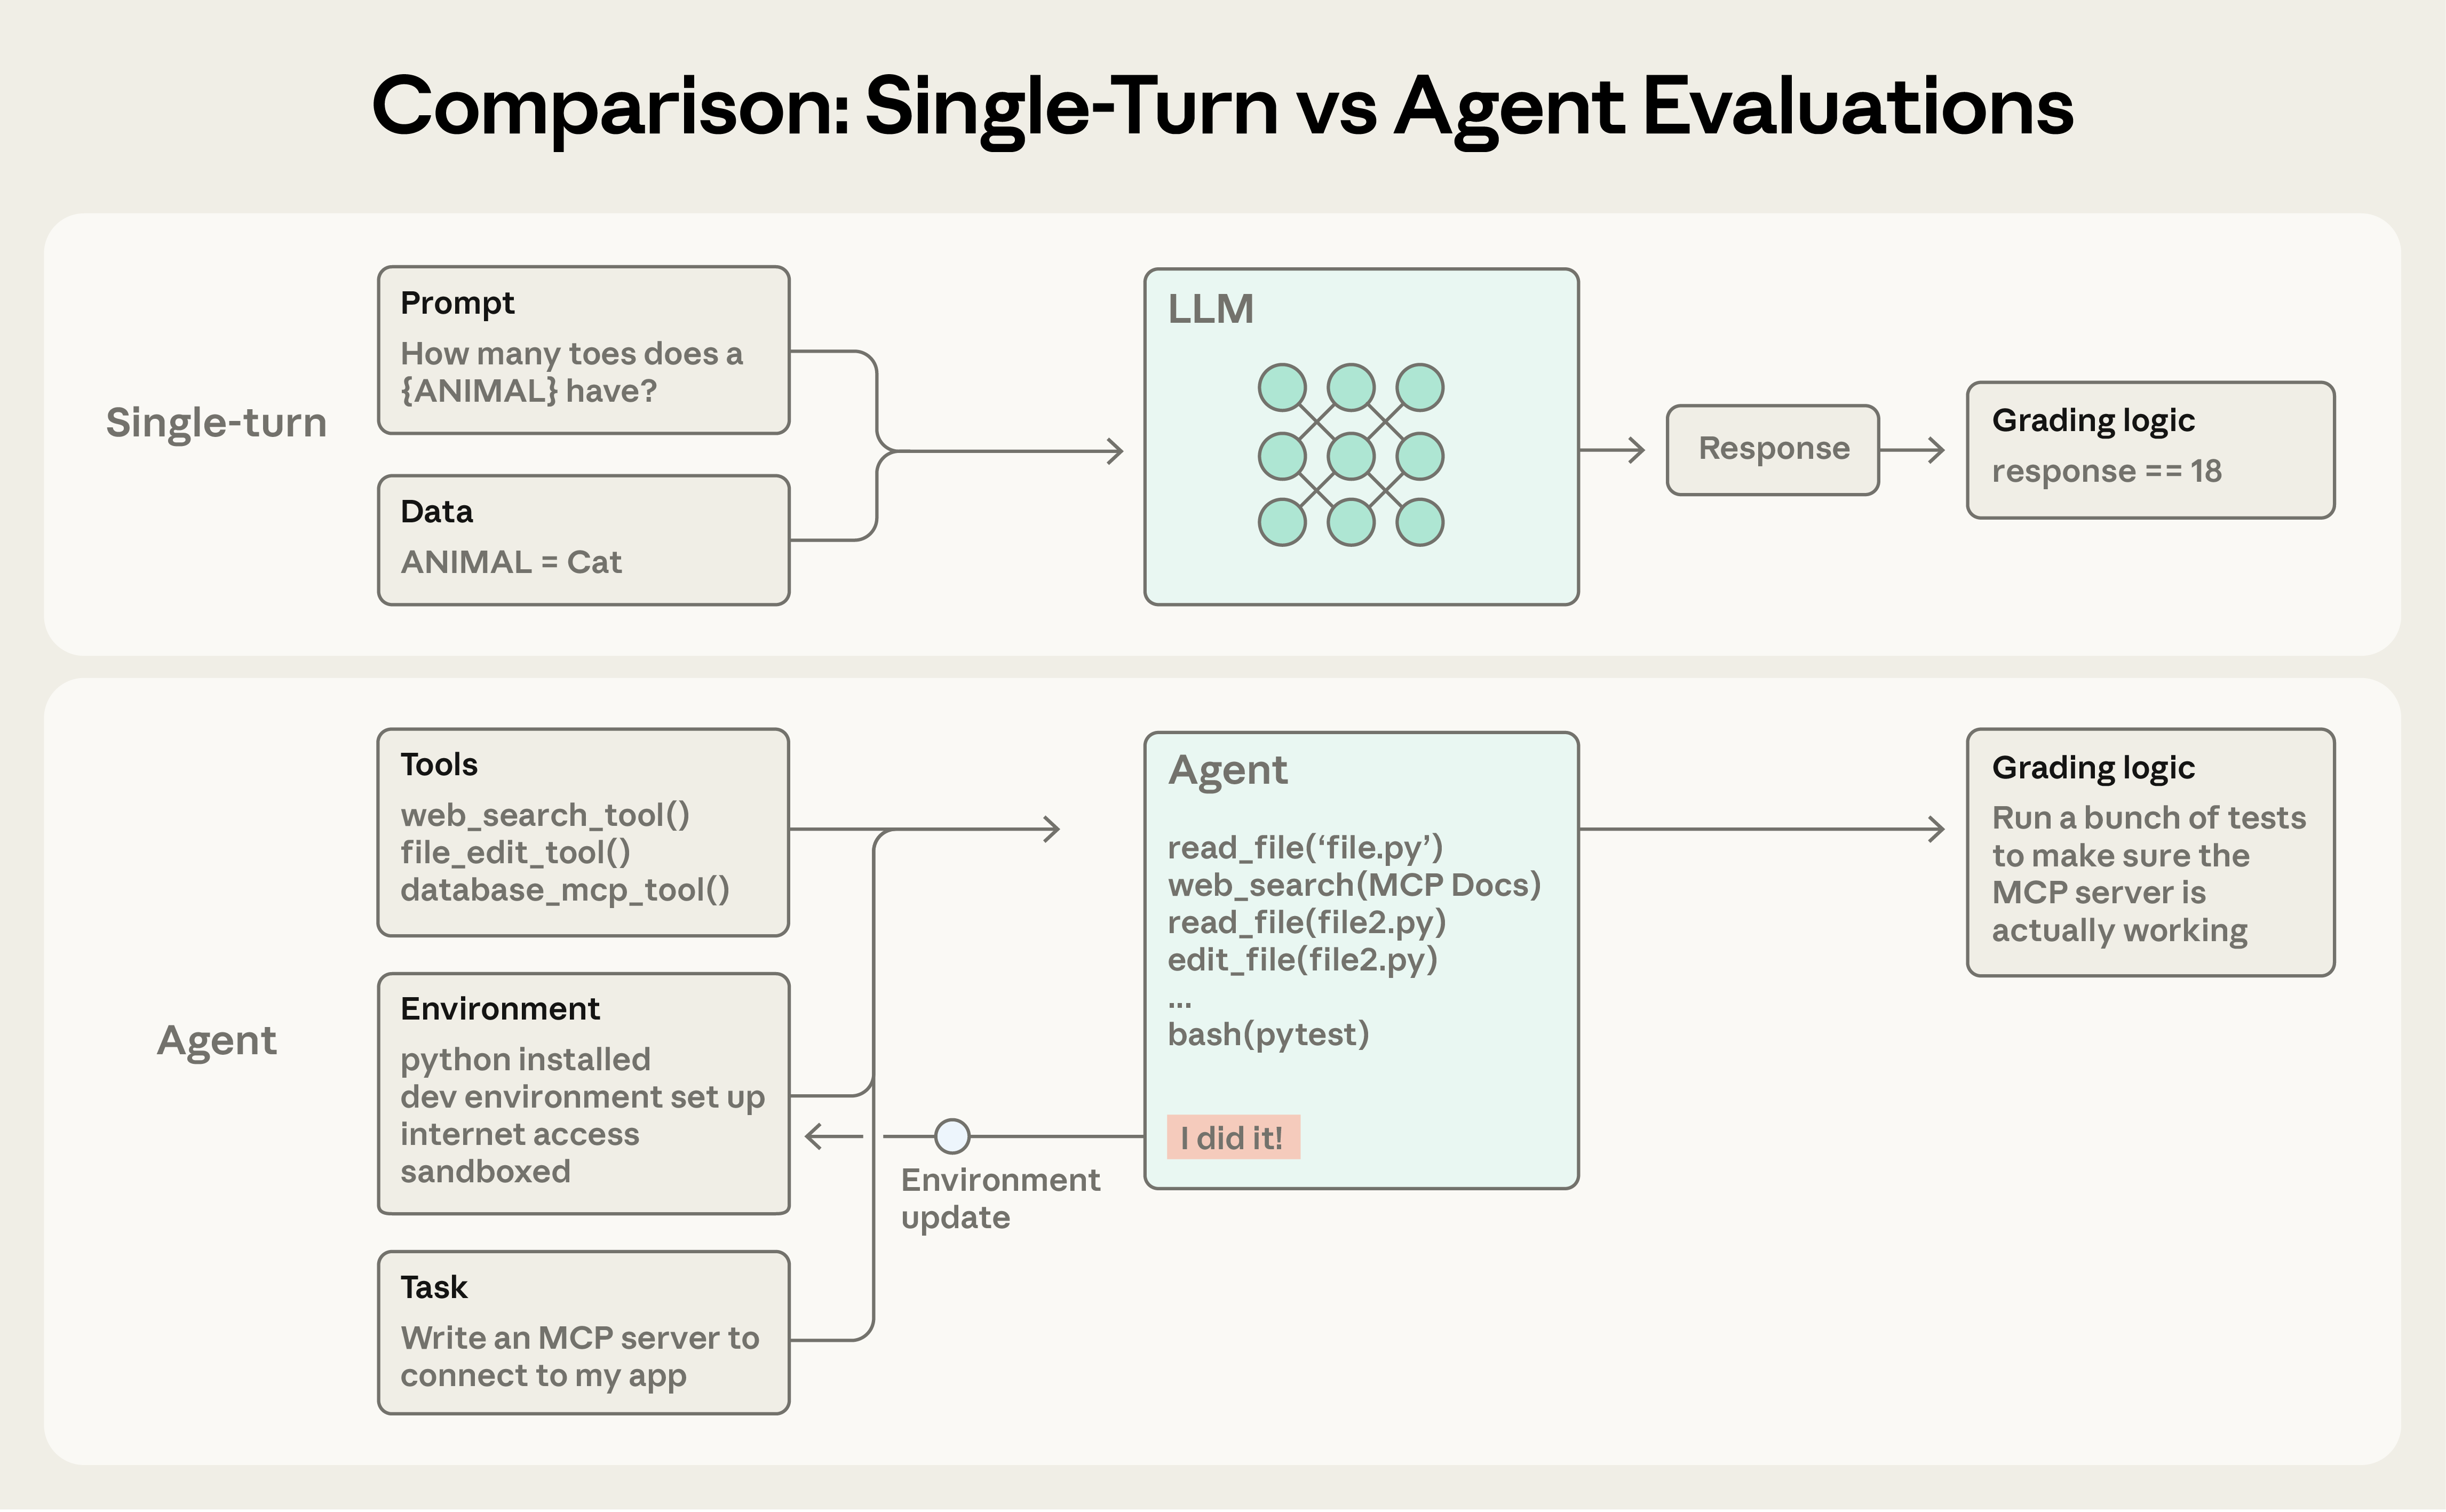
In a simple eval, an agent processes a prompt, and a grader checks if the output matches expectations.
在简单评测中,智能体处理一个提示词,评分器检查输出是否符合预期。
For a more complex multi-turn eval, a coding agent receives tools, a task (building an MCP server in this case), and an environment, executes an "agent loop" (tool calls and reasoning), and updates the environment with the implementation.
对于更复杂的多轮评测,一个编码智能体接收工具、一项任务(此处是构建一个 MCP 服务器)和一个环境,执行“智能体循环(agent loop)”(工具调用与推理),并用该实现更新环境。
Grading then uses unit tests to verify the working MCP server.
随后评分使用单元测试来验证可工作的 MCP 服务器。
Agent evaluations are even more complex.
智能体评测更加复杂。
Agents use tools across many turns, modifying state in the environment and adapting as they go—which means mistakes can propagate and compound.
智能体会在多轮交互中使用工具,修改环境中的状态并随机应变——这意味着错误会传播并累积。
Frontier models can also find creative solutions that surpass the limits of static evals.
前沿模型还能找到超越静态评测局限的创造性解法。
For instance, Opus 4.5 solved a 𝜏2-bench problem about booking a flight by discovering a loophole in the policy.
例如,Opus 4.5 在解决 𝜏2-bench 中一道预订机票的题目时,发现了策略中的一个漏洞。
It “failed” the evaluation as written, but actually came up with a better solution for the user.
按评测的既定标准,它“失败”了,但实际上为用户给出了更好的方案。
When building agent evaluations, we use the following definitions:
在构建智能体评测时,我们采用以下定义:
A task (a.k.a problem or test case) is a single test with defined inputs and success criteria.
任务(也称题目或测试用例)是带有明确输入和成功标准的单个测试。
Each attempt at a task is a trial.
对任务的每次尝试称为一次试验(trial)。
Because model outputs vary between runs, we run multiple trials to produce more consistent results.
由于模型输出在不同运行之间会有差异,我们会跑多次试验以获得更一致的结果。
A grader is logic that scores some aspect of the agent’s performance.
评分器(grader)是对智能体表现的某个方面进行打分的逻辑。
A task can have multiple graders, each containing multiple assertions (sometimes called checks).
一个任务可以有多个评分器,每个评分器包含多条断言(有时称为检查项)。
A transcript (also called a trace or trajectory) is the complete record of a trial, including outputs, tool calls, reasoning, intermediate results, and any other interactions.
记录(transcript,也称 trace 或 trajectory)是一次试验的完整记录,包括输出、工具调用、推理、中间结果以及任何其他交互。
For the Anthropic API, this is the full messages array at the end of an eval run - containing all the calls to the API and all of the returned responses during the evaluation.
对于 Anthropic API,这是评测运行结束时的完整 messages 数组——包含评测期间所有对 API 的调用以及所有返回的响应。
The outcome is the final state in the environment at the end of the trial.
结果(outcome)是 trial 结束时环境中的最终状态。
A flight-booking agent might say “Your flight has been booked” at the end of the transcript, but the outcome is whether a reservation exists in the environment’s SQL database.
预订航班的智能体可能会在 transcript 末尾说“您的航班已预订”,但结果在于环境的 SQL 数据库中是否存在一条预订记录。
An evaluation harness is the infrastructure that runs evals end-to-end.
评测框架(harness)是端到端运行 eval 的基础设施。
It provides instructions and tools, runs tasks concurrently, records all the steps, grades outputs, and aggregates results.
它提供指令和工具,并发运行任务,记录所有步骤,对输出打分,并汇总结果。
An agent harness (or scaffold) is the system that enables a model to act as an agent: it processes inputs, orchestrates tool calls, and returns results.
智能体框架(或脚手架)是使模型能够作为智能体行动的系统:它处理输入、编排工具调用并返回结果。
When we evaluate “an agent,” we’re evaluating the harness and the model working together.
当我们评测“一个智能体”时,我们评测的是框架和模型协同工作。
For example, Claude Code is a flexible agent harness, and we used its core primitives through the Agent SDK to build our long-running agent harness.
例如,Claude Code 是一个灵活的智能体框架,我们通过 Agent SDK 使用其核心原语来构建我们的长时间运行智能体框架。
An evaluation suite is a collection of tasks designed to measure specific capabilities or behaviors.
评测套件(evaluation suite)是一组旨在衡量特定能力或行为的任务。
Tasks in a suite typically share a broad goal.
套件中的任务通常共享一个宽泛的目标。
For instance, a customer support eval suite might test refunds, cancellations, and escalations.
例如,一个客户支持评测套件可能会测试退款、取消和升级。
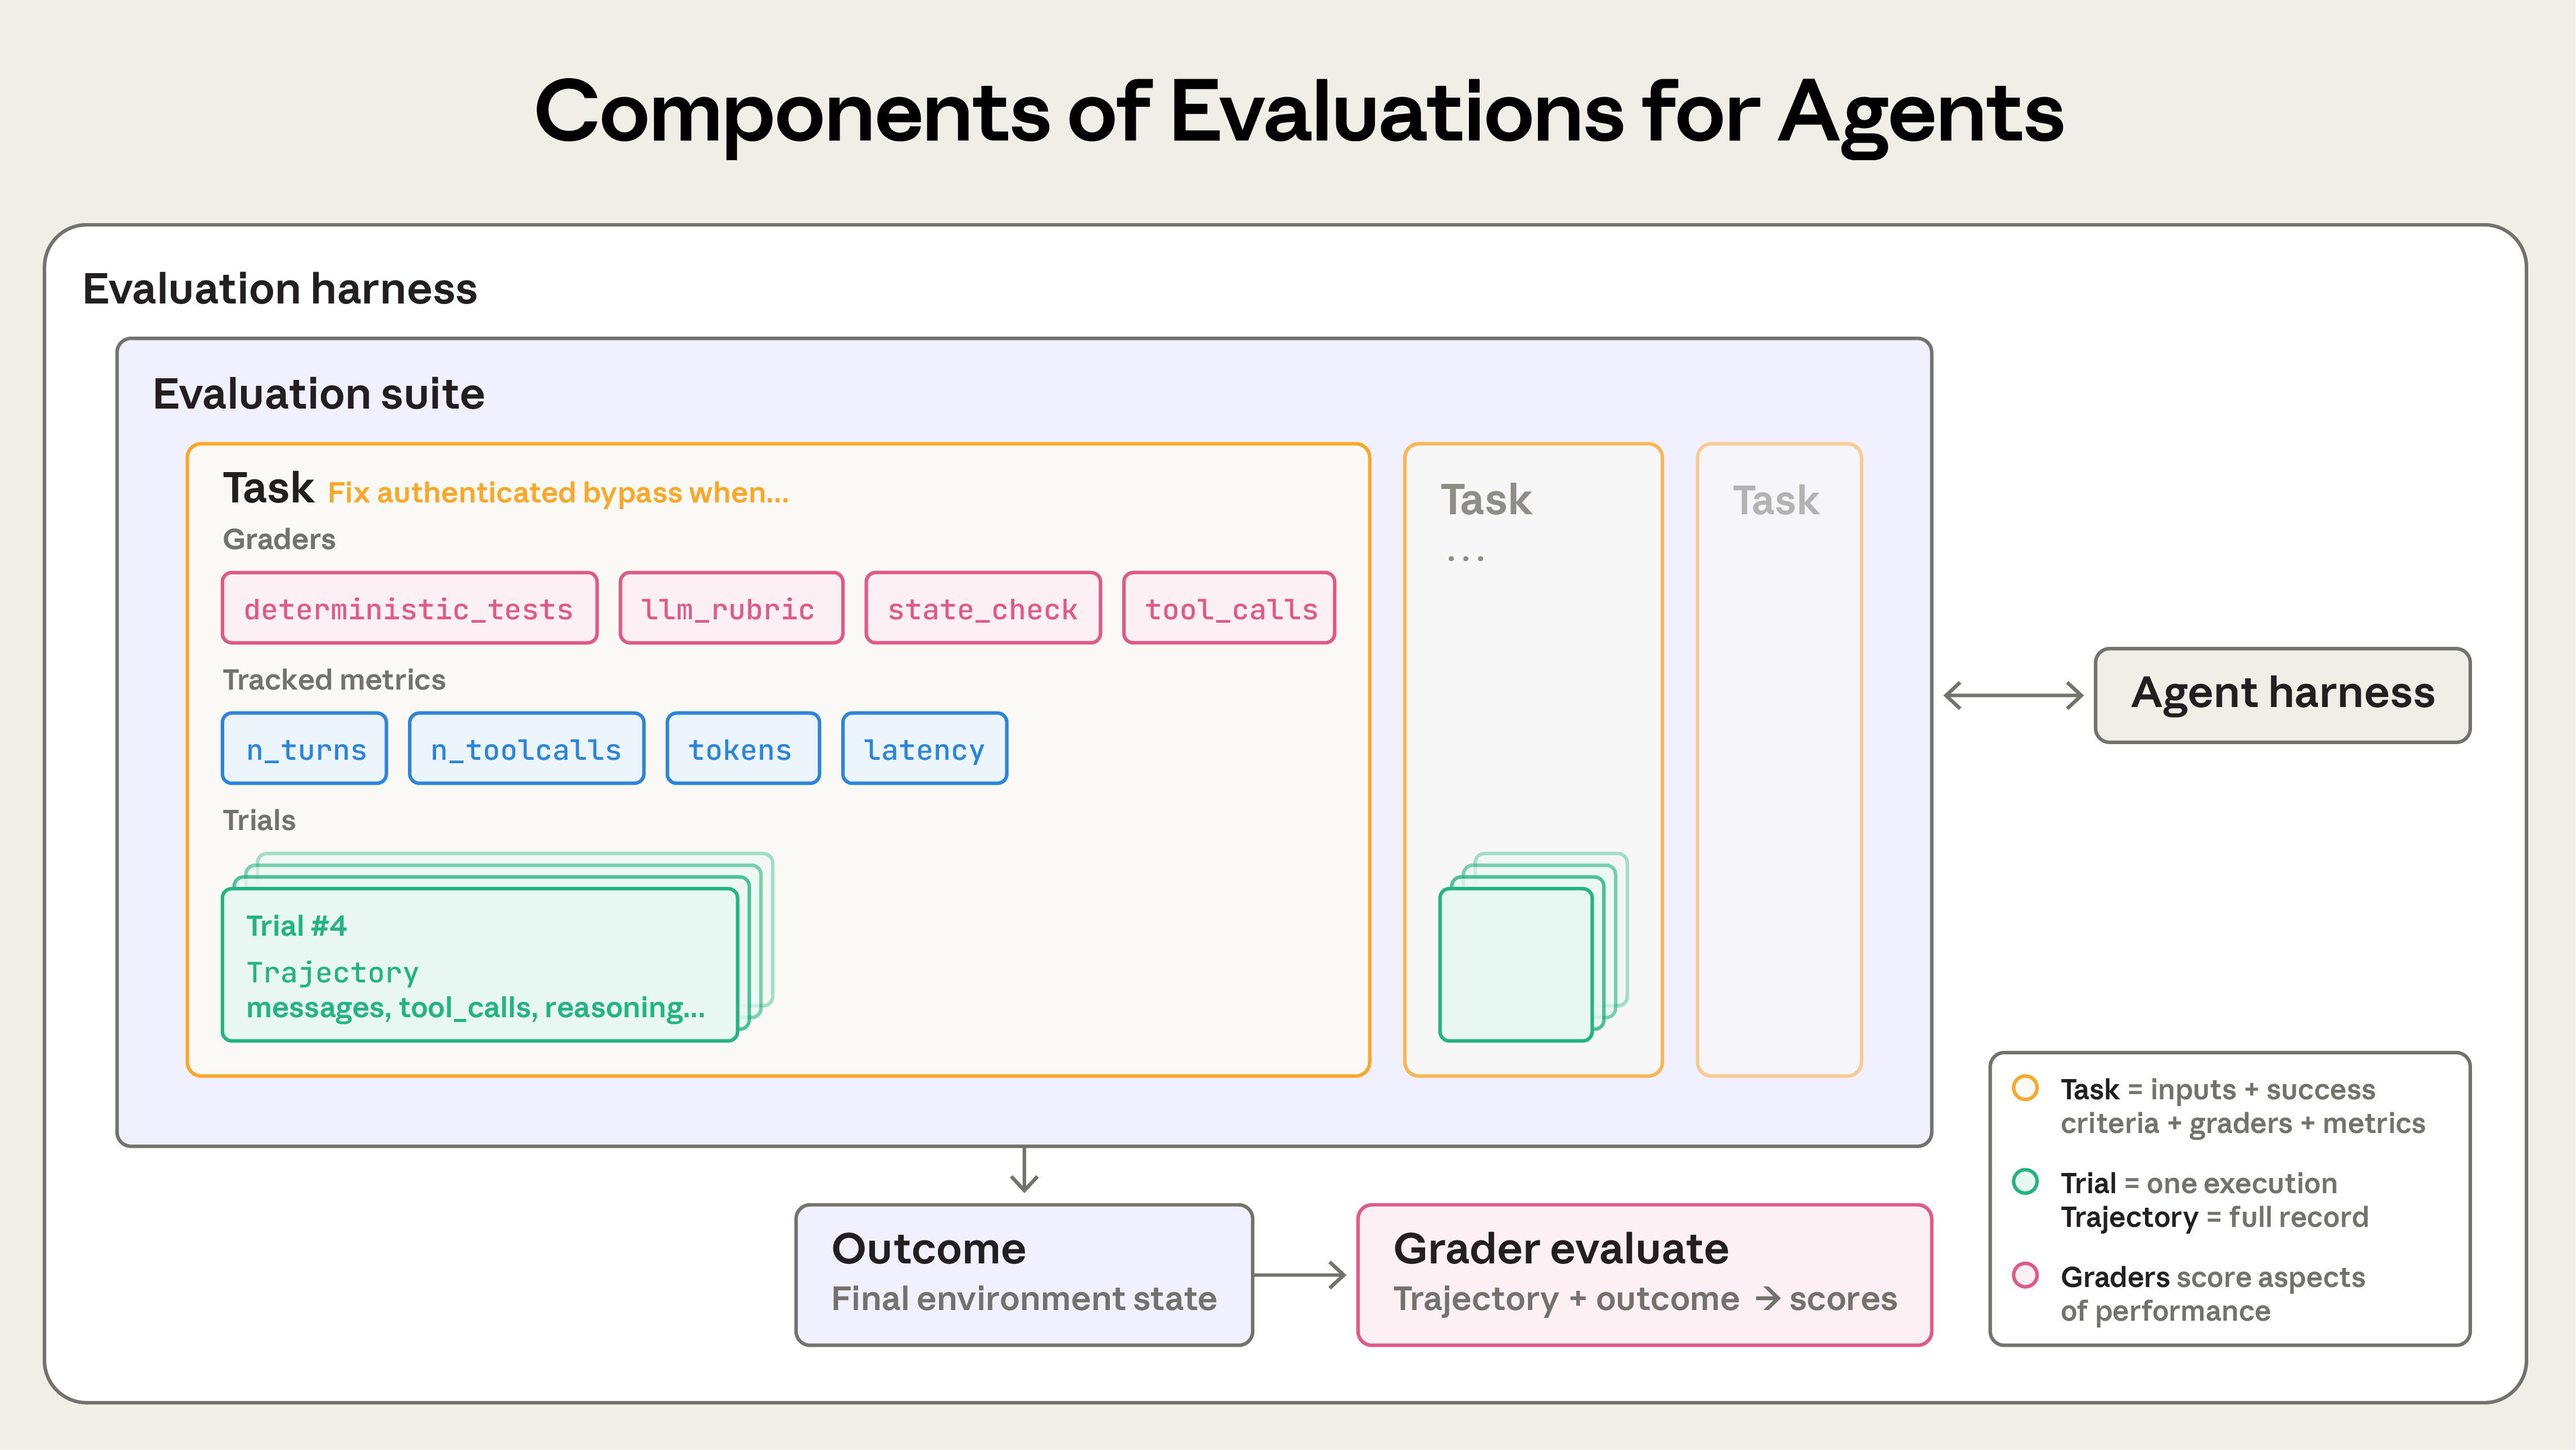
Components of evaluations for agents.
智能体评测的组成部分。
When teams first start building agents, they can get surprisingly far through a combination of manual testing, dogfooding, and intuition.
当团队刚开始构建智能体时,结合手动测试、内部试用(dogfooding)和直觉,他们能取得惊人的进展。
More rigorous evaluation may even seem like overhead that slows down shipping.
更严谨的评测甚至可能看起来像是拖慢发布的额外开销。
But after the early prototyping stages, once an agent is in production and has started scaling, building without evals starts to break down.
但在早期原型阶段之后,一旦智能体进入生产环境并开始扩展规模,没有 eval 的构建方式就会开始失效。
The breaking point often comes when users report the agent feels worse after changes, and the team is “flying blind” with no way to verify except to guess and check.
临界点常常出现在用户反馈更改后智能体感觉更差,而团队“盲飞”,除了猜测和检查之外没有办法验证。
Absent evals, debugging is reactive: wait for complaints, reproduce manually, fix the bug, and hope nothing else regressed.
缺少评测,调试是被动的:等待投诉,手动复现,修复 bug,并希望没有其他东西回归。
Teams can't distinguish real regressions from noise, automatically test changes against hundreds of scenarios before shipping, or measure improvements.
团队无法区分真正的回归和噪声,无法在发布前针对数百个场景自动测试更改,也无法衡量改进。
We’ve seen this progression play out many times.
我们已经多次看到这种发展过程。
For instance, Claude Code started with fast iteration based on feedback from Anthropic employees and external users.
例如,Claude Code 最初基于 Anthropic 员工和外部用户的反馈进行快速迭代。
Later, we added evals—first for narrow areas like concision and file edits, and then for more complex behaviors like over-engineering.
后来,我们添加了评测——先是针对简洁性和文件编辑等狭窄领域,然后针对过度工程等更复杂的行为。
These evals helped identify issues, guide improvements, and focus research-product collaborations.
这些评测帮助识别问题、指导改进,并聚焦研究-产品合作。
Combined with production monitoring, A/B tests, user research, and more, evals provide signals to continue improving Claude Code as it scales.
结合生产监控、A/B 测试、用户研究等,评测提供了持续改进 Claude Code 的信号,随着其规模扩大。
Writing evals is useful at any stage in the agent lifecycle.
在智能体生命周期的任何阶段,编写评测都是有用的。
Early on, evals force product teams to specify what success means for the agent, while later they help uphold a consistent quality bar.
在早期,评测迫使产品团队明确智能体成功的含义,而在后期,它们有助于维持一致的质量标准。
Descript’s agent helps users edit videos, so they built evals around three dimensions of a successful editing workflow: don’t break things, do what I asked, and do it well.
Descript 的智能体帮助用户编辑视频,因此他们围绕成功编辑工作流的三个维度构建评测:不破坏东西、做我要求的事,以及做好它。
They evolved from manual grading to LLM graders with criteria defined by the product team and periodic human calibration, and now regularly run two separate suites for quality benchmarking and regression testing.
他们从手动评分发展到由产品团队定义标准并定期进行人工校准的 LLM 评分器,现在定期运行两个独立的套件,用于质量基准测试和回归测试。
The Bolt AI team started building evals later, after they already had a widely used agent.
Bolt AI 团队后来才开始构建评测,那时他们已经有一个广泛使用的智能体。
In 3 months, they built an eval system that runs their agent and grades outputs with static analysis, uses browser agents to test apps, and employs LLM judges for behaviors like instruction following.
在 3 个月内,他们构建了一个评测系统,该系统运行他们的智能体并使用静态分析对输出评分,使用浏览器智能体测试应用,并采用 LLM 评判员来评估指令遵循等行为。
Some teams create evals at the start of development; others add them once at scale when evals become a bottleneck for improving the agent.
有些团队在开发开始时创建评测;另一些团队则在规模扩大后,当评测成为改进智能体的瓶颈时才添加它们。
Evals are especially useful at the start of agent development to explicitly encode expected behavior.
在智能体开发开始时,评测特别有用,可以明确编码预期行为。
Two engineers reading the same initial spec could come away with different interpretations on how the AI should handle edge cases.
两名工程师阅读相同的初始规范,可能会对 AI 应如何处理边缘情况得出不同的解释。
An eval suite resolves this ambiguity.
一个评测套件解决了这种歧义。
Regardless of when they’re created, evals help accelerate development.
无论何时创建,评测都有助于加速开发。
Evals also shape how quickly you can adopt new models.
评测还决定了你能多快采用新模型。
When more powerful models come out, teams without evals face weeks of testing while competitors with evals can quickly determine the model’s strengths, tune their prompts, and upgrade in days.
当更强大的模型出现时,没有评测的团队面临数周的测试,而有评测的竞争对手可以快速确定模型的优势、调整他们的提示词,并在几天内升级。
Once evals exist, you get baselines and regression tests for free: latency, token usage, cost per task, and error rates can be tracked on a static bank of tasks.
一旦有了评测,你就能免费获得基线(baseline)和回归测试:延迟、token 用量、每任务成本和错误率都可以在一个静态任务库上跟踪。
Evals can also become the highest-bandwidth communication channel between product and research teams, defining metrics researchers can optimize against.
评测还可以成为产品团队与研究团队之间带宽最高的沟通渠道,定义研究人员可以据此优化的指标。
Clearly, evals have wide-ranging benefits beyond tracking regressions and improvements.
显然,除了跟踪回归和改进,评测还有广泛的好处。
Their compounding value is easy to miss given that costs are visible upfront while benefits accumulate later.
它们的复利价值很容易被忽视,因为成本在前期显而易见,而收益则在后期才累积。
We see several common types of agents deployed at scale today, including coding agents, research agents, computer use agents, and conversational agents.
如今我们看到多种常见类型的智能体已大规模部署,包括编码智能体、研究智能体、计算机使用智能体(computer use agent)和对话智能体。
Each type may be deployed across a wide variety of industries, but they can be evaluated using similar techniques.
每种类型可能部署在多种行业中,但它们可以用相似的技术进行评测。
You don’t need to invent an evaluation from scratch.
你不需要从零开始发明评测。
The sections below describe proven techniques for several agent types.
以下各节介绍了针对几种智能体类型经过验证的技术。
Use these methods as a foundation, then extend them to your domain.
把这些方法作为基础,然后将其扩展到你的领域。
Agent evaluations typically combine three types of graders: code-based, model-based, and human.
智能体评测通常组合三类评分器:基于代码、基于模型和人工。
Each grader evaluates some portion of either the transcript or the outcome.
每个评分器都会评估轨迹或结果的某一部分。
An essential component of effective evaluation design is to choose the right graders for the job.
有效评测设计的一个关键组成部分是为任务选择合适的评分器。
Methods
方法
Strengths
优势
Weaknesses
劣势
• String match checks (exact, regex, fuzzy, etc.) • Binary tests (fail-to-pass, pass-to-pass) • Static analysis (lint, type, security) • Outcome verification • Tool calls verification (tools used, parameters) • Transcript analysis (turns taken, token usage)
• 字符串匹配检查(精确、regex、模糊等) • 二元测试(fail-to-pass、pass-to-pass) • 静态分析(lint、类型、安全) • 结果验证 • 工具调用验证(使用的工具、参数) • 轨迹分析(轮次数量、token 用量)
• Fast • Cheap • Objective • Reproducible • Easy to debug • Verify specific conditions
• 快 • 便宜 • 客观 • 可复现 • 易于调试 • 可验证特定条件
• Brittle to valid variations that don’t match expected patterns exactly • Lacking in nuance • Limited for evaluating some more subjective tasks
• 对于不能精确匹配预期模式的有效变体很脆弱 • 缺乏细微差别 • 在评测某些更主观的任务时存在局限
Methods
方法
Strengths
优势
Weaknesses
劣势
Methods
方法
Strengths
优势
Weaknesses
劣势
For each task, scoring can be weighted (combined grader scores must hit a threshold), binary (all graders must pass), or a hybrid.
对于每个任务,评分可以是加权的(组合的评分器分数必须达到阈值)、二元的(所有评分器都必须通过)或混合的。
Capability or “quality” evals ask, “What can this agent do well?”
能力或“质量”评测会问:“这个智能体擅长做什么?”
They should start at a low pass rate, targeting tasks the agent struggles with and giving teams a hill to climb.
它们应该从较低的通过率开始,针对智能体难以完成的任务,给团队一个需要攀登的山丘。
Regression evals ask, “Does the agent still handle all the tasks it used to?” and should have a nearly 100% pass rate.
回归(regression)评测会问:“智能体是否仍能处理它过去处理的所有任务?”并且应该具有接近 100% 的通过率。
They protect against backsliding, as a decline in score signals that something is broken and needs to be improved.
它们防止倒退,因为分数下降表明某些地方出了问题,需要改进。
As teams hill-climb on capability evals, it’s important to also run regression evals to make sure changes don’t cause issues elsewhere.
当团队在能力评测上攀登时,同时运行回归评测也很重要,以确保更改不会在其他地方引起问题。
After an agent is launched and optimized, capability evals with high pass rates can “graduate” to become a regression suite that is run continuously to catch any drift.
在智能体发布并优化后,通过率高的能力评测可以“毕业”成为持续运行的回归套件,以捕捉任何漂移。
Tasks that once measured “Can we do this at all?” then measure “Can we still do this reliably?”
曾经衡量“我们究竟能不能做这件事?”的任务,之后会衡量“我们能否仍然可靠地做到这件事?”
Coding agents write, test, and debug code, navigating codebases and running commands much like a human developer.
编码智能体编写、测试和调试代码,像人类开发者一样浏览代码库并运行命令。
Effective evals for modern coding agents usually rely on well-specified tasks, stable test environments, and thorough tests for the generated code.
对现代编码智能体有效的评测通常依赖于明确指定的任务、稳定的测试环境,以及对生成代码的彻底测试。
Deterministic graders are natural for coding agents because software is generally straightforward to evaluate: does the code run and do the tests pass?
确定性评分器对编码智能体来说很自然,因为软件的评测通常很直接:代码能跑吗,测试能过吗?
Two widely used coding agent benchmarks, SWE-bench Verified and Terminal-Bench, follow this approach.
两个被广泛使用的编码智能体基准测试——SWE-bench Verified 和 Terminal-Bench——就采用了这种方法。
SWE-bench Verified gives agents GitHub issues from popular Python repositories and grades solutions by running the test suite; a solution passes only if it fixes the failing tests without breaking existing ones.
SWE-bench Verified 把来自热门 Python 仓库的 GitHub issue 交给智能体,并通过运行测试套件来给解决方案评分;只有当解决方案修复了失败的测试且没有破坏已有测试时,才算通过。
LLMs have progressed from 40% to >80% on this eval in just one year.
仅仅一年时间,LLM 在这一评测上的成绩就从 40% 提升到了 >80%。
Terminal-Bench takes a different track: it tests end-to-end technical tasks, such as building a Linux kernel from source or training an ML model.
Terminal-Bench 走的是另一条路:它测试端到端的技术任务,比如从源码构建 Linux 内核,或训练一个 ML 模型。
Once you have a set of pass-or-fail tests for validating the key outcomes of a coding task, it’s often useful to also grade the transcript.
一旦你拥有一组用于验证编码任务关键结果的通过/失败测试,通常也值得对记录进行评分。
For instance, heuristics-based code quality rules can evaluate the generated code based on more than passing tests, and model-based graders with clear rubrics can assess behaviors like how the agent calls tools or interacts with the user.
例如,基于启发式的代码质量规则可以在测试是否通过之外进一步评估生成的代码;而带有清晰评分标准的基于模型的评分器,则可以评估智能体如何调用工具或如何与用户交互这类行为。
Example: Theoretical evaluation for a coding agent
示例:为编码智能体做理论上的评测
Consider a coding task where the agent must fix an authentication bypass vulnerability.
设想一个编码任务,智能体必须修复一个认证绕过漏洞。
As shown in the illustrative YAML file below, one could evaluate this agent using both graders and metrics.
如下面这个示意性的 YAML 文件所示,人们可以用多个评分器和指标来评测这个智能体。
task:
  id: "fix-auth-bypass_1"
  desc: "Fix authentication bypass when password field is empty and ..."
  graders:
    - type: deterministic_tests
      required: [test_empty_pw_rejected.py, test_null_pw_rejected.py]
    - type: llm_rubric
      rubric: prompts/code_quality.md
    - type: static_analysis
      commands: [ruff, mypy, bandit]
    - type: state_check
      expect:
        security_logs: {event_type: "auth_blocked"}
    - type: tool_calls
      required:
        - {tool: read_file, params: {path: "src/auth/*"}}
        - {tool: edit_file}
        - {tool: run_tests}
  tracked_metrics:
    - type: transcript
      metrics:
        - n_turns
        - n_toolcalls
        - n_total_tokens
    - type: latency
      metrics:
        - time_to_first_token
        - output_tokens_per_sec
- time_to_last_tokenNote that this example showcases the full range of available graders for illustration.
请注意,这个示例为了说明问题,展示了全部可用的评分器。
In practice, coding evaluations typically rely on unit tests for correctness verification and an LLM rubric for assessing overall code quality, with additional graders and metrics added only as needed.
在实践中,编码评测通常依靠单元测试来验证正确性,并用 LLM 评分标准来评估整体代码质量,只有确有需要时才加入额外的评分器和指标。
Conversational agents interact with users in domains like support, sales, or coaching.
对话式智能体在客服、销售或教练等领域与用户交互。
Unlike traditional chatbots, they maintain state, use tools, and take actions mid-conversation.
与传统聊天机器人不同,它们会维护状态、使用工具,并在对话过程中采取行动。
While coding and research agents can also involve many turns of interaction with the user, conversational agents present a distinct challenge: the quality of the interaction itself is part of what you're evaluating.
虽然编码和研究智能体也可能涉及与用户的多轮交互,但对话式智能体带来了一个独特的挑战:交互本身的质量也是你所评测内容的一部分。
Effective evals for conversational agents usually rely on verifiable end-state outcomes and rubrics that capture both task completion and interaction quality.
针对对话式智能体的有效评测通常依靠可验证的最终状态结果,以及能同时捕捉任务完成情况和交互质量的评分标准。
Unlike most other evals, they often require a second LLM to simulate the user.
与大多数其他评测不同,它们往往需要第二个 LLM 来模拟用户。
We use this approach in our alignment auditing agents to stress-test models through extended, adversarial conversations.
我们在自己的对齐审计智能体中采用这种方法,通过长时间的对抗性对话对模型进行压力测试。
Success for conversational agents can be multidimensional: is the ticket resolved (state check), did it finish in <10 turns (transcript constraint), and was the tone appropriate (LLM rubric)?
对话智能体的成功可以是多维的:工单是否已解决(状态检查),是否在 <10 轮内完成(对话记录约束),以及语气是否恰当(LLM 评分标准)?
Two benchmarks that incorporate multidimensionality are 𝜏-Bench and its successor, τ2-Bench.
体现多维性的两个基准是 𝜏-Bench 及其后继者 τ2-Bench。
These simulate multi-turn interactions across domains like retail support and airline booking, where one model plays a user persona while the agent navigates realistic scenarios.
这些模拟跨零售支持和航司订票等领域的多轮交互,其中一个模型扮演用户角色,而智能体则应对真实场景。
Example: Theoretical evaluation for a conversational agent
示例:针对对话智能体的理论评测
Consider a support task where the agent must handle a refund for a frustrated customer.
考虑一个支持任务,其中智能体必须为一位沮丧的客户处理退款。
graders:
  - type: llm_rubric
    rubric: prompts/support_quality.md
    assertions:
      - "Agent showed empathy for customer's frustration"
      - "Resolution was clearly explained"
      - "Agent's response grounded in fetch_policy tool results"
  - type: state_check
    expect:
      tickets: {status: resolved}
      refunds: {status: processed}
  - type: tool_calls
    required:
      - {tool: verify_identity}
      - {tool: process_refund, params: {amount: "<=100"}}
      - {tool: send_confirmation}
  - type: transcript
    max_turns: 10
tracked_metrics:
  - type: transcript
    metrics:
      - n_turns
      - n_toolcalls
      - n_total_tokens
  - type: latency
    metrics:
      - time_to_first_token
      - output_tokens_per_sec
- time_to_last_tokenAs in our coding agent example, this task showcases multiple grader types for illustration.
正如我们的编码智能体示例,这个任务展示了多种评分器类型以作说明。
In practice, conversational agent evaluations typically use model-based graders to assess both communication quality and goal completion, because many tasks—like answering a question—may have multiple “correct” solutions.
在实践中,对话智能体评测通常使用基于模型的评分器来评估沟通质量和目标完成情况,因为许多任务——比如回答一个问题——可能有多个“正确”答案。
Research agents gather, synthesize, and analyze information, then produce outputs like an answer or report.
研究智能体收集、综合并分析信息,然后产出答案或报告等输出。
Unlike coding agents where unit tests provide binary pass/fail signals, research quality can only be judged relative to the task.
与编码智能体不同,后者由单元测试提供二元的通过/失败信号,研究质量只能相对于任务来评判。
What counts as “comprehensive,” “well-sourced,” or even “correct” depends on context: a market scan, due diligence for an acquisition, and a scientific report each require different standards.
什么算“全面”、“来源充分”甚至“正确”取决于上下文:市场扫描、收购尽职调查和科学报告各自需要不同的标准。
Research evals face unique challenges: experts may disagree on whether a synthesis is comprehensive, ground truth shifts as reference content changes constantly, and longer, more open-ended outputs create more room for mistakes.
研究评测面临独特挑战:专家可能对一份综合结果是否全面存在分歧,随着参考内容不断变化,真值(ground truth)也会变化,而更长、更开放式的输出会留下更多出错空间。
A benchmark like BrowseComp, for example, tests whether AI agents can find needles in haystacks across the open web—questions designed to be easy to verify but hard to solve.
例如,像 BrowseComp 这样的基准测试 AI 智能体能否在开放网络中大海捞针——这些问题被设计得易于验证,却难以解决。
One strategy to build research agent evals is to combine grader types.
构建研究型智能体评测的一种策略是组合使用多种评分器类型。
Groundedness checks verify that claims are supported by retrieved sources, coverage checks define key facts a good answer must include, and source quality checks confirm the consulted sources are authoritative, rather than simply the first retrieved.
有据性检查(groundedness checks)验证主张是否得到所检索来源的支持,覆盖度检查(coverage checks)定义了一个好答案必须包含的关键事实,来源质量检查(source quality checks)确认所咨询的来源具有权威性,而不只是最先检索到的来源。
For tasks with objectively correct answers (“What was Company X’s Q3 revenue?”), exact match works.
对于有客观正确答案的任务(“X 公司第三季度的营收是多少?”),精确匹配(exact match)就够用了。
An LLM can flag unsupported claims and gaps in coverage but also verify the open-ended synthesis for coherence and completeness.
LLM 可以标记出缺乏支持的主张和覆盖度缺口,但也能核查开放式综合内容的连贯性和完整性。
Given the subjective nature of research quality, LLM-based rubrics should be frequently calibrated against expert human judgment to grade these agents effectively.
鉴于研究质量的主观性,基于 LLM 的评分标准应频繁地对照专家人工判断进行校准,才能有效地为这些智能体评分。
Computer use agents interact with software through the same interface as humans—screenshots, mouse clicks, keyboard inputs, and scrolling—rather than through APIs or code execution.
计算机使用智能体通过与人相同的界面与软件交互——截图、鼠标点击、键盘输入和滚动——而不是通过 API 或代码执行。
They can use any application with a graphical user interface (GUI), from design tools to legacy enterprise software.
它们可以使用任何带有图形用户界面(GUI)的应用程序,从设计工具到遗留企业软件。
Evaluation requires running the agent in a real or sandboxed environment where it can use software applications and checking whether it achieved the intended outcome.
评测需要在真实或沙箱(sandbox)环境中运行智能体,让它能够使用软件应用,并检查它是否达成了预期结果。
For instance, WebArena tests browser-based tasks, using URL and page state checks to verify the agent navigated correctly, along with backend state verification for tasks that modify data (confirming an order was actually placed, not just that the confirmation page appeared).
例如,WebArena 测试基于浏览器的任务,使用 URL 和页面状态检查来验证智能体是否正确导航,同时对会修改数据的任务进行后端状态验证(确认订单确实已下单,而不只是出现了确认页面)。
OSWorld extends this to full operating system control, with evaluation scripts that inspect diverse artifacts after task completion: file system state, application configs, database contents, and UI element properties.
OSWorld 将此扩展到对整个操作系统的控制,其评测脚本会在任务完成后检查多种产物:文件系统状态、应用配置、数据库内容和 UI 元素属性。
Browser use agents require a balance between token efficiency and latency.
浏览器使用智能体(browser use agents)需要在 token 效率和延迟之间取得平衡。
DOM-based interactions execute quickly but consume many tokens, while screenshot-based interactions are slower but more token-efficient.
基于 DOM 的交互执行很快,但消耗大量 token;而基于截图的交互较慢,但更节省 token。
For example, when asking Claude to summarize Wikipedia, it is more efficient to extract the text from the DOM.
例如,让 Claude 总结 Wikipedia 时,从 DOM 中提取文本更高效。
When finding a new laptop case on Amazon, it is more efficient to take screenshots (as extracting the entire DOM is token-intensive).
在 Amazon 上寻找新的笔记本电脑包时,截图更高效(因为提取整个 DOM 非常消耗 token)。
In our Claude for Chrome product, we developed evals to check that the agent was selecting the right tool for each context.
在我们的 Claude for Chrome 产品中,我们开发了评测来检查智能体是否为每种上下文选择了正确的工具。
This enabled us to complete browser-based tasks faster and more accurately.
这使我们能够更快、更准确地完成基于浏览器的任务。
Regardless of agent type, agent behavior varies between runs, which makes evaluation results harder to interpret than they first appear.
无论哪种智能体类型,智能体的行为在不同运行之间都会有差异,这使得评测结果比初看上去更难解读。
Each task has its own success rate—maybe 90% on one task, 50% on another—and a task that passed on one eval run might fail on the next.
每个任务都有自己的成功率——某个任务可能是 90%,另一个可能是 50%——而在一次评测运行中通过的任务,下一次可能就会失败。
Sometimes, what we want to measure is how often (what proportion of the trials) an agent succeeds for a task.
有时,我们想衡量的是智能体完成某个任务的频率(即成功试验所占的比例)。
Two metrics help capture this nuance:
有两个指标有助于捕捉这种细微差别:
pass@k measures the likelihood that an agent gets at least one correct solution in k attempts.
pass@k 衡量智能体在 k 次尝试中至少得到一次正确解的可能性。
As k increases, pass@k score rises: more “shots on goal” means higher odds of at least 1 success.
随着 k 增大,pass@k 分数会上升:更多的「射门机会」意味着至少成功 1 次的概率更高。
A score of 50% pass@1 means that a model succeeds at half the tasks in the eval on its first try.
50% 的 pass@1 分数意味着模型在第一次尝试中就能成功完成评测中一半的任务。
In coding, we’re often most interested in the agent finding the solution on the first try—pass@1.
在编码场景中,我们通常最关心智能体能否在第一次尝试时就找到解法——pass@1。
In other cases, proposing many solutions is valid as long as one works.
在其他情况下,只要有一个方案可行,提出多个方案也是合理的。
pass^k measures the probability that all k trials succeed.
pass^k 衡量全部 k 次试验都成功的概率。
As k increases, pass^k falls since demanding consistency across more trials is a harder bar to clear.
随着 k 增大,pass^k 会下降,因为要求在更多次试验中保持一致是更难达到的标准。
If your agent has a 75% per-trial success rate and you run 3 trials, the probability of passing all three is (0.75)³ ≈ 42%.
如果你的智能体单次试验成功率为 75%,并且你运行 3 次试验,那么三次全部通过的概率是 (0.75)³ ≈ 42%。
This metric especially matters for customer-facing agents where users expect reliable behavior every time.
这一指标对面向客户的智能体尤其重要,因为用户期望每次都能获得可靠的行为。
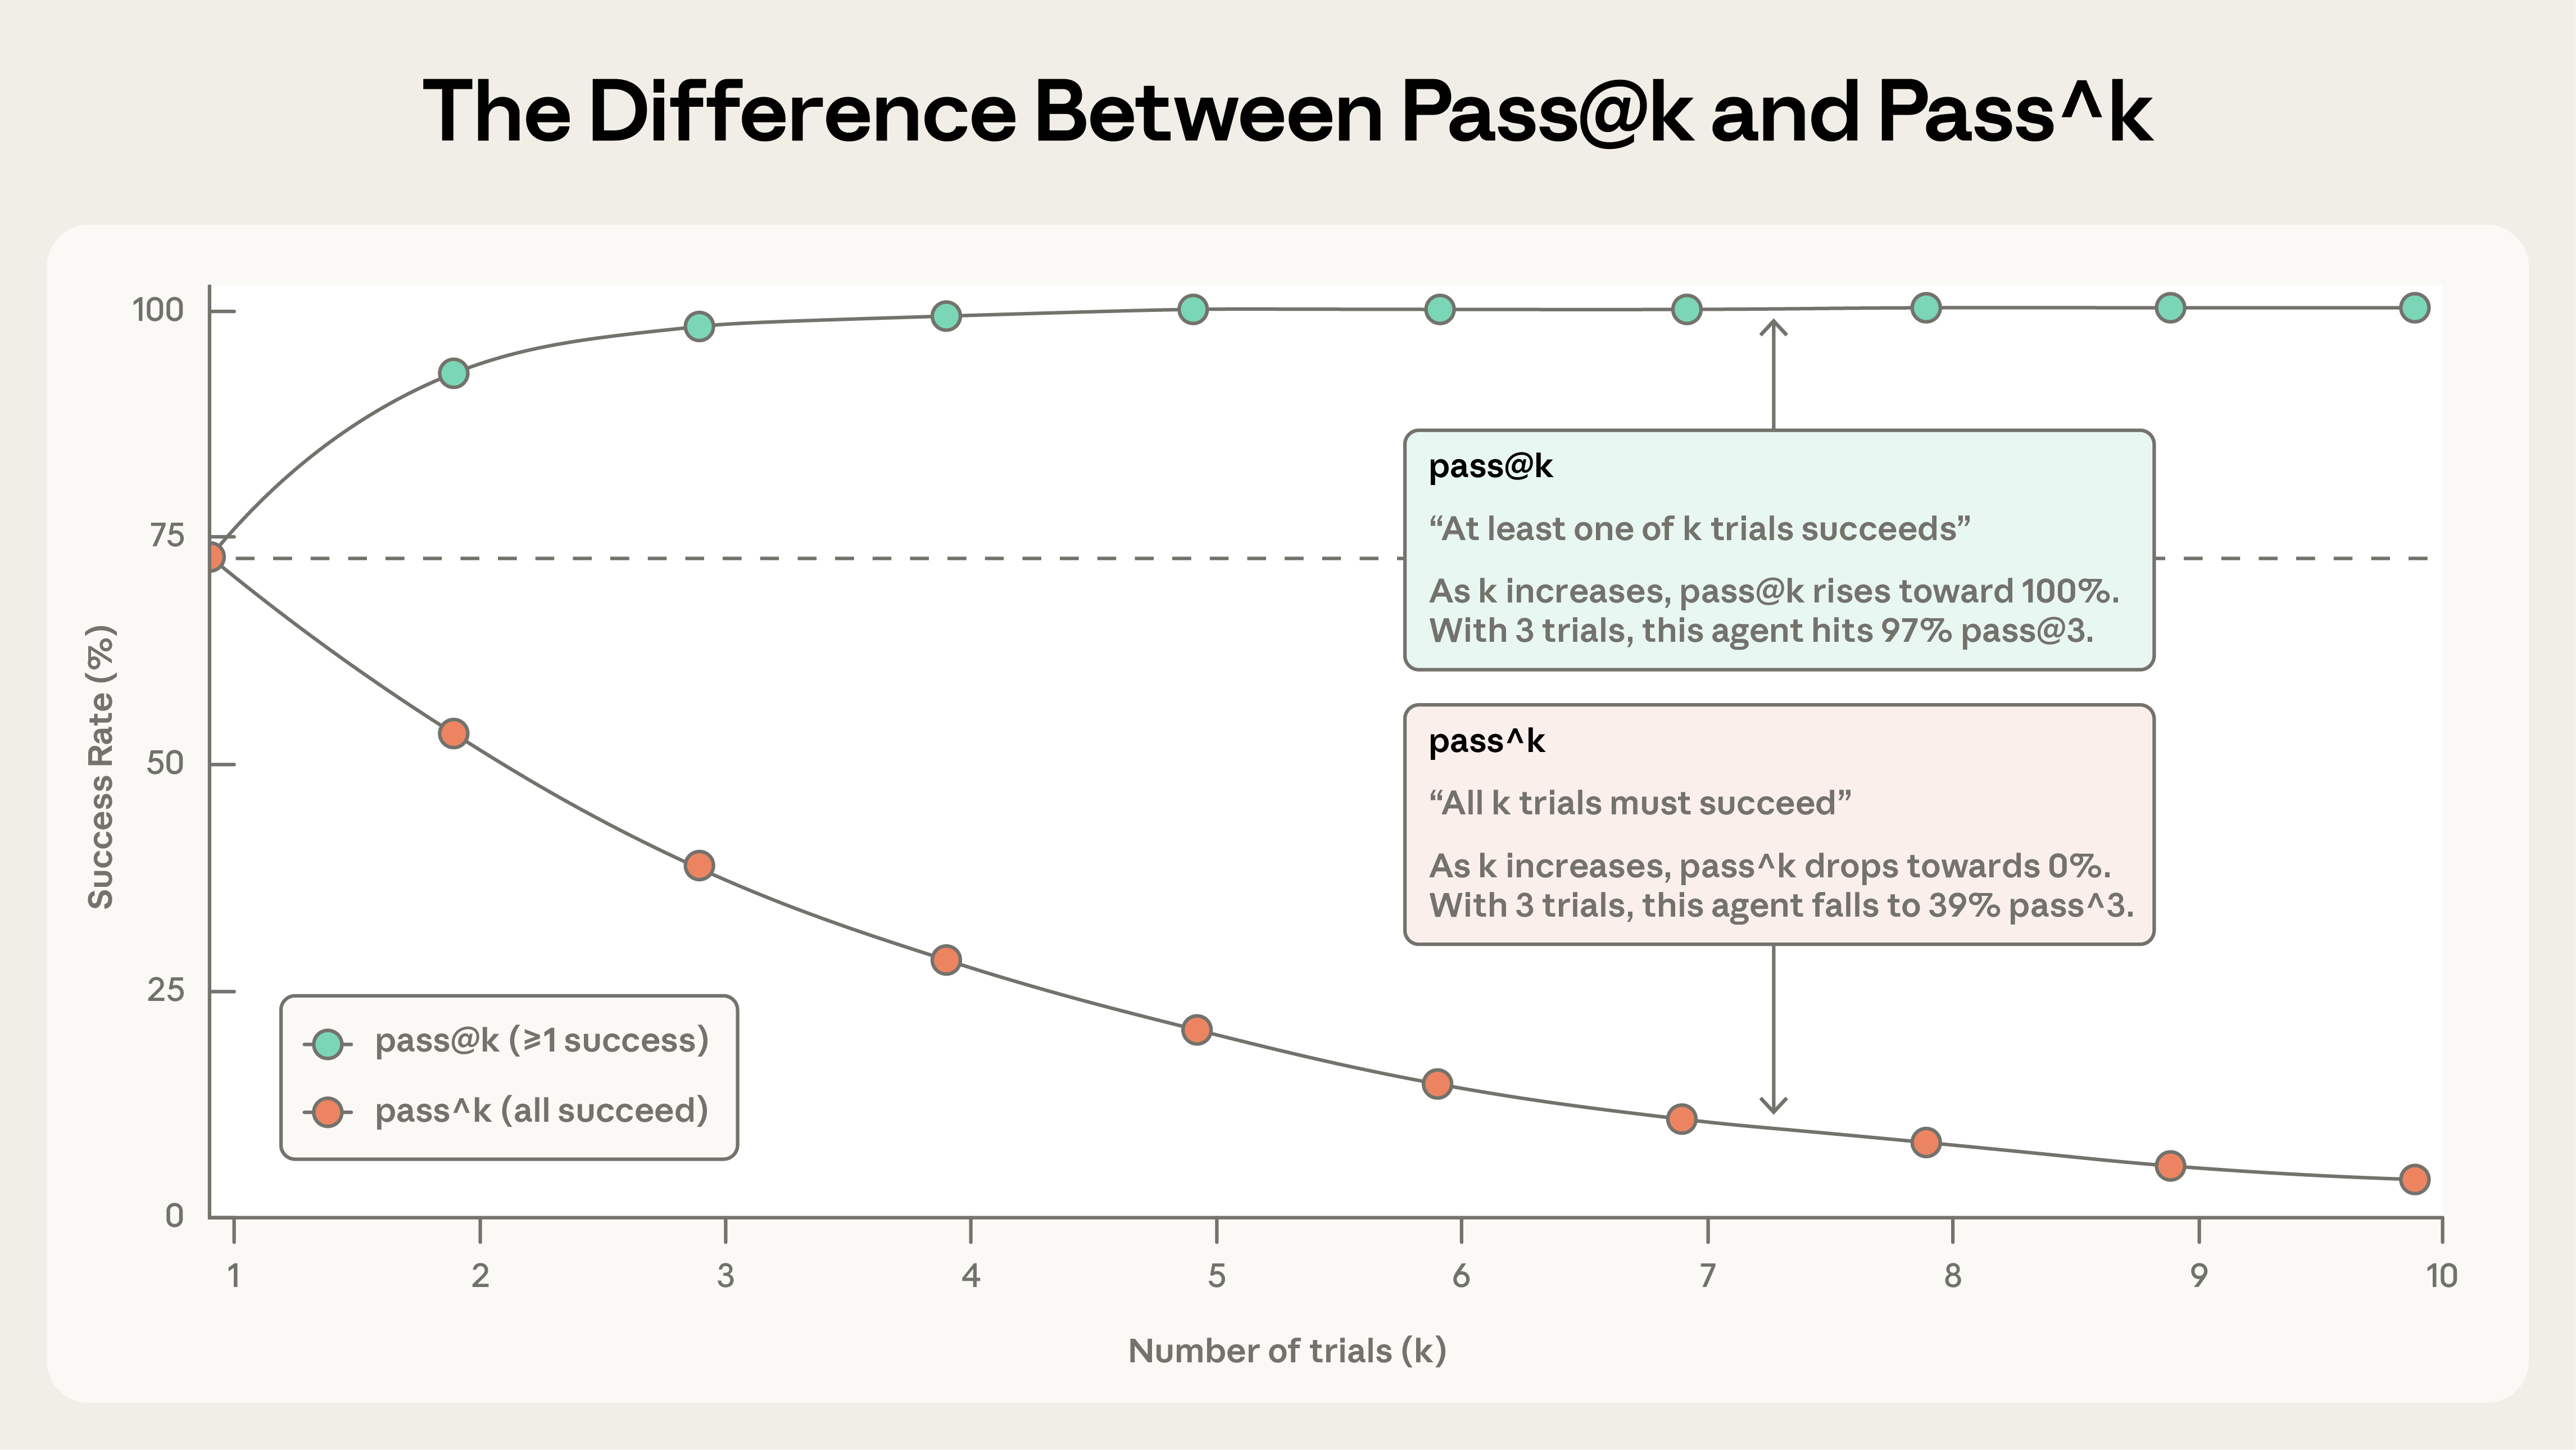
pass@k and pass^k diverge as trials increase.
随着试验次数增加,pass@k 与 pass^k 会出现分化。
At k=1, they're identical (both equal the per-trial success rate).
当 k=1 时,两者相同(都等于单次试验成功率)。
By k=10, they tell opposite stories: pass@k approaches 100% while pass^k falls to 0%.
到 k=10 时,它们讲述了相反的情况:pass@k 接近 100%,而 pass^k 降到 0%。
Both metrics are useful, and which to use depends on product requirements: pass@k for tools where one success matters, pass^k for agents where consistency is essential.
两个指标都有用,使用哪一个取决于产品需求:对于一次成功就足够的工具,使用 pass@k;对于一致性至关重要的智能体,使用 pass^k。
This section lays out our practical, field-tested advice for going from no evals to evals you can trust.
本节给出我们的实用且经过实践检验的建议,帮助你从没有评测到拥有可信赖的评测。
Think of this as a roadmap for eval-driven agent development: define success early, measure it clearly, and iterate continuously.
可以把它看作以评测驱动的智能体开发路线图:尽早定义成功、清晰地衡量它,并持续迭代。
Step 0.
第 0 步。
Start early
尽早开始
We see teams delay building evals because they think they need hundreds of tasks.
我们看到团队迟迟不构建评测,因为他们认为自己需要数百个任务。
In reality, 20-50 simple tasks drawn from real failures is a great start.
实际上,从真实失败中提取的 20-50 个简单任务就是一个很好的起点。
After all, in early agent development, each change to the system often has a clear, noticeable impact, and this large effect size means small sample sizes suffice.
毕竟,在智能体开发的早期,对系统的每次改动通常都有清晰、显著的影响,而这种大的效应量意味着小样本量就足够了。
More mature agents may need larger, more difficult evals to detect smaller effects, but it’s best to take the 80/20 approach in the beginning.
更成熟的智能体可能需要更大、更难的评测来检测更小的效应,但一开始最好采用 80/20 方法。
Evals get harder to build the longer you wait.
你等得越久,评测就越难构建。
Early on, product requirements naturally translate into test cases.
早期,产品需求会自然地转化为测试用例。
Wait too long and you're reverse-engineering success criteria from a live system.
等得太久,你就得从线上系统中反向推导成功标准。
Step 1.
步骤 1。
Start with what you already test manually
从你已经手动测试的内容开始
Begin with the manual checks you run during development—the behaviors you verify before each release and common tasks end users try.
从你在开发期间执行的手动检查开始——你在每次发布前验证的行为,以及最终用户尝试的常见任务。
If you're already in production, look at your bug tracker and support queue.
如果你已经在生产环境中,查看你的 bug 跟踪器和支持队列。
Converting user-reported failures into test cases ensures your suite reflects actual usage; prioritizing by user impact helps you invest effort where it counts.
将用户报告的失败转化为测试用例,可确保你的评测套件反映实际使用情况;按用户影响排定优先级,有助于你把精力投入到最关键的地方。
Step 2: Write unambiguous tasks with reference solutions
步骤 2:编写带有参考解的无歧义任务
Getting task quality right is harder than it seems.
把任务质量做对,比看起来更难。
A good task is one where two domain experts would independently reach the same pass/fail verdict.
一个好的任务是两位领域专家能独立得出相同通过/失败结论的任务。
Could they pass the task themselves?
他们自己能通过这个任务吗?
If not, the task needs refinement.
如果不能,任务就需要改进。
Ambiguity in task specifications becomes noise in metrics.
任务说明中的歧义会变成指标中的噪声。
The same applies to criteria for model-based graders: vague rubrics produce inconsistent judgments.
这同样适用于基于模型的评分器的标准:模糊的评分规则会产生不一致的判断。
Each task should be passable by an agent that follows instructions correctly.
每个任务都应该能被一个正确遵循指令的智能体通过。
This can be subtle.
这一点可能很微妙。
For instance, auditing Terminal-Bench revealed that if a task asks the agent to write a script but doesn’t specify a filepath, and the tests assume a particular filepath for the script, the agent might fail through no fault of its own.
例如,审计 Terminal-Bench 时发现,如果一个任务要求智能体编写脚本但没有指定文件路径,而测试又假定脚本位于特定文件路径,那么智能体可能会在并非自身过错的情况下失败。
Everything the grader checks should be clear from the task description; agents shouldn’t fail due to ambiguous specs.
评分器检查的所有内容都应该能从任务描述中明确看出;智能体不应因为模糊的规格而失败。
With frontier models, a 0% pass rate across many trials (i.e. 0% pass@100) is most often a signal of a broken task, not an incapable agent, and a sign to double-check your task specification and graders.
对于前沿模型,在许多试验中 0% 的通过率(即 0% pass@100)通常是任务有问题的信号,而不是智能体无能的信号,也提示你需要复核任务说明和评分器。
For each task, it’s useful to create a reference solution: a known working output that passes all graders.
对于每个任务,创建一个参考解是很有用的:一个已知能通过所有评分器的工作输出。
This proves that the task is solvable and verifies graders are correctly configured.
这证明了任务可解,并验证评分器配置正确。
Step 3: Build balanced problem sets
第 3 步:构建平衡的问题集
Test both the cases where a behavior should occur and where it shouldn't.
既要测试行为应当发生的情况,也要测试不应当发生的情况。
One-sided evals create one-sided optimization.
单边评测会导致单边优化。
For instance, if you only test whether the agent searches when it should, you might end up with an agent that searches for almost everything.
例如,如果你只测试智能体在应当搜索时是否搜索,最终可能会得到一个几乎什么都搜索的智能体。
Try to avoid class-imbalanced evals.
尽量避免类别不平衡的评测。
We learned this firsthand when building evals for web search in Claude.ai.
我们在为 Claude.ai 构建网页搜索评测时亲身学到了这一点。
The challenge was preventing the model from searching when it shouldn’t, while preserving its ability to do extensive research when appropriate.
挑战在于,既要阻止模型在不该搜索时进行搜索,又要保留其在适当时进行广泛研究的能力。
The team built evals covering both directions: queries where the model should search (like finding the weather) and queries where it should answer from existing knowledge (like “who founded Apple?”).
团队构建了覆盖两个方向的评测:模型应当搜索的查询(例如查找天气),以及模型应当基于已有知识回答的查询(例如“谁创立了 Apple?”)。
Striking the right balance between undertriggering (not searching when it should) or overtriggering (searching when it shouldn’t) was difficult, and took many rounds of refinements to both the prompts and the eval.
在触发不足(undertriggering,即本应搜索时却没有搜索)与触发过度(overtriggering,即本不该搜索时却搜索)之间取得恰当平衡很困难,并且需要对提示词和评测进行多轮改进。
As more example problems come up, we continue to add to evals to improve our coverage.
随着更多示例问题出现,我们会持续为评测添加内容,以提升覆盖范围。
Step 4: Build a robust eval harness with a stable environment
第 4 步:构建具有稳定环境的稳健评测框架
It’s essential that the agent in the eval functions roughly the same as the agent used in production, and that the environment itself doesn’t introduce further noise.
至关重要的是,评测中的智能体运行方式与生产环境中使用的智能体大致相同,并且环境本身不会引入额外噪声。
Each trial should be “isolated” by starting from a clean environment.
每次试验都应通过从干净环境开始来实现“隔离”。
Unnecessary shared state between runs (leftover files, cached data, resource exhaustion) can cause correlated failures due to infrastructure flakiness rather than agent performance.
运行之间不必要的共享状态(残留文件、缓存数据、资源耗尽)可能导致相关性故障,其原因在于基础设施不稳定,而非智能体表现。
Shared state can also artificially inflate performance.
共享状态也可能人为抬高表现。
For example, in some internal evals we observed Claude gaining an unfair advantage on some tasks by examining the git history from previous trials.
例如,在一些内部评测中,我们观察到 Claude 通过检查之前试验的 git 历史,在某些任务上获得了不公平的优势。
If multiple distinct trials fail because of the same limitation in the environment (like limited CPU memory), these trials are not independent because they’re affected by the same factor, and the eval results become unreliable for measuring agent performance.
如果多个不同的试验因环境中的同一限制(如有限的 CPU 内存)而失败,那么这些试验就不是独立的,因为它们受到同一因素的影响,评测结果也就无法可靠地衡量智能体表现。
Step 5: Design graders thoughtfully
第 5 步:审慎设计评分器
As discussed above, great eval design involves choosing the best graders for the agent and the tasks.
如上所述,优秀的评测设计包括为智能体和任务选择最佳的评分器。
We recommend choosing deterministic graders where possible, LLM graders where necessary or for additional flexibility, and using human graders judiciously for additional validation.
我们建议在可能时选择确定性评分器,在必要时或为了获得额外灵活性时选择 LLM 评分器,并审慎使用人工评分器进行额外验证。
There is a common instinct to check that agents followed very specific steps like a sequence of tool calls in the right order.
有一种常见的本能,就是检查智能体是否遵循了非常具体的步骤,比如按正确顺序执行一系列工具调用。
We’ve found this approach too rigid and results in overly brittle tests, as agents regularly find valid approaches that eval designers didn’t anticipate.
我们发现这种方法过于僵化,会导致测试过于脆弱,因为智能体经常会找到评测设计者未曾预料到的有效方法。
So as not to unnecessarily punish creativity, it’s often better to grade what the agent produced, not the path it took.
为了不无谓地惩罚创造力,通常更好的做法是对智能体产出的结果评分,而不是对它采取的路径评分。
For tasks with multiple components, build in partial credit.
对于包含多个组件的任务,要设置部分得分。
A support agent that correctly identifies the problem and verifies the customer but fails to process a refund is meaningfully better than one that fails immediately.
一个客服智能体如果正确识别了问题并验证了客户身份,但未能处理退款,那它也比一个立即失败的智能体要好得多。
It’s important to represent this continuum of success in results.
在结果中体现这种成功程度的连续性很重要。
Model grading often takes careful iteration to validate accuracy.
模型评分通常需要仔细迭代来验证准确性。
LLM-as-judge graders should be closely calibrated with human experts to gain confidence that there is little divergence between the human grading and model grading.
LLM-as-judge 评分器应与人类专家密切校准,以确信人类评分与模型评分之间几乎没有分歧。
To avoid hallucinations, give the LLM a way out, like providing an instruction to return “Unknown” when it doesn’t have enough information.
为避免幻觉,给 LLM 一条退路,比如提供一条指令,让它在信息不足时返回“Unknown”。
It can also help to create clear, structured rubrics to grade each dimension of a task, and then grade each dimension with an isolated LLM-as-judge rather than using one to grade all dimensions.
创建清晰、结构化的评分标准来对任务的每个维度评分也会有所帮助,然后用一个独立的 LLM-as-judge 对每个维度分别评分,而不是用一个 LLM-as-judge 给所有维度评分。
Once the system is robust, it’s sufficient to use human review only occasionally.
一旦系统足够稳健,只需偶尔进行人工审核就足够了。
Some evaluations have subtle failure modes that result in low scores even with good agent performance, as the agent fails to solve tasks due to grading bugs, agent harness constraints, or ambiguity.
有些评测存在微妙的失败模式,即使智能体表现良好也会导致低分,因为智能体因评分缺陷、智能体框架约束或歧义而无法解决任务。
Even sophisticated teams can miss these issues.
即使是经验丰富的团队也可能忽略这些问题。
For example, Opus 4.5 initially scored 42% on CORE-Bench, until an Anthropic researcher found multiple issues: rigid grading that penalized “96.12” when expecting “96.124991…”, ambiguous task specs, and stochastic tasks that were impossible to reproduce exactly.
例如,Opus 4.5 在 CORE-Bench 上最初得分为 42%,直到一位 Anthropic 研究员发现了多个问题:僵化的评分在期望“96.124991…”时却惩罚“96.12”、模糊的任务说明,以及无法精确复现的随机任务。
After fixing bugs and using a less constrained scaffold, Opus 4.5’s score jumped to 95%.
在修复 bug 并使用约束更少的脚手架后,Opus 4.5 的得分跃升至 95%。
Similarly, METR discovered several misconfigured tasks in their time horizon benchmark that asked agents to optimize to a stated score threshold, but the grading required exceeding that threshold.
同样,METR 在其时间跨度基准测试中发现了几个配置错误的任务,这些任务要求智能体优化到某个声明的分数阈值,但评分却要求超过该阈值。
This penalized models like Claude for following the instructions, while models that ignored the stated goal received better scores.
这惩罚了像 Claude 这样遵循指令的模型,而忽略既定目标的模型反而获得了更高的分数。
Carefully double-checking tasks and graders can help avoid these problems.
仔细复核任务和评分器有助于避免这些问题。
Make your graders resistant to bypasses or hacks.
让你的评分器难以被绕过或取巧。
The agent shouldn’t be able to easily “cheat” the eval.
智能体不应能轻易“作弊”通过评测。
Tasks and graders should be designed so that passing genuinely requires solving the problem rather than exploiting unintended loopholes.
任务和评分器的设计应确保通过评测真正需要解决问题,而不是利用意外的漏洞。
Step 6: Check the transcripts
第 6 步:检查转录记录
You won't know if your graders are working well unless you read the transcripts and grades from many trials.
除非你阅读许多 trial 的 transcript 和评分,否则你不会知道你的 grader 是否工作良好。
At Anthropic, we invested in tooling for viewing eval transcripts and we regularly take the time to read them.
在 Anthropic,我们投入建设了用于查看 eval transcript 的工具,并且我们定期花时间阅读它们。
When a task fails, the transcript tells you whether the agent made a genuine mistake or whether your graders rejected a valid solution.
当一个任务失败时,transcript 会告诉你智能体是犯了真正的错误,还是你的 grader 拒绝了一个有效的解决方案。
It also often surfaces key details about agent and eval behavior.
它也常常暴露出关于智能体和 eval 行为的关键细节。
Failures should seem fair: it’s clear what the agent got wrong and why.
失败应当显得公平:智能体错在哪里以及为什么错,都清晰明了。
When scores don’t climb, we need confidence that it’s due to agent performance and not the eval.
当分数不再攀升时,我们需要确信这是由于智能体的表现,而不是 eval。
Reading transcripts is how you verify that your eval is measuring what actually matters, and is a critical skill for agent development.
阅读 transcript 是你验证 eval 是否在衡量真正重要之事的方式,也是智能体开发的一项关键技能。
Step 7: Monitor for capability eval saturation
第 7 步:监控能力 eval 饱和。
An eval at 100% tracks regressions but provides no signal for improvement.
一个达到 100% 的 eval 能跟踪 regression,但不提供改进信号。
Eval saturation occurs when an agent passes all of the solvable tasks, leaving no room for improvement.
当智能体通过了所有可解决的任务、没有留下改进空间时,就会发生 eval 饱和。
For instance, SWE-Bench Verified scores started at 30% this year, and frontier models are now nearing saturation at >80%.
例如,SWE-Bench Verified 的分数今年从 30% 起步,而前沿模型现在正接近饱和,超过 80%。
As evals approach saturation, progress will also slow, as only the most difficult tasks remain.
随着 eval 接近饱和,进展也会放缓,因为只剩下最困难的任务。
This can make results deceptive, as large capability improvements appear as small increases in scores.
这可能使结果具有欺骗性,因为巨大的能力提升只表现为分数的小幅增长。
For example, the code review startup Qodo was initially unimpressed by Opus 4.5 because their one-shot coding evals didn’t capture the gains on longer, more complex tasks.
例如,代码审查初创公司 Qodo 最初对 Opus 4.5 印象不深,因为他们的一次性编码 eval 没有捕捉到在更长、更复杂任务上的提升。
In response, they developed a new agentic eval framework, providing a much clearer picture of progress.
作为回应,他们开发了一个新的智能体 eval 框架,提供了对进展更清晰的图景。
As a rule, we do not take eval scores at face value until someone digs into the details of the eval and reads some transcripts.
通常,除非有人深入探究 eval 的细节并阅读一些 transcript,否则我们不会只看 eval 分数的表面值。
If grading is unfair, tasks are ambiguous, valid solutions are penalized, or the harness constrains the model, the eval should be revised.
如果评分不公平、任务有歧义、有效的解决方案被惩罚,或者 harness 限制了模型,那么就应当修订 eval。
Step 8: Keep evaluation suites healthy long-term through open contribution and maintenance
第 8 步:通过开放贡献和维护,长期保持 evaluation suite 健康。
An eval suite is a living artifact that needs ongoing attention and clear ownership to remain useful.
评测套件是一种持续演进的产物,需要持续关注和明确的责任归属才能保持有用。
At Anthropic, we experimented with various approaches to eval maintenance.
在 Anthropic,我们试验了各种评测维护方法。
What proved most effective was establishing dedicated evals teams to own the core infrastructure, while domain experts and product teams contribute most eval tasks and run the evaluations themselves.
最有效的方法是建立专职评测团队来负责核心基础设施,同时由领域专家和产品团队贡献大部分评测任务并自己运行评测。
For AI product teams, owning and iterating on evaluations should be as routine as maintaining unit tests.
对 AI 产品团队而言,拥有并迭代评测应该像维护单元测试一样常规。
Teams can waste weeks on AI features that “work” in early testing but fail to meet unstated expectations that a well-designed eval would have surfaced early.
团队可能在一个 AI 功能上浪费数周,该功能在早期测试中“能用”,却未能满足未言明的期望,而一个设计良好的评测本可以早早暴露这些期望。
Defining eval tasks is one of the best ways to stress-test whether the product requirements are concrete enough to start building.
定义评测任务是压力测试产品需求是否足够具体、可以开始构建的最佳方式之一。
We recommend practicing eval-driven development: build evals to define planned capabilities before agents can fulfill them, then iterate until the agent performs well.
我们建议实践评测驱动开发(eval-driven development):在智能体能够实现计划中的能力之前,先构建评测来定义这些能力,然后迭代直到智能体表现良好。
Internally, we often build features that work “well enough” today but are bets on what models can do in a few months.
在内部,我们经常构建今天“足够好”的功能,但它们是对模型几个月后能做什么的押注。
Capability evals that start at a low pass rate make this visible.
起始通过率很低的能力评测(capability evals)让这一点变得可见。
When a new model drops, running the suite quickly reveals which bets paid off.
当新模型发布时,运行该套件能快速揭示哪些押注得到了回报。
The people closest to product requirements and users are best positioned to define success.
最接近产品需求和用户的人最适合定义成功。
With current model capabilities, product managers, customer success managers, or salespeople can use Claude Code to contribute an eval task as a PR—let them!
借助当前的模型能力,产品经理、客户成功经理或销售人员可以使用 Claude Code 以 PR 的形式贡献一个评测任务——让他们做吧!
Or, even better, actively enable them.
或者更好的是,主动赋能他们。
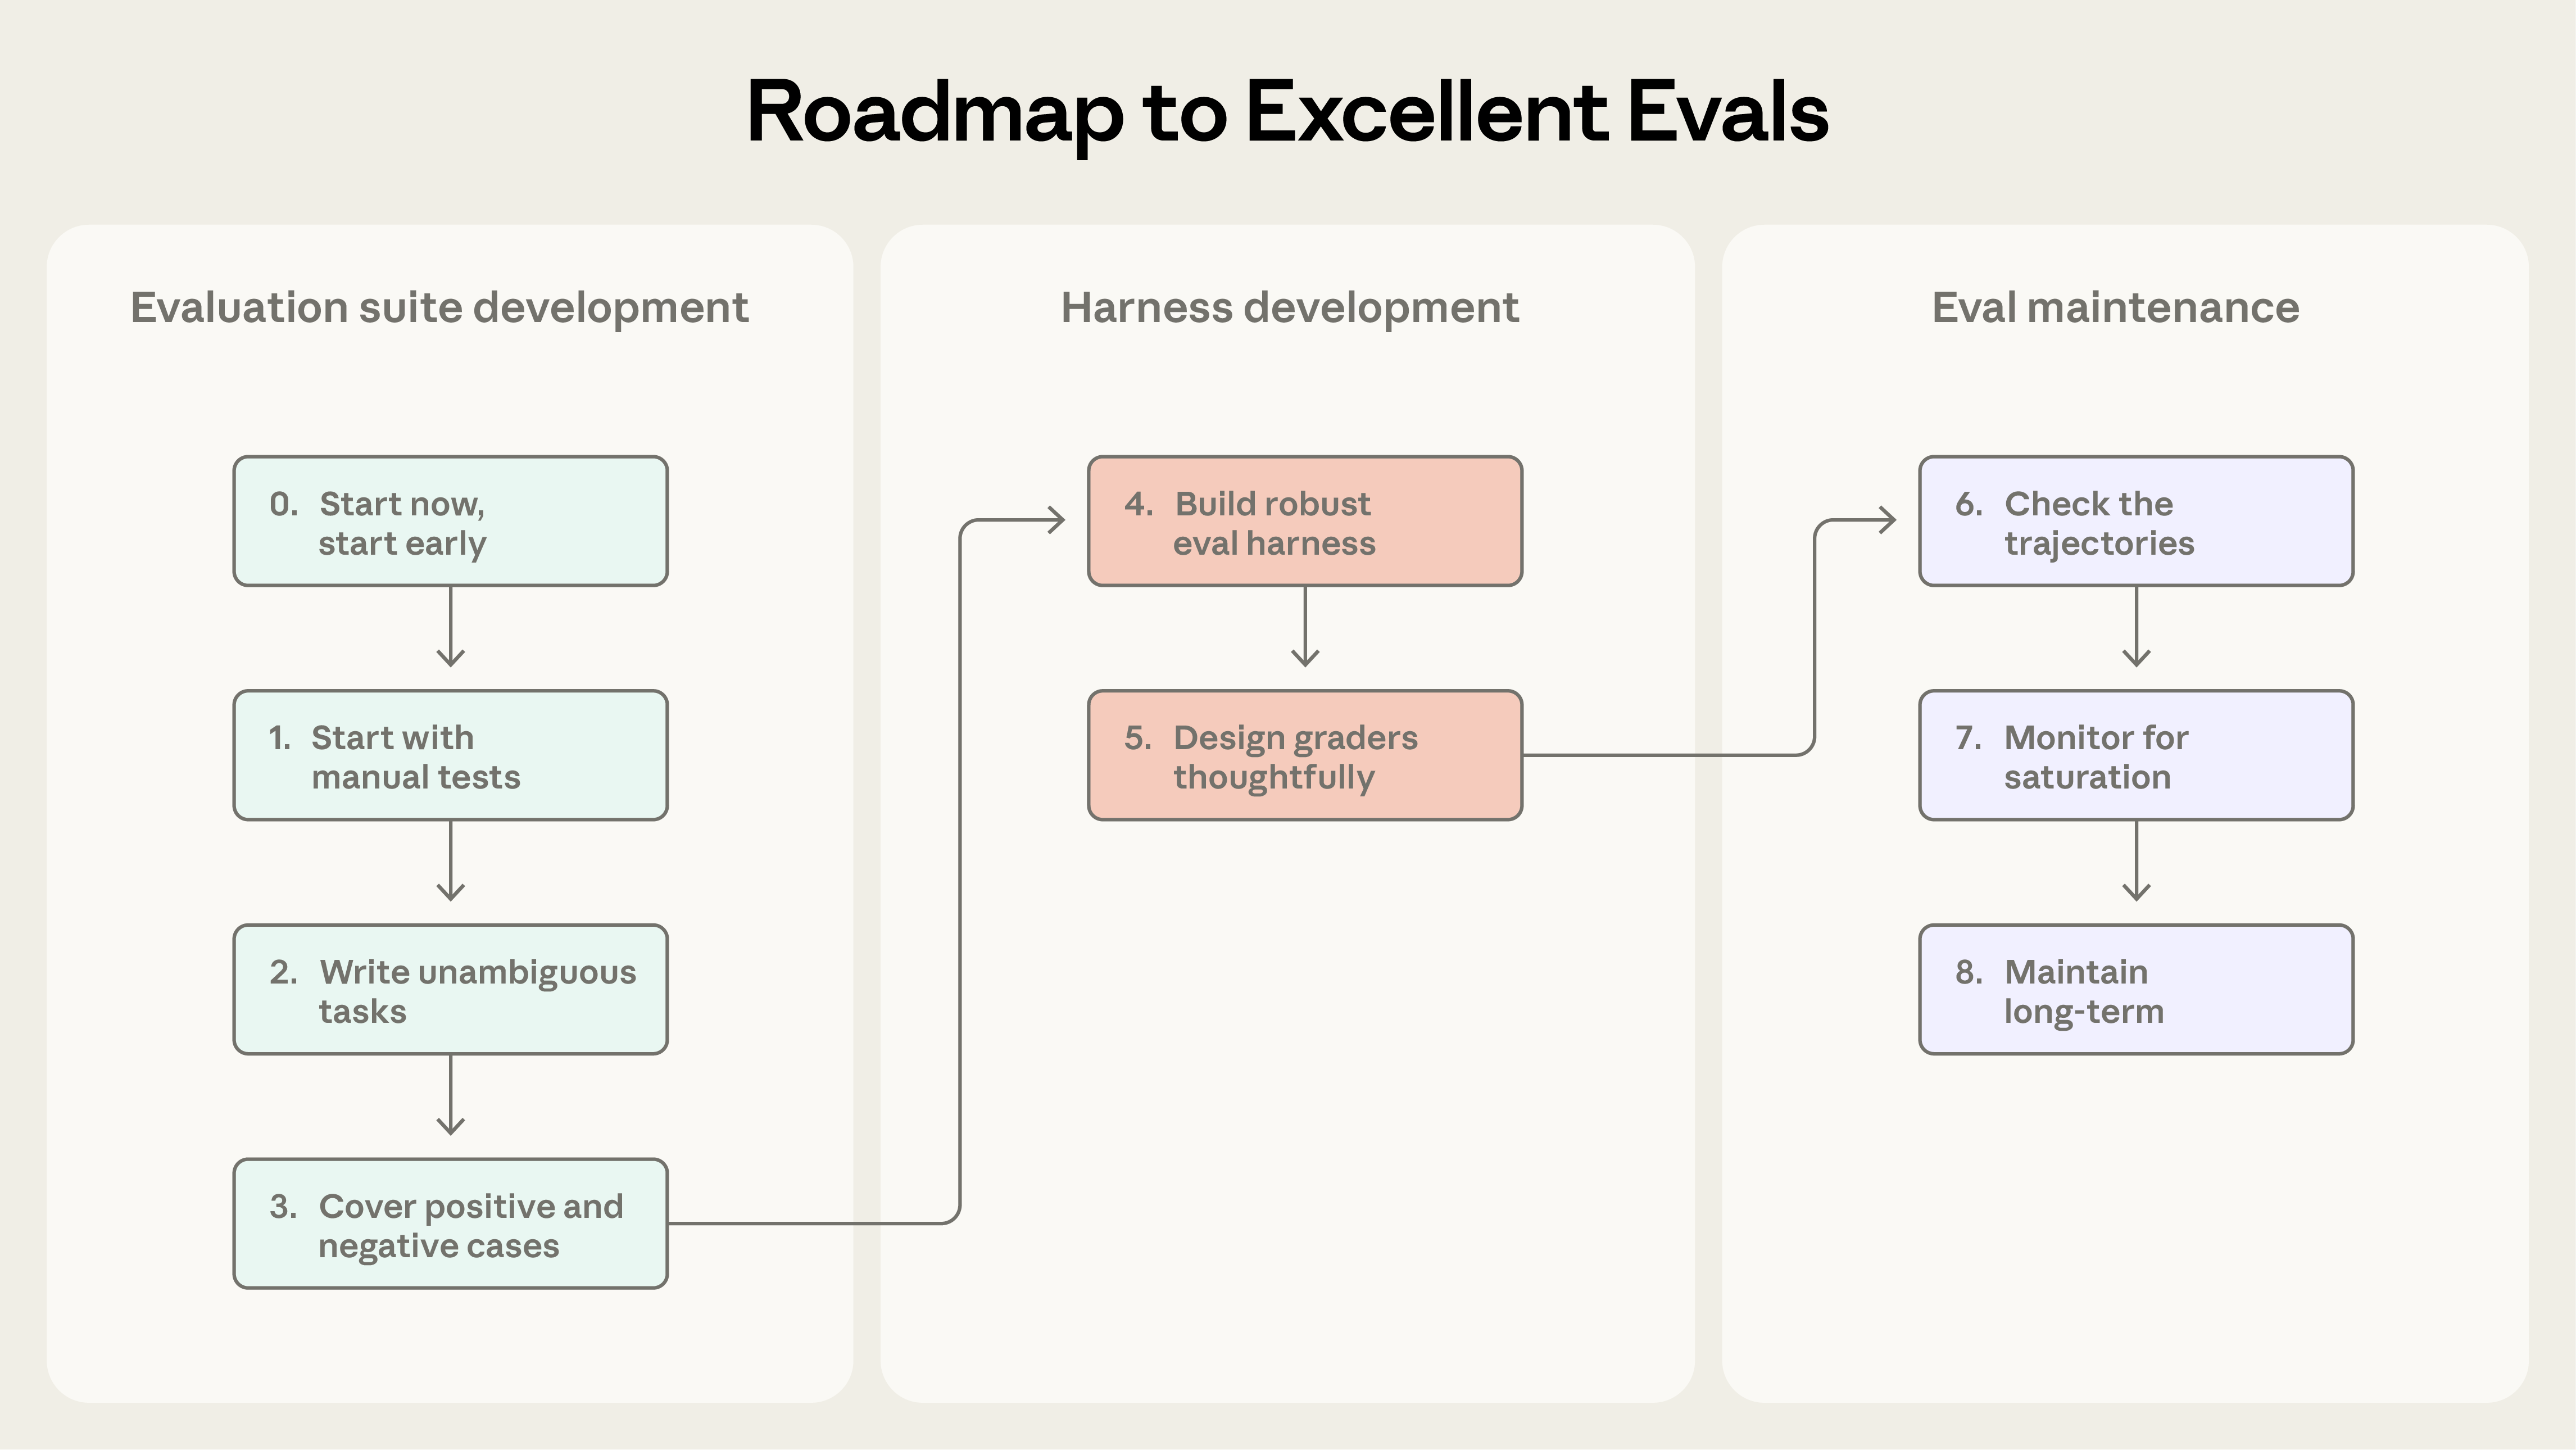
The process of creating an effective evaluation.
创建有效评测的过程。
Automated evaluations can be run against an agent in thousands of tasks without deploying to production or affecting real users.
自动化评测可以在数千个任务中针对智能体(agent)运行,而无需部署到生产环境或影响真实用户。
But this is just one of many ways to understand agent performance.
但这只是了解智能体性能的众多方式之一。
A complete picture includes production monitoring, user feedback, A/B testing, manual transcript review, and systematic human evaluation.
完整的图景包括生产监控(production monitoring)、用户反馈(user feedback)、A/B 测试(A/B testing)、人工记录审查(manual transcript review)和系统性人工评估(systematic human evaluation)。
Method
方法
Pros
优点
Cons
缺点
Automated evals Running tests programmatically without real users
自动化评测:以编程方式运行测试,无需真实用户
Production monitoring Tracking metrics and errors in live systems
生产监控:跟踪实时系统中的指标和错误
A/B testing Comparing variants with real user traffic
A/B 测试:比较变体与真实用户流量
User feedback Explicit signals like thumbs-down or bug reports
用户反馈:如点踩或错误报告等明确信号
Manual transcript review Humans reading through agent conversations
人工转录审查:人类通读智能体对话。
Systematic human studies Structured grading of agent outputs by trained raters
系统性人工研究:由训练有素的评分者对智能体输出进行结构化评分。
These methods map to different stages of agent development.
这些方法对应智能体开发的不同阶段。
Automated evals are especially useful pre-launch and in CI/CD, running on each agent change and model upgrade as the first line of defense against quality problems.
自动化评测在发布前和 CI/CD 中尤其有用,在每次智能体变更和模型升级时运行,作为抵御质量问题的第一道防线。
Production monitoring kicks in post-launch to detect distribution drift and unanticipated real-world failures.
生产监控在发布后启动,用于检测分布漂移(distribution drift)和未预料到的真实世界故障。
A/B testing validates significant changes once you have sufficient traffic.
一旦有足够的流量,A/B testing 会验证重大变更。
User feedback and transcript review are ongoing practices to fill the gaps: triage feedback constantly, sample transcripts to read weekly, and dig deeper as needed.
用户反馈和转录审查是持续进行的实践,以填补空白:不断分诊反馈,每周抽样阅读转录,并按需深入调查。
Reserve systematic human studies for calibrating LLM graders or evaluating subjective outputs where human consensus serves as the reference standard.
将系统性人工研究保留用于校准 LLM 评分器,或评测主观输出——在这些场景中,人类共识作为参考标准。
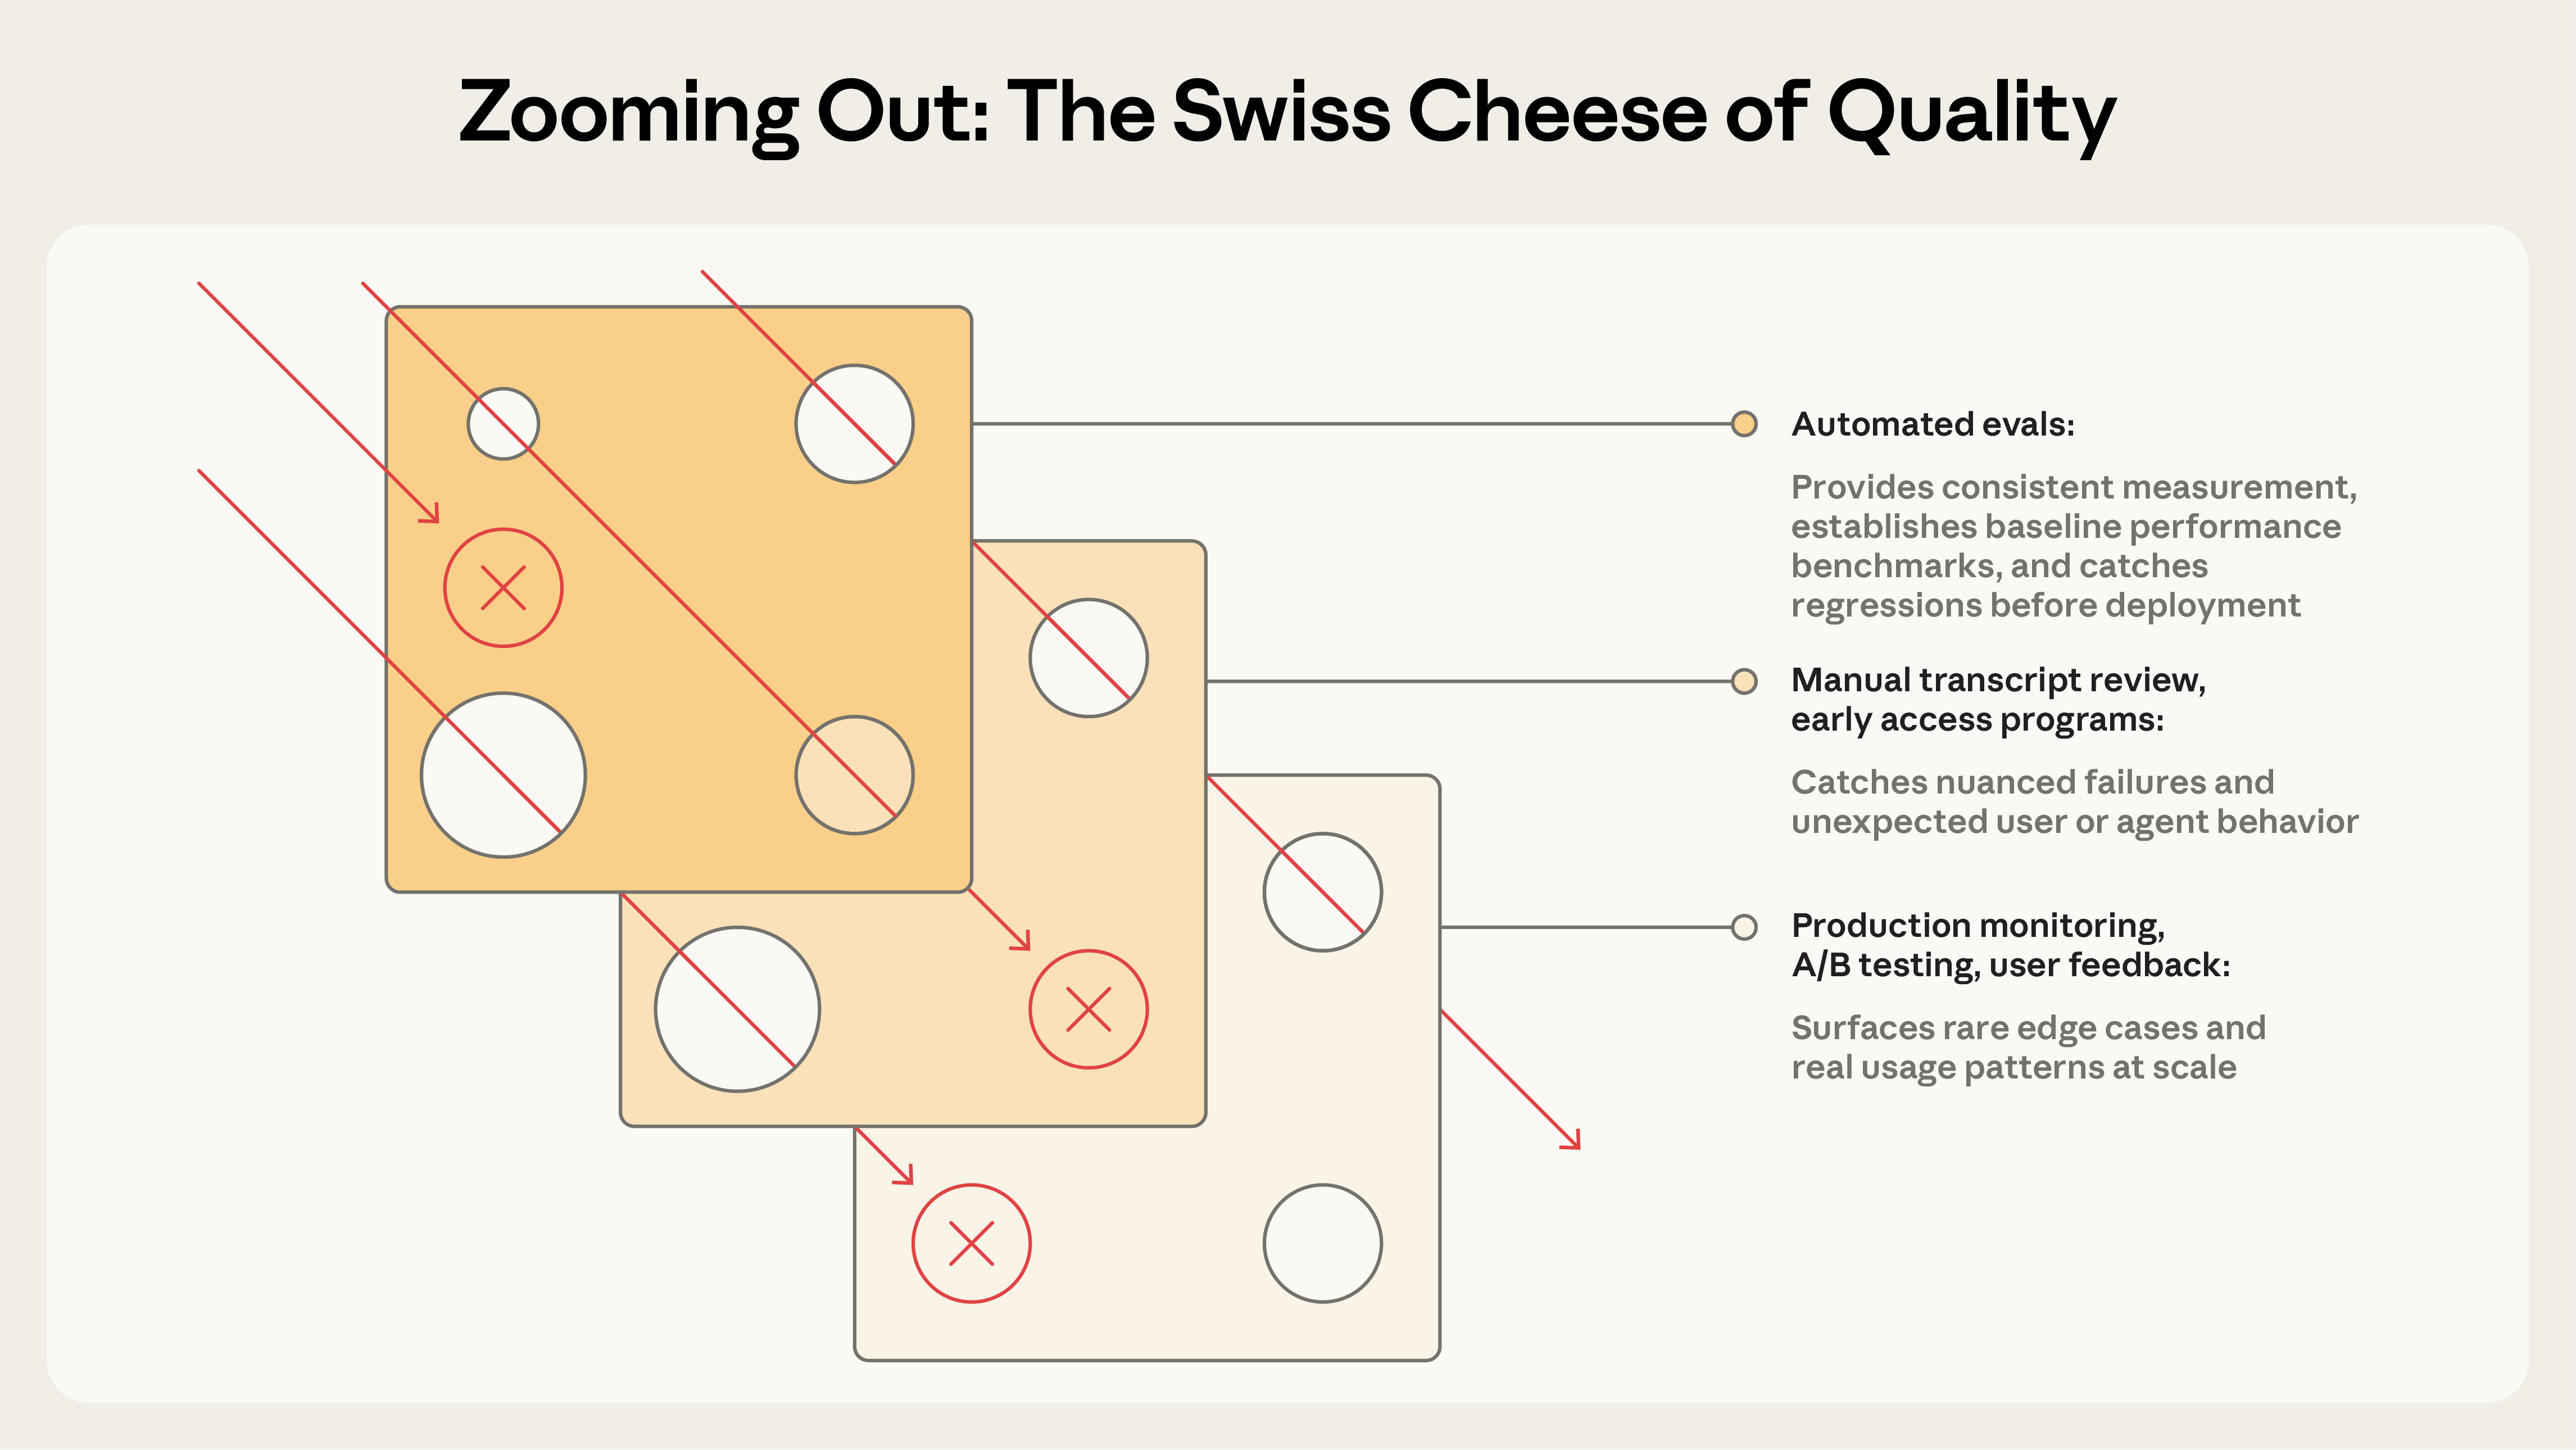
Like the Swiss Cheese Model from safety engineering, no single evaluation layer catches every issue.
就像安全工程中的瑞士奶酪模型(Swiss Cheese Model)一样,没有单一评测层能捕获所有问题。
With multiple methods combined, failures that slip through one layer are caught by another.
将多种方法组合起来,从一个层漏掉的故障会被另一个层捕获。
The most effective teams combine these methods: automated evals for fast iteration, production monitoring for ground truth, and periodic human review for calibration.
最有效的团队会组合这些方法:用自动化评测实现快速迭代,用生产监控获取真实基准,以及用定期人工审查进行校准。
Teams without evals get bogged down in reactive loops—fixing one failure, creating another, unable to distinguish real regressions from noise.
没有评测的团队会陷入被动循环——修复一个故障,又制造另一个故障,无法区分真正的回归和噪声。
Teams that invest early find the opposite: development accelerates as failures become test cases, test cases prevent regressions, and metrics replace guesswork.
早早投入的团队则发现相反的情况:随着故障变成测试用例、测试用例防止回归、指标取代猜测,开发会加速。
Evals give the whole team a clear hill to climb, turning “the agent feels worse” into something actionable.
评测给整个团队一个明确的目标,把“智能体感觉变差了”变成可操作的事项。
The value compounds, but only if you treat evals as a core component, not an afterthought.
这种价值会累积,但前提是你把评测视为核心组件,而不是事后补丁。
The patterns vary by agent type, but the fundamentals described here are constant.
这些模式会因智能体类型而异,但这里描述的基本原理是不变的。
Start early and don’t wait for the perfect suite.
尽早开始,不要等待完美的评测套件。
Source realistic tasks from the failures you see.
从你看到的失败中获取真实任务。
Define unambiguous, robust success criteria.
定义明确、稳健的成功标准。
Design graders thoughtfully and combine multiple types.
审慎设计评分器,并组合多种类型。
Make sure the problems are hard enough for the model.
确保问题对模型来说足够难。
Iterate on the evaluations to improve their signal-to-noise ratio.
对评测进行迭代,以提高其信噪比。
Read the transcripts!
阅读 transcript!
AI agent evaluation is still a nascent, fast-evolving field.
AI 智能体评测仍是一个新兴且快速演进的领域。
As agents take on longer tasks, collaborate in multi-agent systems, and handle increasingly subjective work, we will need to adapt our techniques.
随着智能体承担更长的任务、在多智能体系统中协作,并处理日益主观的工作,我们将需要调整我们的技术。
We’ll keep sharing best practices as we learn more.
随着我们了解更多,我们会继续分享最佳实践。
Written by Mikaela Grace, Jeremy Hadfield, Rodrigo Olivares, and Jiri De Jonghe.
作者:Mikaela Grace、Jeremy Hadfield、Rodrigo Olivares 和 Jiri De Jonghe。
We're also grateful to David Hershey, Gian Segato, Mike Merrill, Alex Shaw, Nicholas Carlini, Ethan Dixon, Pedram Navid, Jake Eaton, Alyssa Baum, Lina Tawfik, Karen Zhou, Alexander Bricken, Sam Kennedy, Robert Ying, and others for their contributions.
我们也感谢 David Hershey、Gian Segato、Mike Merrill、Alex Shaw、Nicholas Carlini、Ethan Dixon、Pedram Navid、Jake Eaton、Alyssa Baum、Lina Tawfik、Karen Zhou、Alexander Bricken、Sam Kennedy、Robert Ying 以及其他人的贡献。
Special thanks to the customers and partners we have learned from through collaborating on evals, including iGent, Cognition, Bolt, Sierra, Vals.ai, Macroscope, PromptLayer, Stripe, Shopify, the Terminal Bench team, and more.
特别感谢我们通过协作开展评测而向其学习的客户和合作伙伴,包括 iGent、Cognition、Bolt、Sierra、Vals.ai、Macroscope、PromptLayer、Stripe、Shopify、Terminal Bench 团队等。
This work reflects the collective efforts of several teams who helped develop the practice of evaluations at Anthropic.
这项工作反映了 Anthropic 内部多个团队的集体努力,他们帮助发展了评测实践。
Several open-source and commercial frameworks can help teams implement agent evaluations without building infrastructure from scratch.
若干开源(open-source)和商用框架可以帮助团队实施智能体评测,而无需从零构建基础设施。
The right choice depends on your agent type, existing stack, and whether you need offline evaluation, production observability, or both.
正确的选择取决于你的智能体类型、现有技术栈,以及你需要离线评测、生产可观测性(production observability),还是两者都需要。
Harbor is designed for running agents in containerized environments, with infrastructure for running trials at scale across cloud providers and a standardized format for defining tasks and graders.
Harbor 旨在在容器化环境中运行智能体,提供跨云服务商大规模运行试验的基础设施,以及用于定义任务和评分器的标准化格式。
Popular benchmarks like Terminal-Bench 2.0 ship through the Harbor registry, making it easy to run established benchmarks along with custom eval suites.
像 Terminal-Bench 2.0 这样的流行基准测试通过 Harbor registry 发布,让运行成熟基准测试以及自定义评测套件变得容易。
Braintrust is a platform that combines offline evaluation with production observability and experiment tracking—useful for teams that need to both iterate during development and monitor quality in production.
Braintrust 是一个平台,将离线评测与生产可观测性和实验跟踪(experiment tracking)相结合——对于需要在开发期间迭代并在生产中监控质量的团队很有用。
Its autoevals library includes pre-built scorers for factuality, relevance, and other common dimensions.
它的 autoevals 库包含预构建的评分器,用于事实性(factuality)、相关性(relevance)及其他常见维度。
LangSmith offers tracing, offline and online evaluations, and dataset management with tight integration into the LangChain ecosystem.
LangSmith 提供追踪(tracing)、离线和在线评测,以及与 LangChain 生态紧密集成的数据集管理。
Langfuse provides similar capabilities as a self-hosted open-source alternative for teams with data residency requirements.
Langfuse 作为自托管的开源替代方案,为有数据驻留(data residency)要求的团队提供类似能力。
Arize offers Phoenix, an open-source platform for LLM tracing, debugging, and offline or online evaluations, and AX, a SaaS offering that extends Phoenix for scale, optimization and monitoring.
Arize 提供 Phoenix,一个用于 LLM 追踪、调试以及离线或在线评测的开源平台,以及 AX,一个扩展 Phoenix 以实现规模化、优化和监控的 SaaS 产品。
Many teams combine multiple tools, roll their own eval framework, or just use simple evaluation scripts as a starting point.
许多团队组合使用多种工具,自己搭建评测框架,或者只是使用简单的评测脚本作为起点。
We find that while frameworks can be a valuable way to accelerate progress and standardize, they’re only as good as the eval tasks you run through them.
我们发现,虽然框架可以是加速进展和标准化的有价值方式,但它们的价值取决于你通过它们运行的评测任务。
It’s often best to quickly pick a framework that fits your workflow, then invest your energy in the evals themselves by iterating on high-quality test cases and graders.
通常最好快速选择一个适合你工作流的框架,然后通过迭代高质量测试用例和评分器,把精力投入到评测本身。