引入上下文检索(Contextual Retrieval)
Introducing Contextual Retrieval
文章目录
For an AI model to be useful in specific contexts, it often needs access to background knowledge.
为了让 AI 模型在特定场景中有用,它通常需要访问背景知识(background knowledge)。
For example, customer support chatbots need knowledge about the specific business they're being used for, and legal analyst bots need to know about a vast array of past cases.
例如,客户支持聊天机器人需要了解它们所服务的具体业务的知识,而法律分析机器人则需要了解大量过往案例。
Developers typically enhance an AI model's knowledge using Retrieval-Augmented Generation (RAG).
开发者通常使用检索增强生成(Retrieval-Augmented Generation,RAG)来增强 AI 模型的知识。
RAG is a method that retrieves relevant information from a knowledge base and appends it to the user's prompt, significantly enhancing the model's response.
RAG 是一种从知识库(knowledge base)中检索相关信息,并将其附加到用户提示词(prompt)中,从而显著增强模型响应的方法。
The problem is that traditional RAG solutions remove context when encoding information, which often results in the system failing to retrieve the relevant information from the knowledge base.
问题在于,传统 RAG 方案在编码信息时会移除上下文,这往往导致系统无法从知识库中检索到相关信息。
In this post, we outline a method that dramatically improves the retrieval step in RAG.
在本文中,我们概述一种能显著改进 RAG 中检索步骤的方法。
The method is called “Contextual Retrieval” and uses two sub-techniques: Contextual Embeddings and Contextual BM25.
该方法称为“上下文检索”,并使用两种子技术:上下文嵌入(Contextual Embeddings)和上下文 BM25(Contextual BM25)。
This method can reduce the number of failed retrievals by 49% and, when combined with reranking, by 67%.
该方法可以将检索失败次数减少 49%,而与重排序(reranking)结合时,可以减少 67%。
These represent significant improvements in retrieval accuracy, which directly translates to better performance in downstream tasks.
这些代表着检索准确率的显著提升,并直接转化为下游任务中更好的表现。
You can easily deploy your own Contextual Retrieval solution with Claude with our cookbook.
你可以使用我们的 cookbook,轻松地针对 Claude 部署你自己的上下文检索解决方案。
A note on simply using a longer prompt
关于仅使用更长提示词的说明
Sometimes the simplest solution is the best.
有时最简单的解决方案就是最好的。
If your knowledge base is smaller than 200,000 tokens (about 500 pages of material), you can just include the entire knowledge base in the prompt that you give the model, with no need for RAG or similar methods.
如果你的知识库小于 200,000 个 token(约 500 页材料),你可以直接将整个知识库包含在你提供给模型的提示词中,无需使用 RAG 或类似方法。
A few weeks ago, we released prompt caching for Claude, which makes this approach significantly faster and more cost-effective.
几周前,我们为 Claude 发布了提示词缓存,这使这种方法显著更快、更具成本效益。
Developers can now cache frequently used prompts between API calls, reducing latency by > 2x and costs by up to 90% (you can see how it works by reading our prompt caching cookbook).
开发者现在可以在 API 调用之间缓存频繁使用的提示词,将延迟降低超过 2 倍,成本最多降低 90%(你可以阅读我们的提示词缓存 cookbook 了解其工作原理)。
However, as your knowledge base grows, you'll need a more scalable solution.
然而,随着你的知识库增长,你将需要一个更具扩展性的解决方案。
That’s where Contextual Retrieval comes in.
这正是 Contextual Retrieval 的用武之地。
A primer on RAG: scaling to larger knowledge bases
RAG 入门:扩展到更大的知识库
For larger knowledge bases that don't fit within the context window, RAG is the typical solution.
对于无法放入上下文窗口(context window)的更大知识库,RAG 是典型的解决方案。
RAG works by preprocessing a knowledge base using the following steps:
RAG 通过以下步骤预处理知识库来工作:
Break down the knowledge base (the “corpus” of documents) into smaller chunks of text, usually no more than a few hundred tokens;
将知识库(文档的“语料库”)分解为更小的文本块,通常不超过几百个 token;
Use an embedding model to convert these chunks into vector embeddings that encode meaning;
使用嵌入模型将这些块转换为编码含义的向量嵌入;
Store these embeddings in a vector database that allows for searching by semantic similarity.
将这些嵌入(embedding)存储在一个向量数据库(vector database)中,该数据库允许按语义相似度进行搜索。
At runtime, when a user inputs a query to the model, the vector database is used to find the most relevant chunks based on semantic similarity to the query.
在运行时,当用户向模型输入查询时,会使用向量数据库根据与查询的语义相似度找到最相关的文本块(chunk)。
Then, the most relevant chunks are added to the prompt sent to the generative model.
然后,将最相关的文本块添加到发送给生成式模型的提示词中。
While embedding models excel at capturing semantic relationships, they can miss crucial exact matches.
虽然嵌入模型擅长捕捉语义关系,但它们可能会漏掉关键的精确匹配。
Fortunately, there’s an older technique that can assist in these situations.
幸运的是,有一种更早的技术可以在这些情况下提供帮助。
BM25 (Best Matching 25) is a ranking function that uses lexical matching to find precise word or phrase matches.
BM25(Best Matching 25)是一种排序函数,它使用词法匹配来找到精确的单词或短语匹配。
It's particularly effective for queries that include unique identifiers or technical terms.
对于包含唯一标识符或技术术语的查询,它特别有效。
BM25 works by building upon the TF-IDF (Term Frequency-Inverse Document Frequency) concept.
BM25 的工作方式建立在 TF-IDF(Term Frequency-Inverse Document Frequency)概念之上。
TF-IDF measures how important a word is to a document in a collection.
TF-IDF 衡量一个词对集合中文档的重要程度。
BM25 refines this by considering document length and applying a saturation function to term frequency, which helps prevent common words from dominating the results.
BM25 通过考虑文档长度并对词频应用饱和函数来改进这一点,这有助于防止常见词主导结果。
Here’s how BM25 can succeed where semantic embeddings fail: Suppose a user queries "Error code TS-999" in a technical support database.
以下是 BM25 如何在语义嵌入失败之处取得成功:假设用户在技术支持数据库中查询“Error code TS-999”。
An embedding model might find content about error codes in general, but could miss the exact "TS-999" match.
嵌入模型可能会找到一般性的错误代码相关内容,但可能会漏掉精确的“TS-999”匹配。
BM25 looks for this specific text string to identify the relevant documentation.
BM25 会查找这个特定文本字符串,以识别相关文档。
RAG solutions can more accurately retrieve the most applicable chunks by combining the embeddings and BM25 techniques using the following steps:
RAG 解决方案可以通过结合嵌入和 BM25 技术,使用以下步骤更准确地检索最适用的文本块:
Break down the knowledge base (the "corpus" of documents) into smaller chunks of text, usually no more than a few hundred tokens;
将知识库(文档的“语料库”)拆分成更小的文本块,通常不超过几百个 token;
Create TF-IDF encodings and semantic embeddings for these chunks;
为这些文本块创建 TF-IDF 编码和语义嵌入;
Use BM25 to find top chunks based on exact matches;
使用 BM25 根据精确匹配找到排名靠前的文本块;
Use embeddings to find top chunks based on semantic similarity;
使用嵌入根据语义相似度找到排名靠前的文本块;
Combine and deduplicate results from (3) and (4) using rank fusion techniques;
使用排名融合技术合并并去重来自 (3) 和 (4) 的结果;
Add the top-K chunks to the prompt to generate the response.
将 top-K 文本块添加到提示词中,以生成响应。
By leveraging both BM25 and embedding models, traditional RAG systems can provide more comprehensive and accurate results, balancing precise term matching with broader semantic understanding.
通过同时利用 BM25 和嵌入模型,传统 RAG 系统能够提供更全面、更准确的结果,在精确的词项匹配与更广泛的语义理解之间取得平衡。
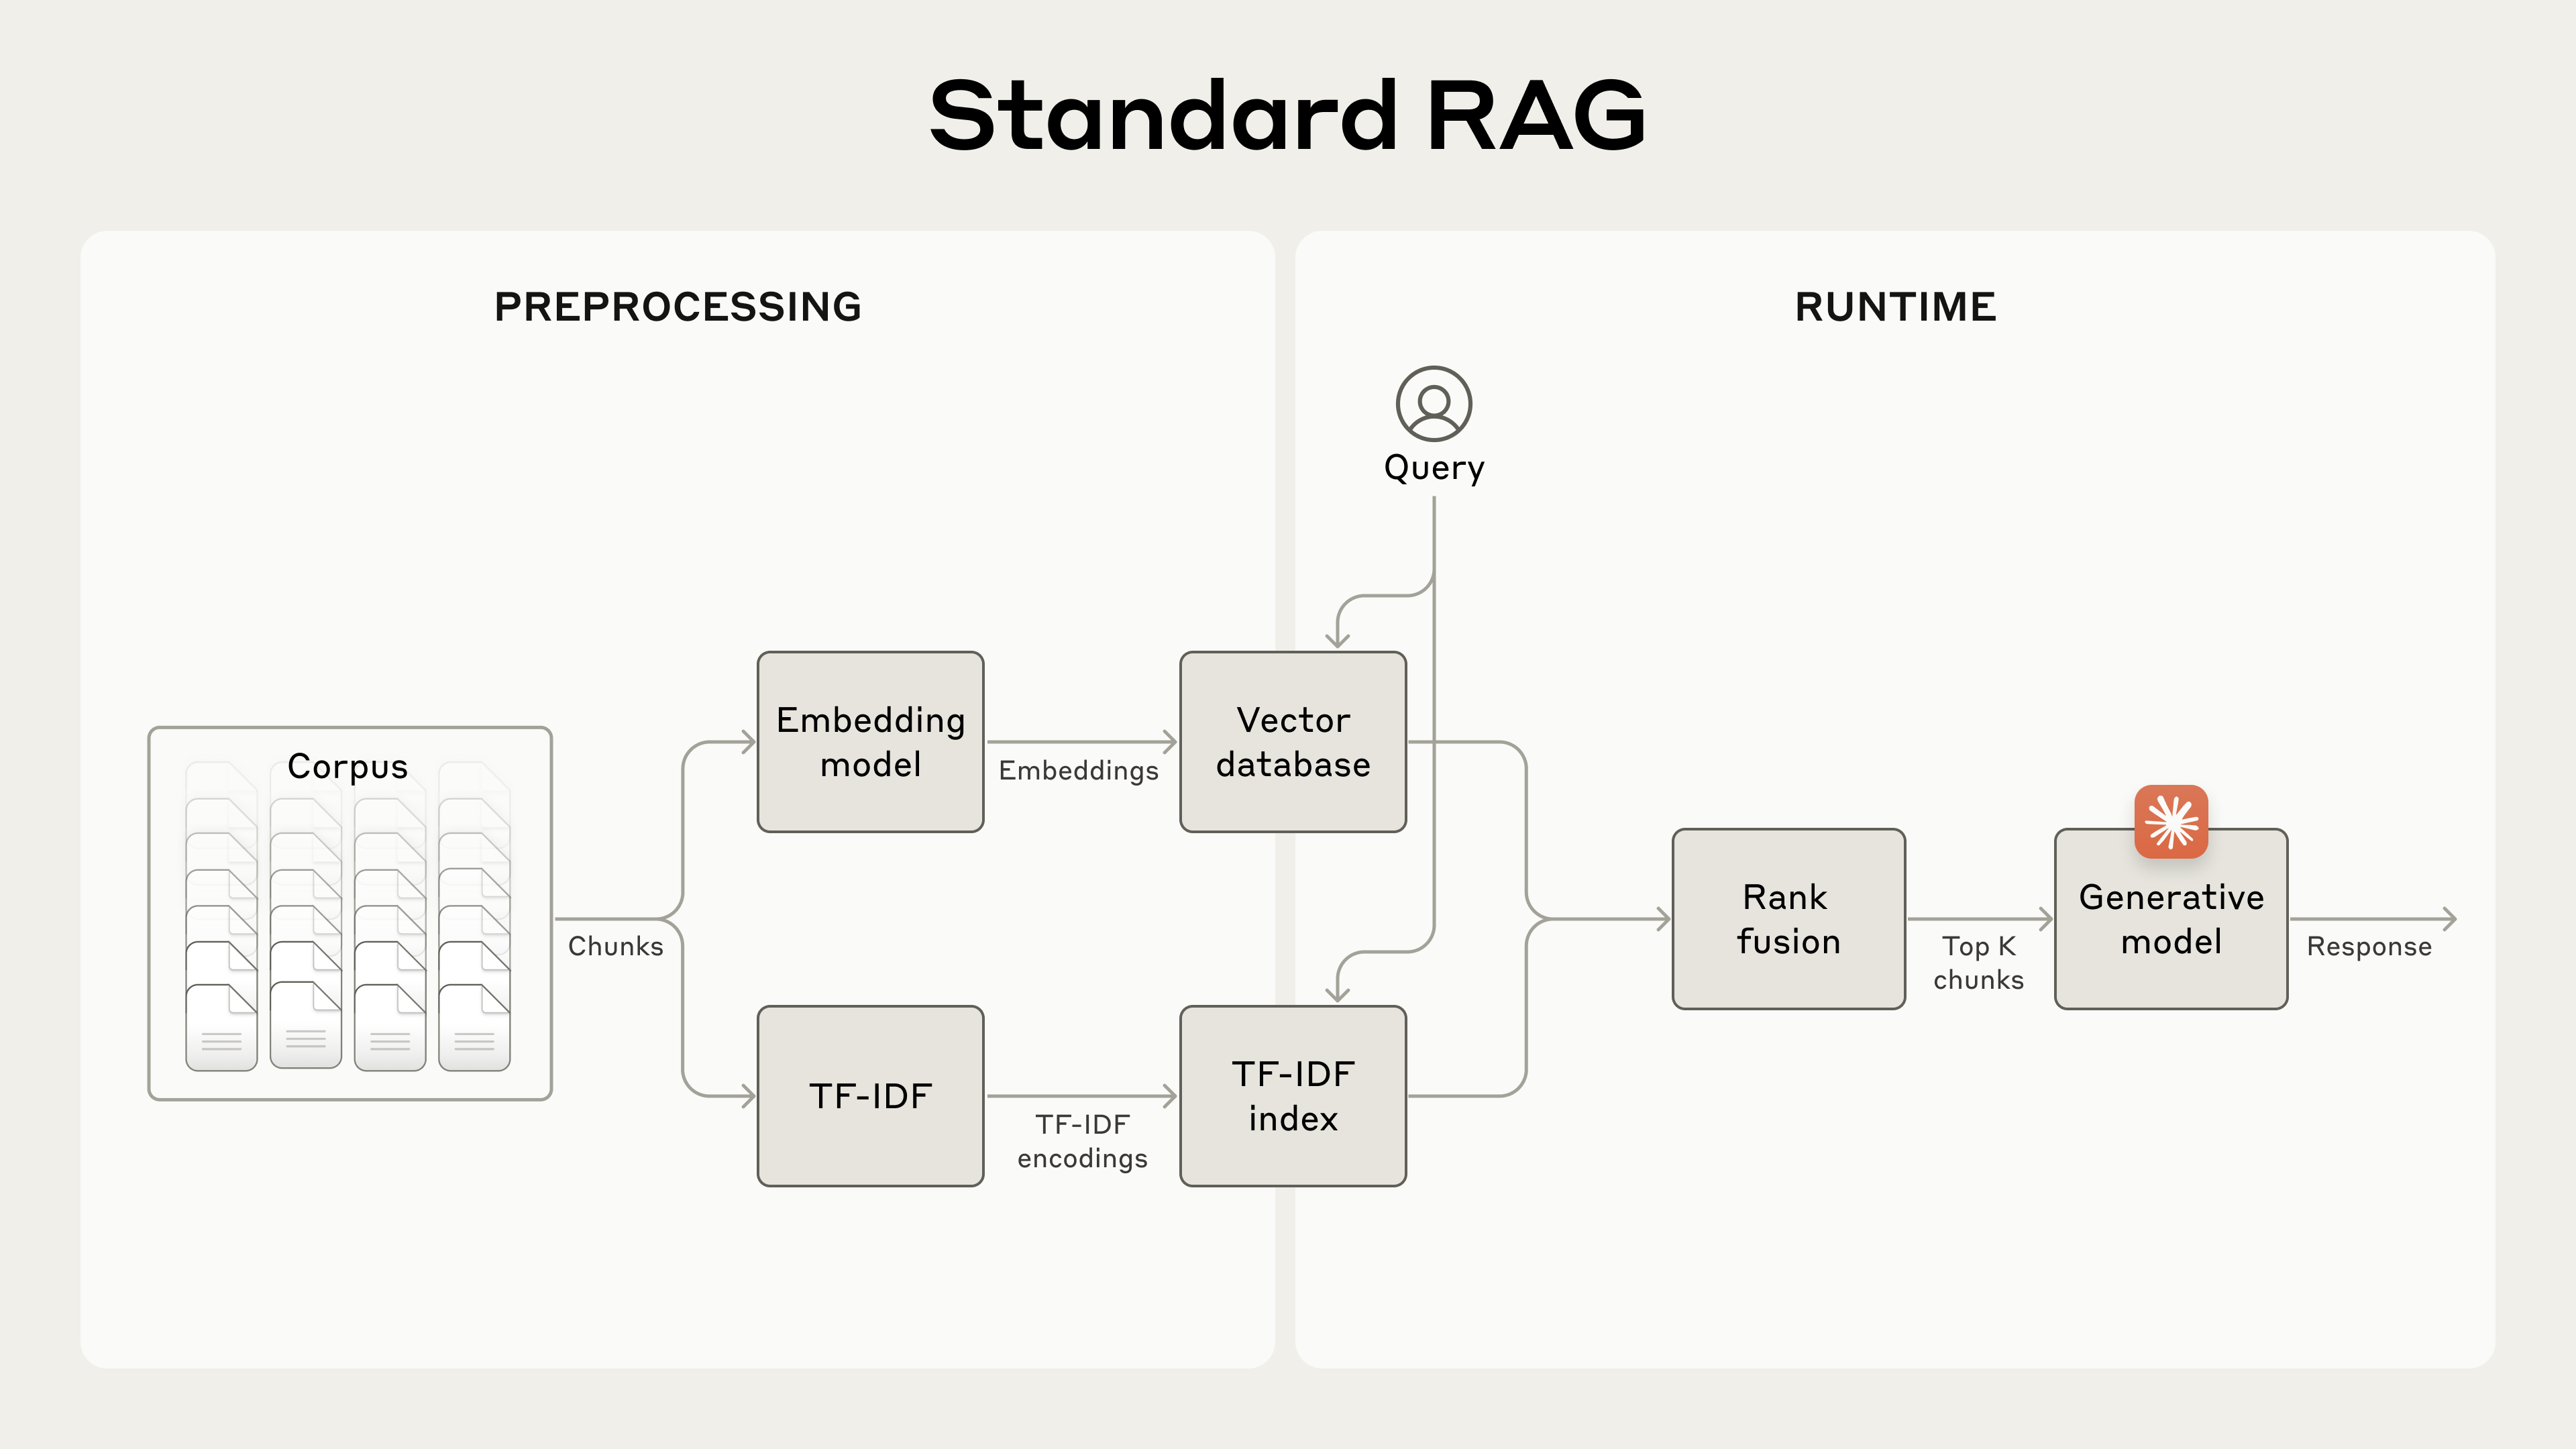
A Standard Retrieval-Augmented Generation (RAG) system that uses both embeddings and Best Match 25 (BM25) to retrieve information.
一个标准的检索增强生成(RAG)系统,同时使用嵌入和 Best Match 25(BM25)来检索信息。
TF-IDF (term frequency-inverse document frequency) measures word importance and forms the basis for BM25.
TF-IDF(词频-逆文档频率)衡量词的重要性,并构成 BM25 的基础。
This approach allows you to cost-effectively scale to enormous knowledge bases, far beyond what could fit in a single prompt.
这种方法让你能够以经济高效的方式扩展到巨大的知识库,远远超出单个提示词所能容纳的范围。
But these traditional RAG systems have a significant limitation: they often destroy context.
但这些传统 RAG 系统有一个重大局限:它们常常破坏上下文。
The context conundrum in traditional RAG
传统 RAG 中的上下文难题
In traditional RAG, documents are typically split into smaller chunks for efficient retrieval.
在传统 RAG 中,文档通常被分割成更小的块以提高检索效率。
While this approach works well for many applications, it can lead to problems when individual chunks lack sufficient context.
虽然这种方法对许多应用很有效,但当单个块缺乏足够的上下文时,可能会导致问题。
For example, imagine you had a collection of financial information (say, U.S. SEC filings) embedded in your knowledge base, and you received the following question: "What was the revenue growth for ACME Corp in Q2 2023?"
例如,假设你有一个金融信息集合(比如美国 SEC 文件)嵌入在你的知识库中,然后你收到以下问题:“ACME Corp 在 2023 年第二季度的收入增长是多少?”
A relevant chunk might contain the text: "The company's revenue grew by 3% over the previous quarter."
一个相关的分块可能包含这样的文本:“公司营收较上一季度增长了 3%。”
However, this chunk on its own doesn't specify which company it's referring to or the relevant time period, making it difficult to retrieve the right information or use the information effectively.
然而,这个分块本身没有说明它指的是哪家公司或相关时间段,这使得检索正确信息或有效使用信息变得困难。
Introducing Contextual Retrieval
引入上下文检索
Contextual Retrieval solves this problem by prepending chunk-specific explanatory context to each chunk before embedding (“Contextual Embeddings”) and creating the BM25 index (“Contextual BM25”).
上下文检索通过在嵌入每个分块之前,为其前置分块特定的解释性上下文(“上下文嵌入”),并创建 BM25 索引(“上下文 BM25”),解决了这个问题。
Let’s return to our SEC filings collection example.
让我们回到 SEC 申报文件集合的示例。
Here's an example of how a chunk might be transformed:
以下是一个分块可能如何被转换的示例:
original_chunk = "The company's revenue grew by 3% over the previous quarter."

contextualized_chunk = "This chunk is from an SEC filing on ACME corp's performance in Q2 2023; the previous quarter's revenue was $314 million. The company's revenue grew by 3% over the previous quarter."It is worth noting that other approaches to using context to improve retrieval have been proposed in the past.
值得注意的是,过去已经提出过其他利用上下文来改进检索的方法。
Other proposals include: adding generic document summaries to chunks (we experimented and saw very limited gains), hypothetical document embedding, and summary-based indexing (we evaluated and saw low performance).
其他提议包括:向分块添加通用文档摘要(我们进行了实验,发现收益非常有限)、假设文档嵌入(hypothetical document embedding),以及基于摘要的索引(summary-based indexing)(我们进行了评测,发现性能很低)。
These methods differ from what is proposed in this post.
这些方法与本文提出的方法不同。
Implementing Contextual Retrieval
实现上下文检索
Of course, it would be far too much work to manually annotate the thousands or even millions of chunks in a knowledge base.
当然,手动标注知识库中的数千甚至数百万个 chunk 会是工作量过大的事情。
To implement Contextual Retrieval, we turn to Claude.
为了实现 Contextual Retrieval,我们借助 Claude。
We’ve written a prompt that instructs the model to provide concise, chunk-specific context that explains the chunk using the context of the overall document.
我们编写了一个提示词,指示模型提供简洁、针对特定 chunk 的上下文,利用整篇文档的上下文来解释该 chunk。
We used the following Claude 3 Haiku prompt to generate context for each chunk:
我们使用以下 Claude 3 Haiku 提示词为每个 chunk 生成上下文:
<document>
{{WHOLE_DOCUMENT}}
</document>
Here is the chunk we want to situate within the whole document
<chunk>
{{CHUNK_CONTENT}}
</chunk>
Please give a short succinct context to situate this chunk within the overall document for the purposes of improving search retrieval of the chunk. Answer only with the succinct context and nothing else.The resulting contextual text, usually 50-100 tokens, is prepended to the chunk before embedding it and before creating the BM25 index.
生成的上下文文本通常为 50-100 个 token,会在将其嵌入之前以及创建 BM25 索引之前,前置添加到 chunk 中。
Here’s what the preprocessing flow looks like in practice:
实际中的预处理流程如下:
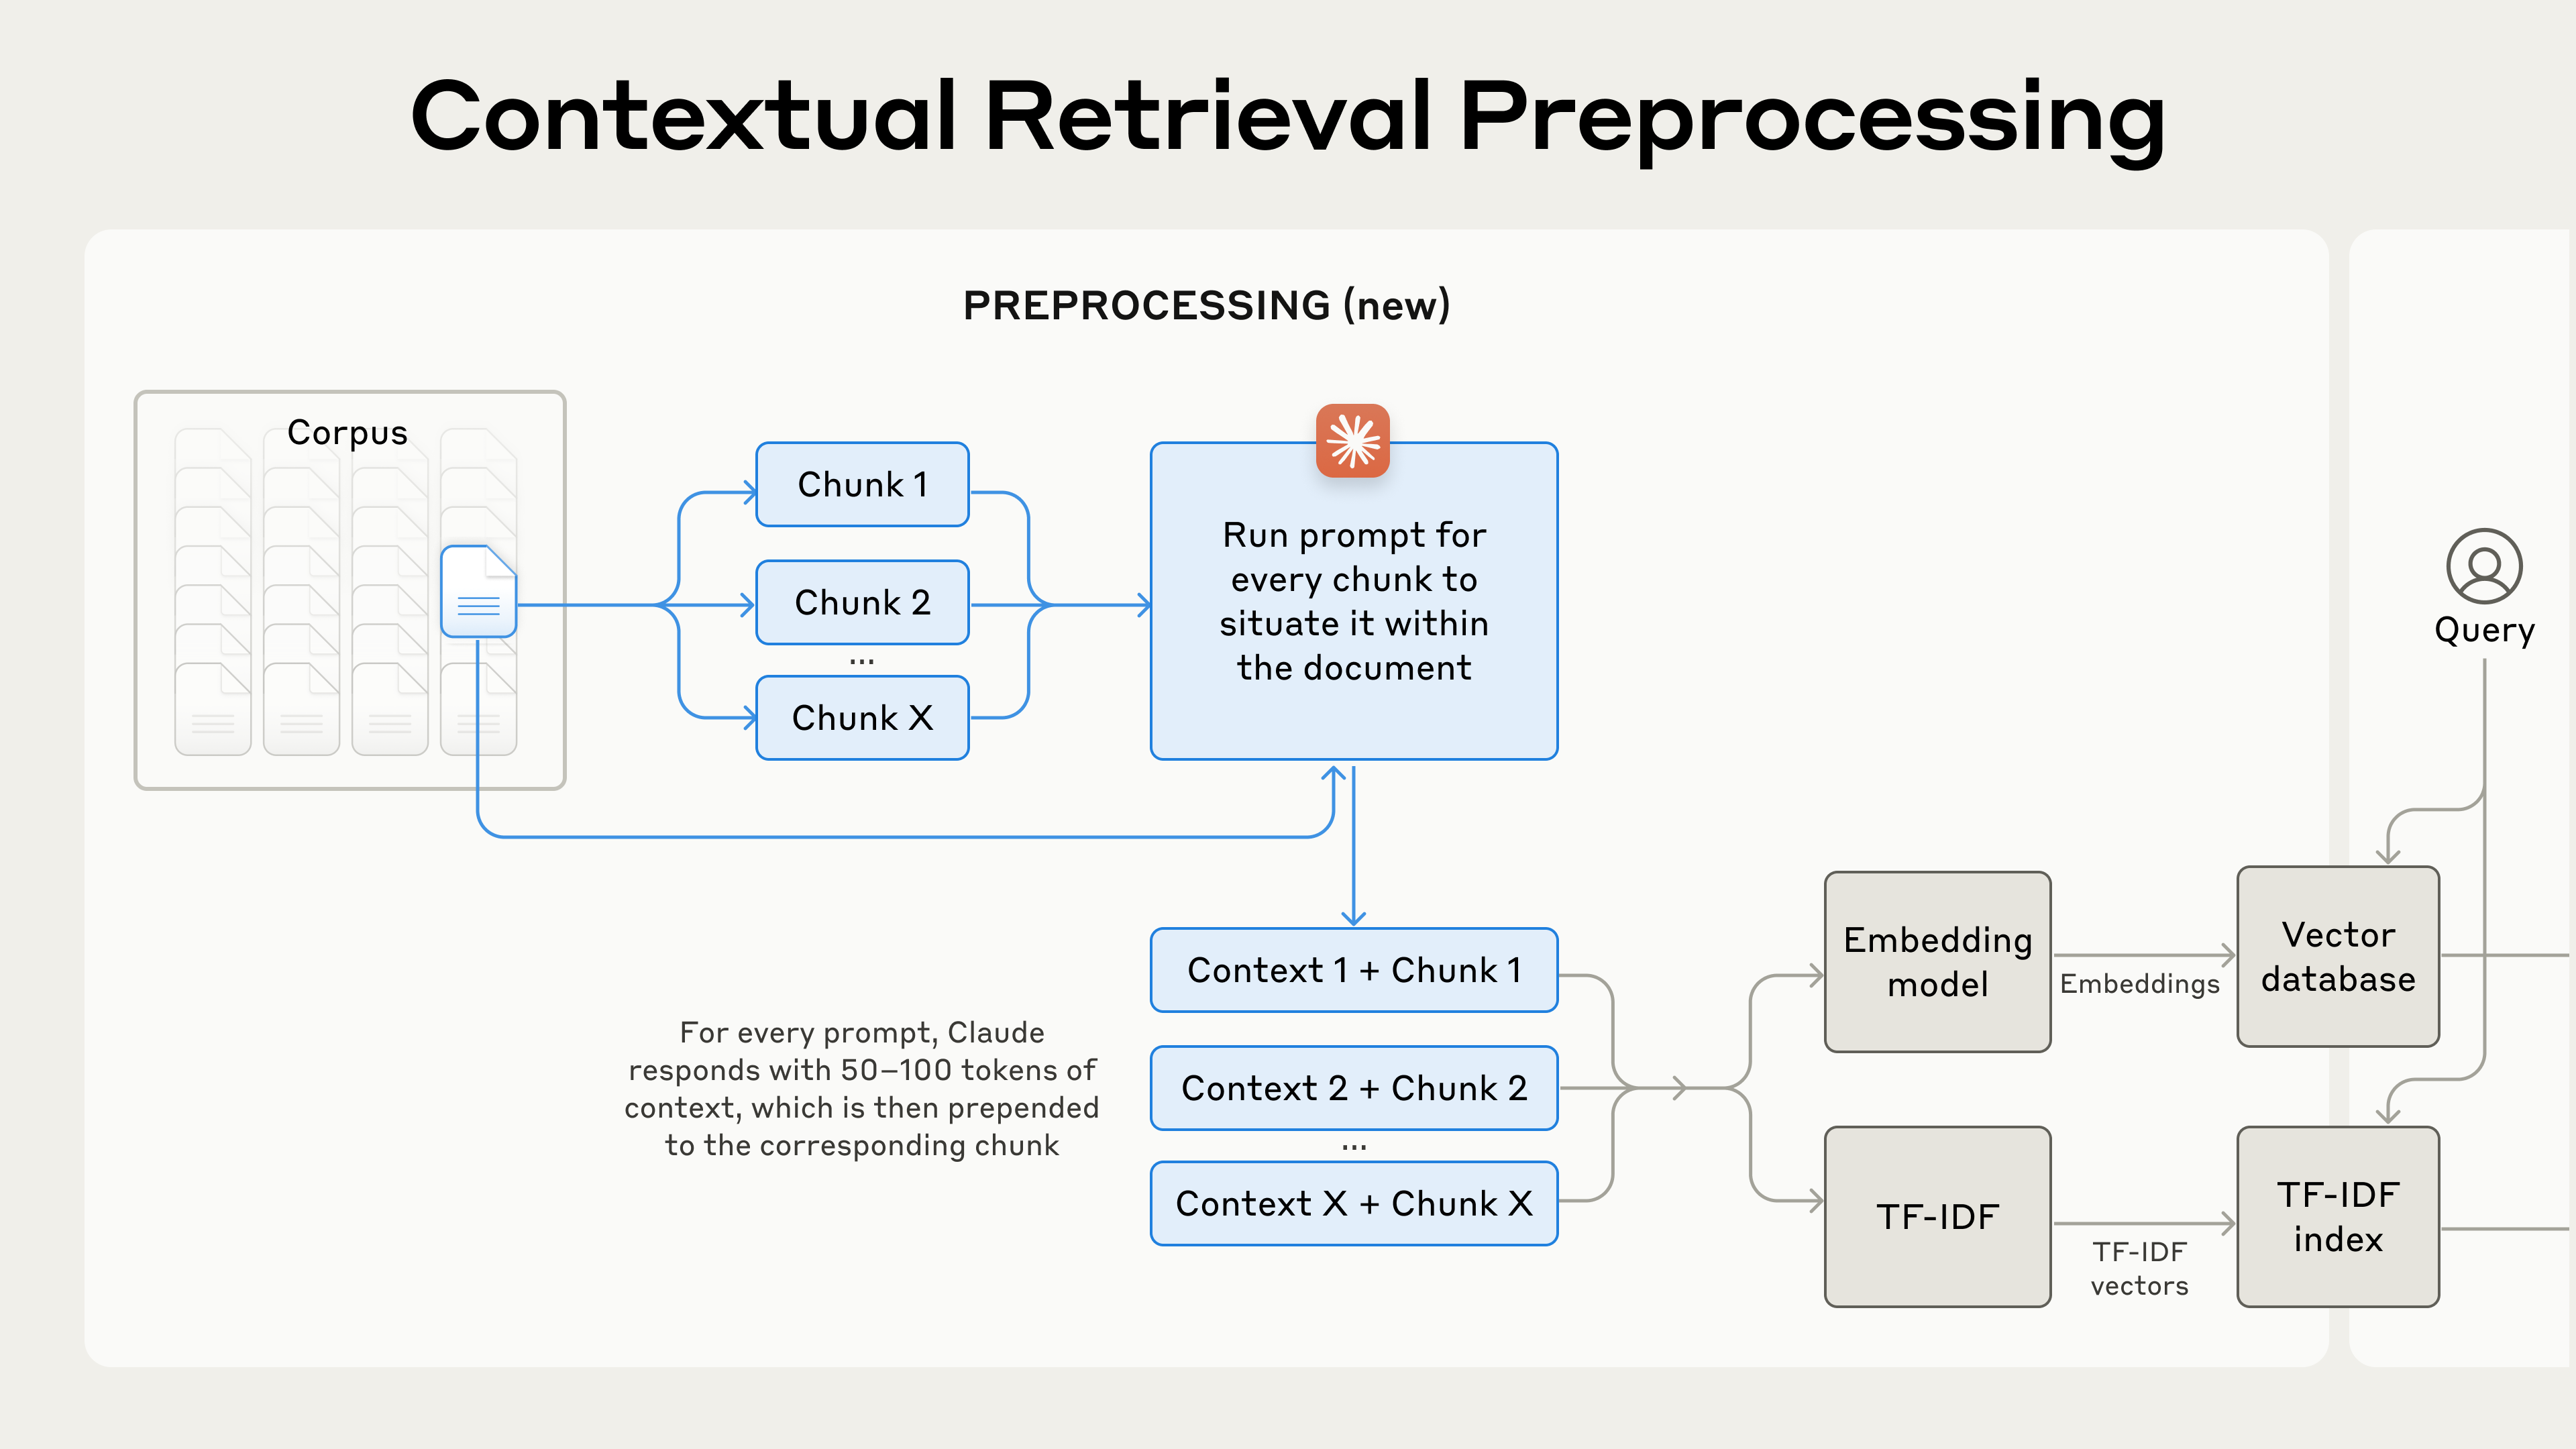
Contextual Retrieval is a preprocessing technique that improves retrieval accuracy.
Contextual Retrieval 是一种提高检索准确率的预处理技术。
If you’re interested in using Contextual Retrieval, you can get started with our cookbook.
如果你有兴趣使用 Contextual Retrieval,可以从我们的 cookbook 开始。
Using Prompt Caching to reduce the costs of Contextual Retrieval
使用 Prompt Caching 降低 Contextual Retrieval 的成本
Contextual Retrieval is uniquely possible at low cost with Claude, thanks to the special prompt caching feature we mentioned above.
多亏了我们上文提到的特殊提示词缓存(prompt caching)功能,上下文检索可以在 Claude 上以低成本独特地实现。
With prompt caching, you don’t need to pass in the reference document for every chunk.
使用提示词缓存,你不需要为每个块传入参考文档。
You simply load the document into the cache once and then reference the previously cached content.
你只需将文档加载到缓存中一次,然后引用之前缓存的内容。
Assuming 800 token chunks, 8k token documents, 50 token context instructions, and 100 tokens of context per chunk, the one-time cost to generate contextualized chunks is $1.02 per million document tokens.
假设块为 800 token、文档为 8k token、上下文指令为 50 token,每个块的上下文为 100 token,则生成上下文化块的一次性成本为每百万文档 token 1.02 美元。
Methodology
方法
We experimented across various knowledge domains (codebases, fiction, ArXiv papers, Science Papers), embedding models, retrieval strategies, and evaluation metrics.
我们在各种知识领域(代码库、小说、ArXiv 论文、科学论文)、嵌入模型、检索策略和评测指标上进行了实验。
We’ve included a few examples of the questions and answers we used for each domain in Appendix II.
我们在附录 II 中列出了每个领域使用的一些问题和答案示例。
The graphs below show the average performance across all knowledge domains with the top-performing embedding configuration (Gemini Text 004) and retrieving the top-20-chunks.
下图展示了在所有知识领域上,使用表现最佳的嵌入配置(Gemini Text 004)并检索前 20 个块时的平均性能。
We use 1 minus recall@20 as our evaluation metric, which measures the percentage of relevant documents that fail to be retrieved within the top 20 chunks.
我们使用 1 减去 recall@20 作为评测指标,它衡量在前 20 个块内未能检索到的相关文档的百分比。
You can see the full results in the appendix - contextualizing improves performance in every embedding-source combination we evaluated.
你可以在附录中看到完整结果——在我们评估的每一种嵌入来源组合中,添加上下文都提升了性能。
Performance improvements
性能提升
Our experiments showed that:
我们的实验表明:
Contextual Embeddings reduced the top-20-chunk retrieval failure rate by 35% (5.7% → 3.7%).
Contextual Embeddings 将 top-20-chunk 检索失败率降低了 35%(5.7% → 3.7%)。
Combining Contextual Embeddings and Contextual BM25 reduced the top-20-chunk retrieval failure rate by 49% (5.7% → 2.9%).
将 Contextual Embeddings 和 Contextual BM25 结合后,top-20-chunk 检索失败率降低了 49%(5.7% → 2.9%)。
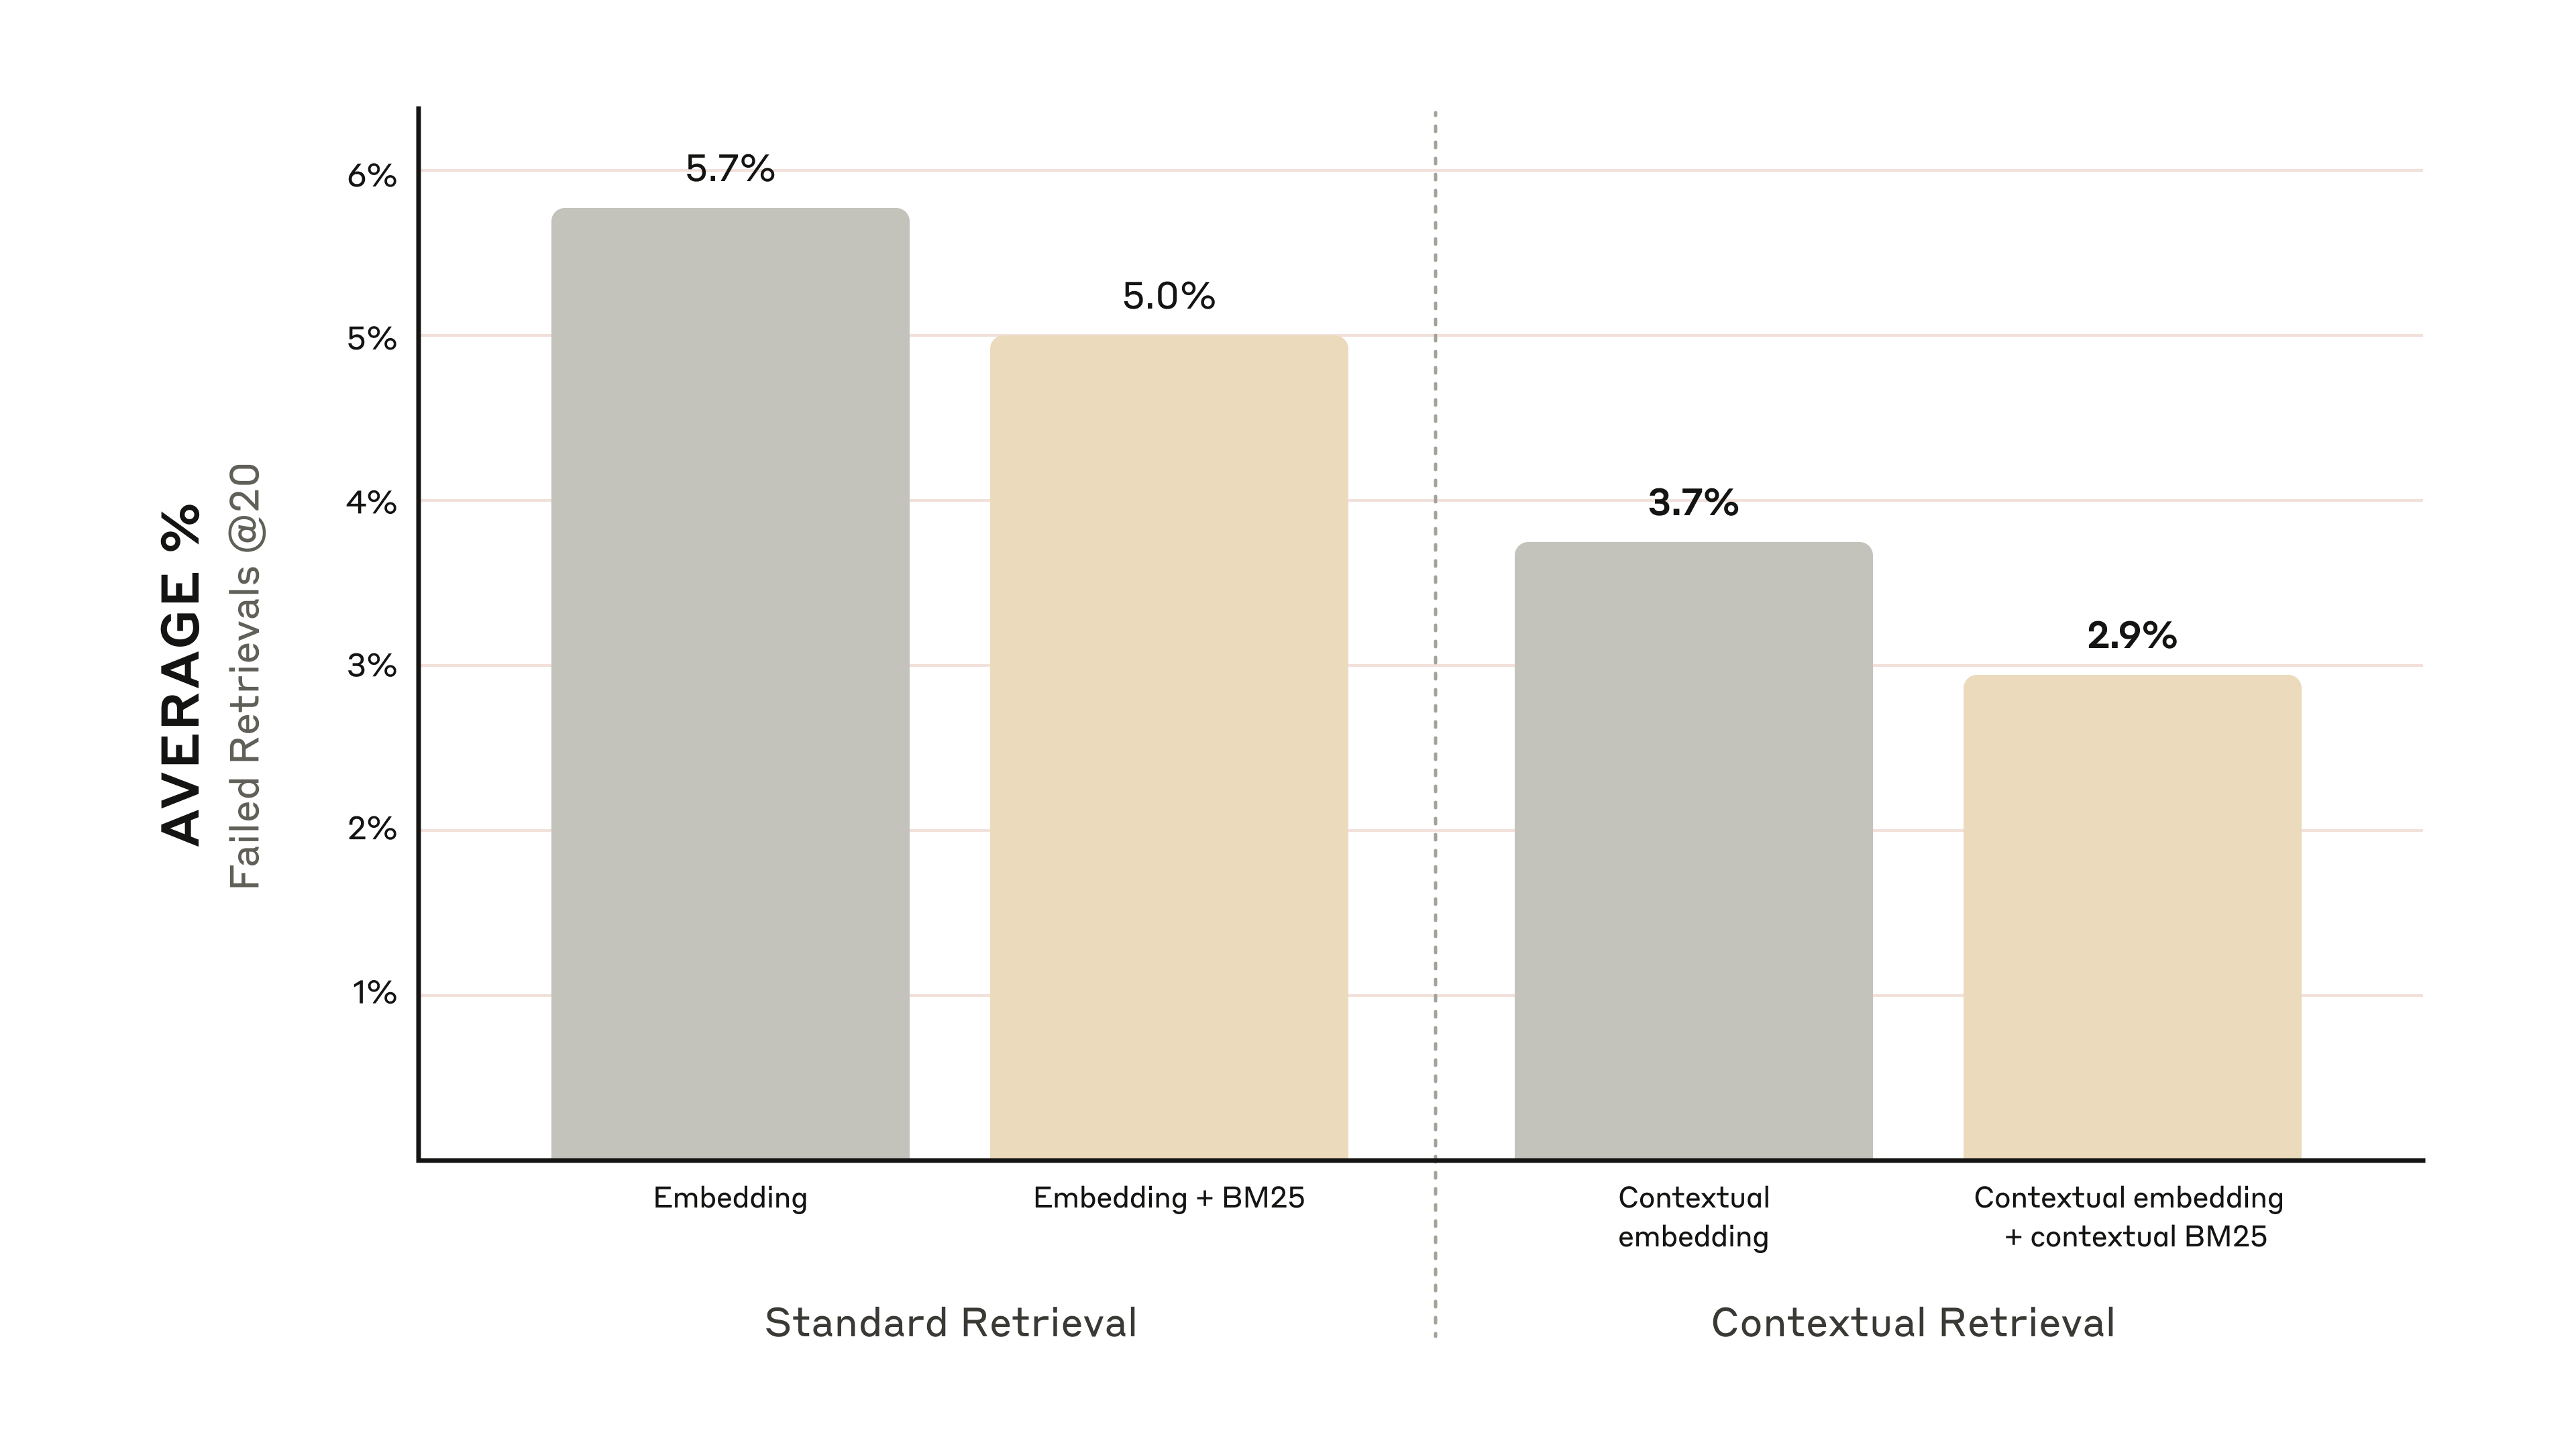
Combining Contextual Embedding and Contextual BM25 reduce the top-20-chunk retrieval failure rate by 49%.
结合 Contextual Embedding 和 Contextual BM25 可将 top-20-chunk 检索失败率降低 49%。
Implementation considerations
实现注意事项
When implementing Contextual Retrieval, there are a few considerations to keep in mind:
在实现 Contextual Retrieval 时,需要考虑以下几点:
Chunk boundaries: Consider how you split your documents into chunks.
Chunk boundaries:考虑如何将文档切分为 chunk。
The choice of chunk size, chunk boundary, and chunk overlap can affect retrieval performance1.
chunk 大小、chunk 边界和 chunk 重叠的选择会影响检索性能1。
Embedding model: Whereas Contextual Retrieval improves performance across all embedding models we tested, some models may benefit more than others.
嵌入模型:虽然 Contextual Retrieval 在我们测试过的所有嵌入模型上都能提升性能,但有些模型的受益可能比其他模型更大。
We found Gemini and Voyage embeddings to be particularly effective.
我们发现 Gemini 和 Voyage 的嵌入尤其有效。
Custom contextualizer prompts: While the generic prompt we provided works well, you may be able to achieve even better results with prompts tailored to your specific domain or use case (for example, including a glossary of key terms that might only be defined in other documents in the knowledge base).
自定义上下文提示词:虽然我们提供的通用提示词效果不错,但使用针对你特定领域或用例定制的提示词,可能会取得更好的结果(例如,加入一个关键术语表,这些术语可能只在知识库中的其他文档里才有定义)。
Number of chunks: Adding more chunks into the context window increases the chances that you include the relevant information.
分块数量:往上下文窗口里放入更多分块,会增加你包含相关信息的机会。
However, more information can be distracting for models so there's a limit to this.
然而,更多信息可能会让模型分心,所以这存在一个上限。
We tried delivering 5, 10, and 20 chunks, and found using 20 to be the most performant of these options (see appendix for comparisons) but it’s worth experimenting on your use case.
我们尝试了提供 5、10 和 20 个分块,发现其中使用 20 个分块的表现最好(对比见附录),不过在你的用例上值得做实验。
Always run evals: Response generation may be improved by passing it the contextualized chunk and distinguishing between what is context and what is the chunk.
始终运行评测:把上下文分块传给模型,并区分清楚哪些是上下文、哪些是分块,可能会改善响应生成的效果。
Further boosting performance with Reranking
用重排序进一步提升性能
In a final step, we can combine Contextual Retrieval with another technique to give even more performance improvements.
在最后一步,我们可以把 Contextual Retrieval 与另一种技术结合起来,进一步提升性能。
In traditional RAG, the AI system searches its knowledge base to find the potentially relevant information chunks.
在传统 RAG 中,AI 系统会搜索其知识库,找出可能相关的信息分块。
With large knowledge bases, this initial retrieval often returns a lot of chunks—sometimes hundreds—of varying relevance and importance.
在大型知识库中,这一初始检索往往会返回大量分块——有时多达数百个——其相关性和重要性各不相同。
Reranking is a commonly used filtering technique to ensure that only the most relevant chunks are passed to the model.
重排序是一种常用的过滤技术,用于确保只有最相关的分块被传递给模型。
Reranking provides better responses and reduces cost and latency because the model is processing less information.
重排序能提供更好的响应,并降低成本与延迟,因为模型处理的信息更少。
The key steps are:
关键步骤如下:
Perform initial retrieval to get the top potentially relevant chunks (we used the top 150);
执行初步检索,获取潜在最相关的前若干分块(我们使用了前 150 个);
Pass the top-N chunks, along with the user's query, through the reranking model;
将前 N 个分块连同用户查询一起传入重排序模型;
Using a reranking model, give each chunk a score based on its relevance and importance to the prompt, then select the top-K chunks (we used the top 20);
使用重排序模型,根据每个分块与提示词的相关性和重要性为其打分,然后选出前 K 个分块(我们使用了前 20 个);
Pass the top-K chunks into the model as context to generate the final result.
将前 K 个分块作为上下文传入模型,以生成最终结果。
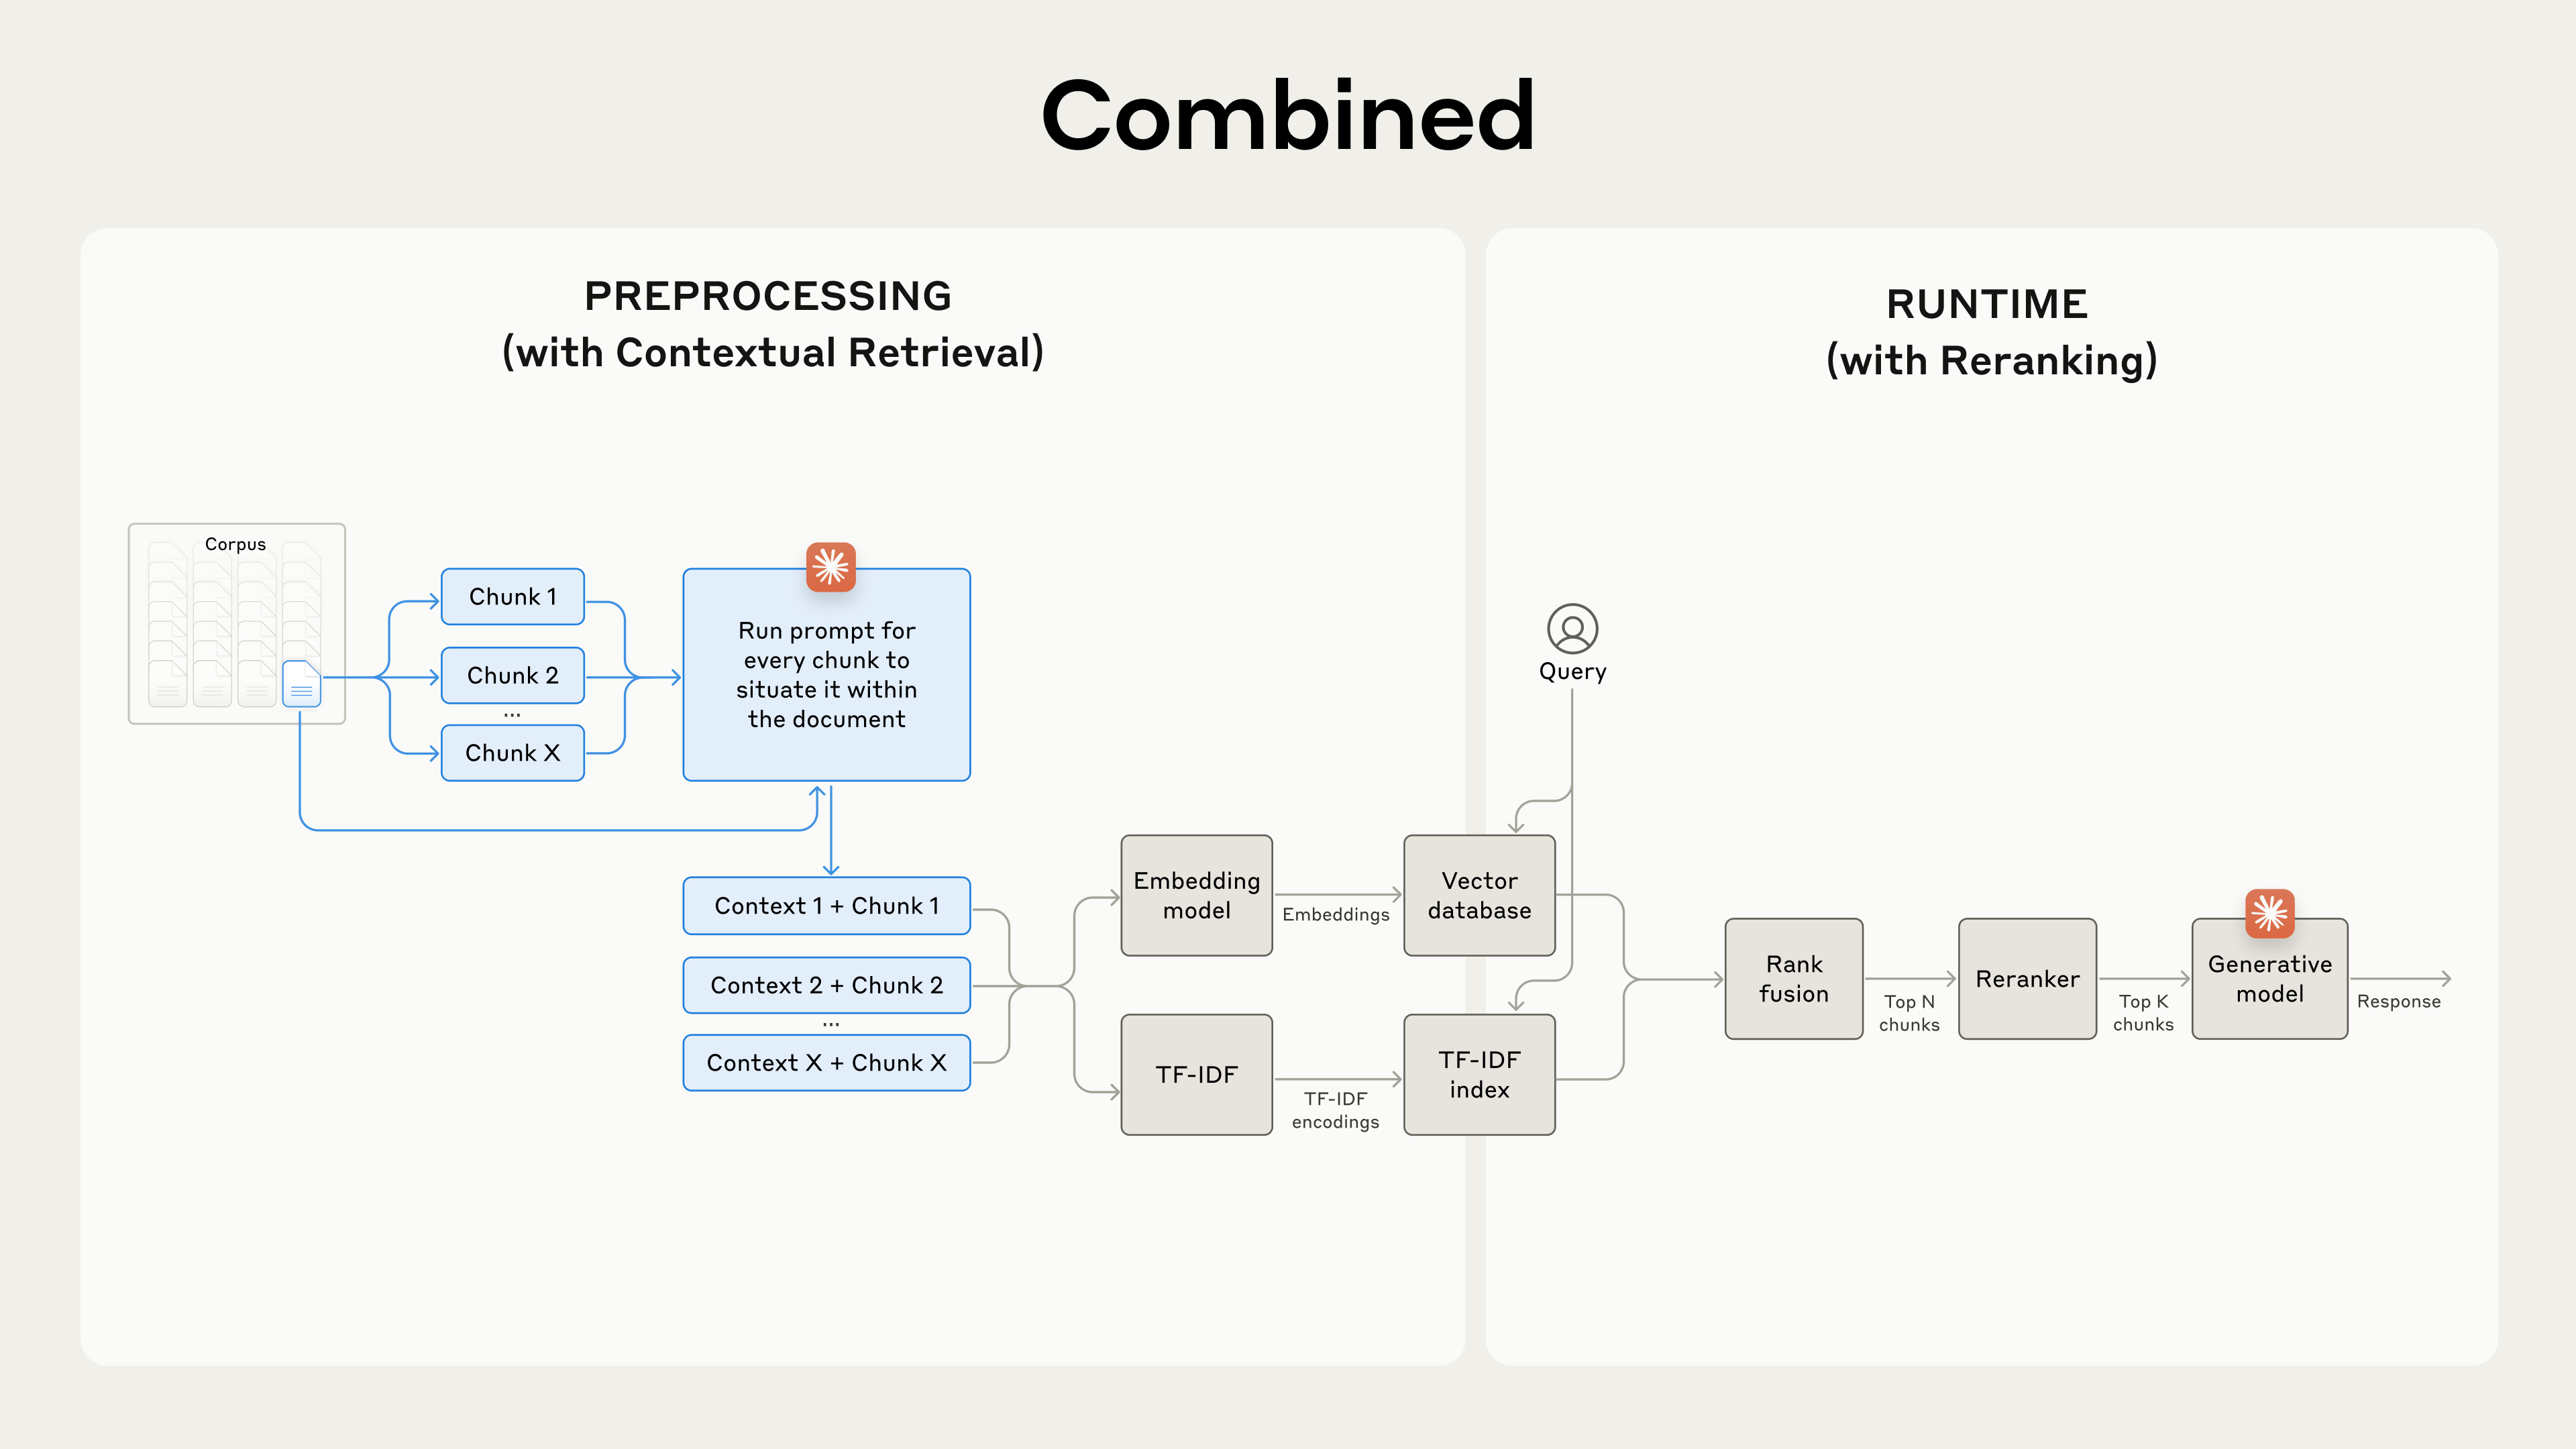
Combine Contextual Retrieva and Reranking to maximize retrieval accuracy.
将 Contextual Retrieva 与重排序结合,以最大化检索准确率。
Performance improvements
性能提升
There are several reranking models on the market.
市面上有若干重排模型。
We ran our tests with the Cohere reranker.
我们的测试使用的是 Cohere reranker。
Voyage also offers a reranker, though we did not have time to test it.
Voyage 也提供了一款 reranker,不过我们没有时间测试它。
Our experiments showed that, across various domains, adding a reranking step further optimizes retrieval.
我们的实验表明,在不同领域中,加入重排步骤能进一步优化检索。
Specifically, we found that Reranked Contextual Embedding and Contextual BM25 reduced the top-20-chunk retrieval failure rate by 67% (5.7% → 1.9%).
具体来说,我们发现重排后的 Contextual Embedding 和 Contextual BM25 将前 20 个 chunk 的检索失败率降低了 67%(5.7% → 1.9%)。
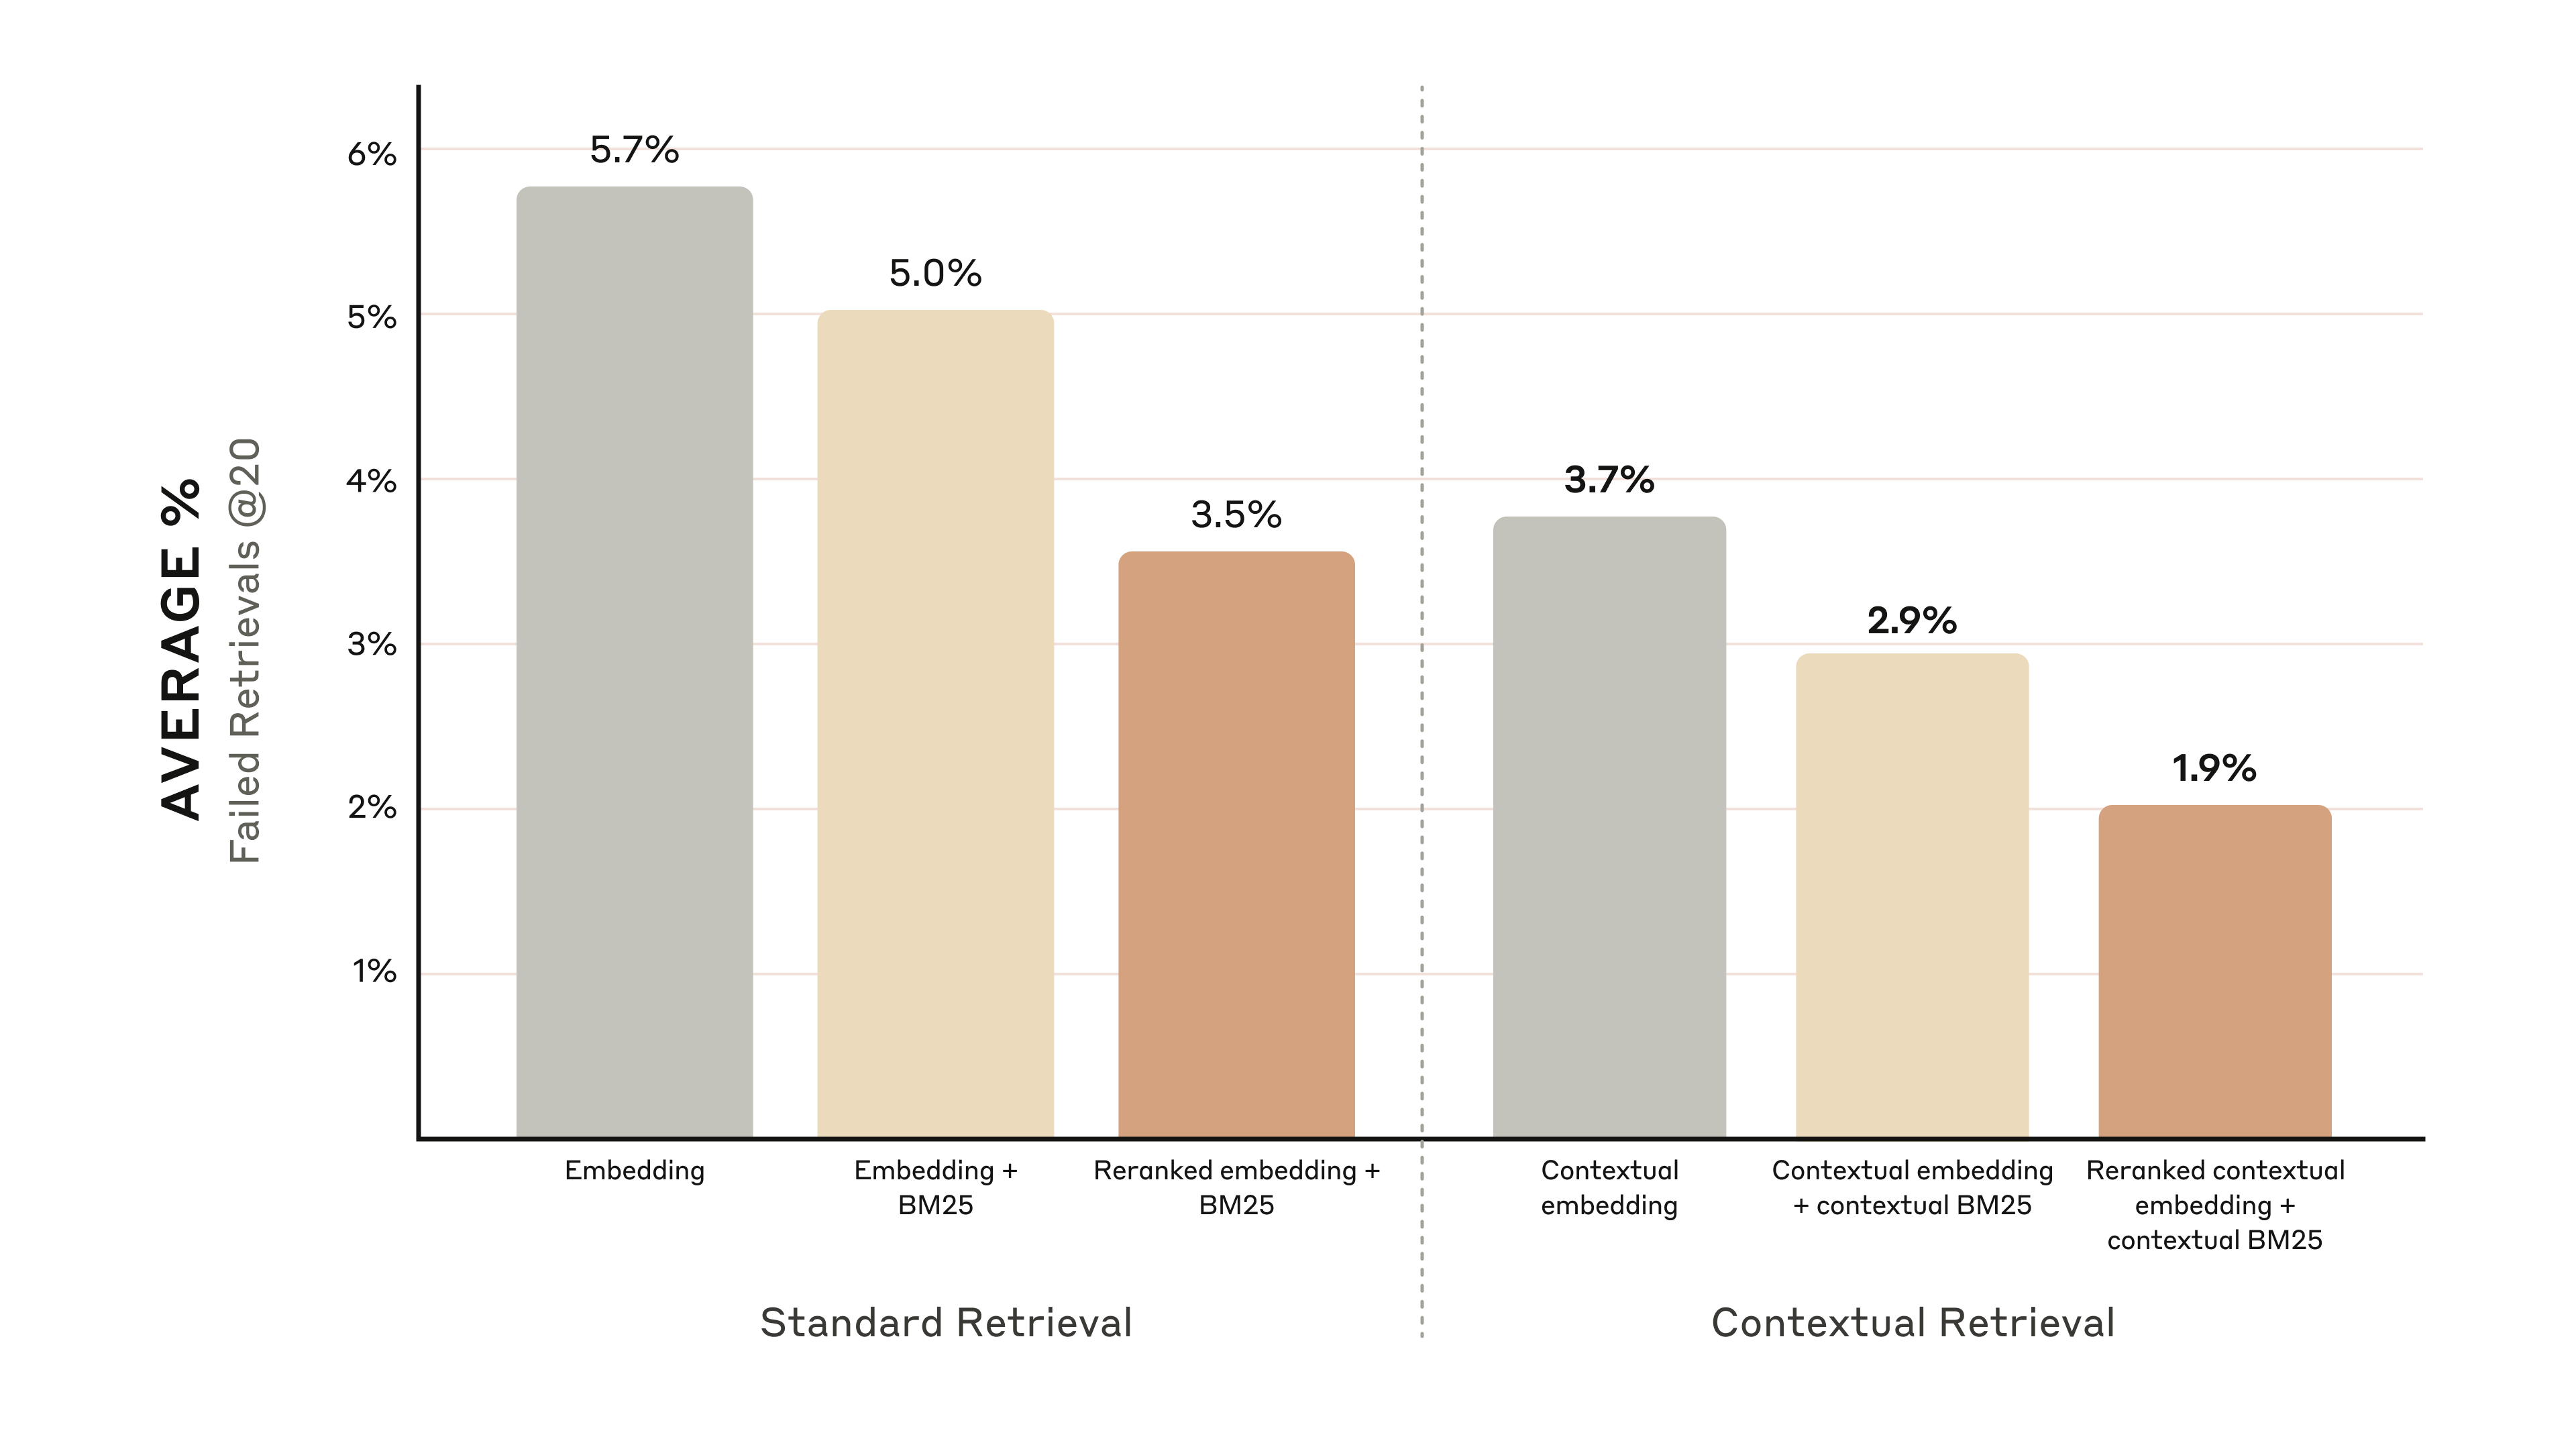
Reranked Contextual Embedding and Contextual BM25 reduces the top-20-chunk retrieval failure rate by 67%.
重排后的 Contextual Embedding 和 Contextual BM25 将前 20 个 chunk 的检索失败率降低了 67%。
Cost and latency considerations
成本与延迟考量
One important consideration with reranking is the impact on latency and cost, especially when reranking a large number of chunks.
重排的一个重要考量是对延迟和成本的影响,尤其是在对大量 chunk 进行重排时。
Because reranking adds an extra step at runtime, it inevitably adds a small amount of latency, even though the reranker scores all the chunks in parallel.
因为重排在运行时增加了一个额外步骤,所以即使 reranker 并行给所有 chunk 打分,它也必然会增加少量延迟。
There is an inherent trade-off between reranking more chunks for better performance vs. reranking fewer for lower latency and cost.
在为了更好性能而重排更多 chunk 与为了更低延迟和成本而重排更少 chunk 之间,存在固有的权衡。
We recommend experimenting with different settings on your specific use case to find the right balance.
我们建议在你的具体用例上尝试不同设置,以找到合适的平衡。
Conclusion
结论
We ran a large number of tests, comparing different combinations of all the techniques described above (embedding model, use of BM25, use of contextual retrieval, use of a reranker, and total # of top-K results retrieved), all across a variety of different dataset types.
我们运行了大量测试,比较上述所有技术的不同组合(嵌入模型、BM25 的使用、上下文检索的使用、重排器 (reranker) 的使用,以及检索到的 top-K 结果总数),并覆盖多种不同的数据集类型。
Here’s a summary of what we found:
以下是我们发现的总结:
Embeddings+BM25 is better than embeddings on their own;
嵌入+BM25 比单独使用嵌入更好;
Voyage and Gemini have the best embeddings of the ones we tested;
在我们测试过的方案中,Voyage 和 Gemini 的嵌入效果最好;
Passing the top-20 chunks to the model is more effective than just the top-10 or top-5;
将 top-20 个 chunk 传给模型比只传 top-10 或 top-5 更有效;
Adding context to chunks improves retrieval accuracy a lot;
为 chunk 添加上下文能大幅提升检索准确率;
Reranking is better than no reranking;
重排优于不重排;
All these benefits stack: to maximize performance improvements, we can combine contextual embeddings (from Voyage or Gemini) with contextual BM25, plus a reranking step, and adding the 20 chunks to the prompt.
所有这些收益可以叠加:为了最大化性能提升,我们可以将上下文嵌入(来自 Voyage 或 Gemini)与上下文 BM25 结合,再加上重排步骤,并把 20 个 chunk 加入提示词。
We encourage all developers working with knowledge bases to use our cookbook to experiment with these approaches to unlock new levels of performance.
我们鼓励所有使用知识库的开发者利用我们的 cookbook 试验这些方法,以释放新的性能水平。
Appendix I
附录 I
Below is a breakdown of results across datasets, embedding providers, use of BM25 in addition to embeddings, use of contextual retrieval, and use of reranking for Retrievals @ 20.
下面是各数据集、嵌入提供方、在嵌入之外使用 BM25、使用上下文检索以及针对 Retrievals @ 20 使用重排的结果细分。
See Appendix II for the breakdowns for Retrievals @ 10 and @ 5 as well as example questions and answers for each dataset.
有关 Retrievals @ 10 和 @ 5 的细分,以及每个数据集的示例问题和答案,请参见附录 II。
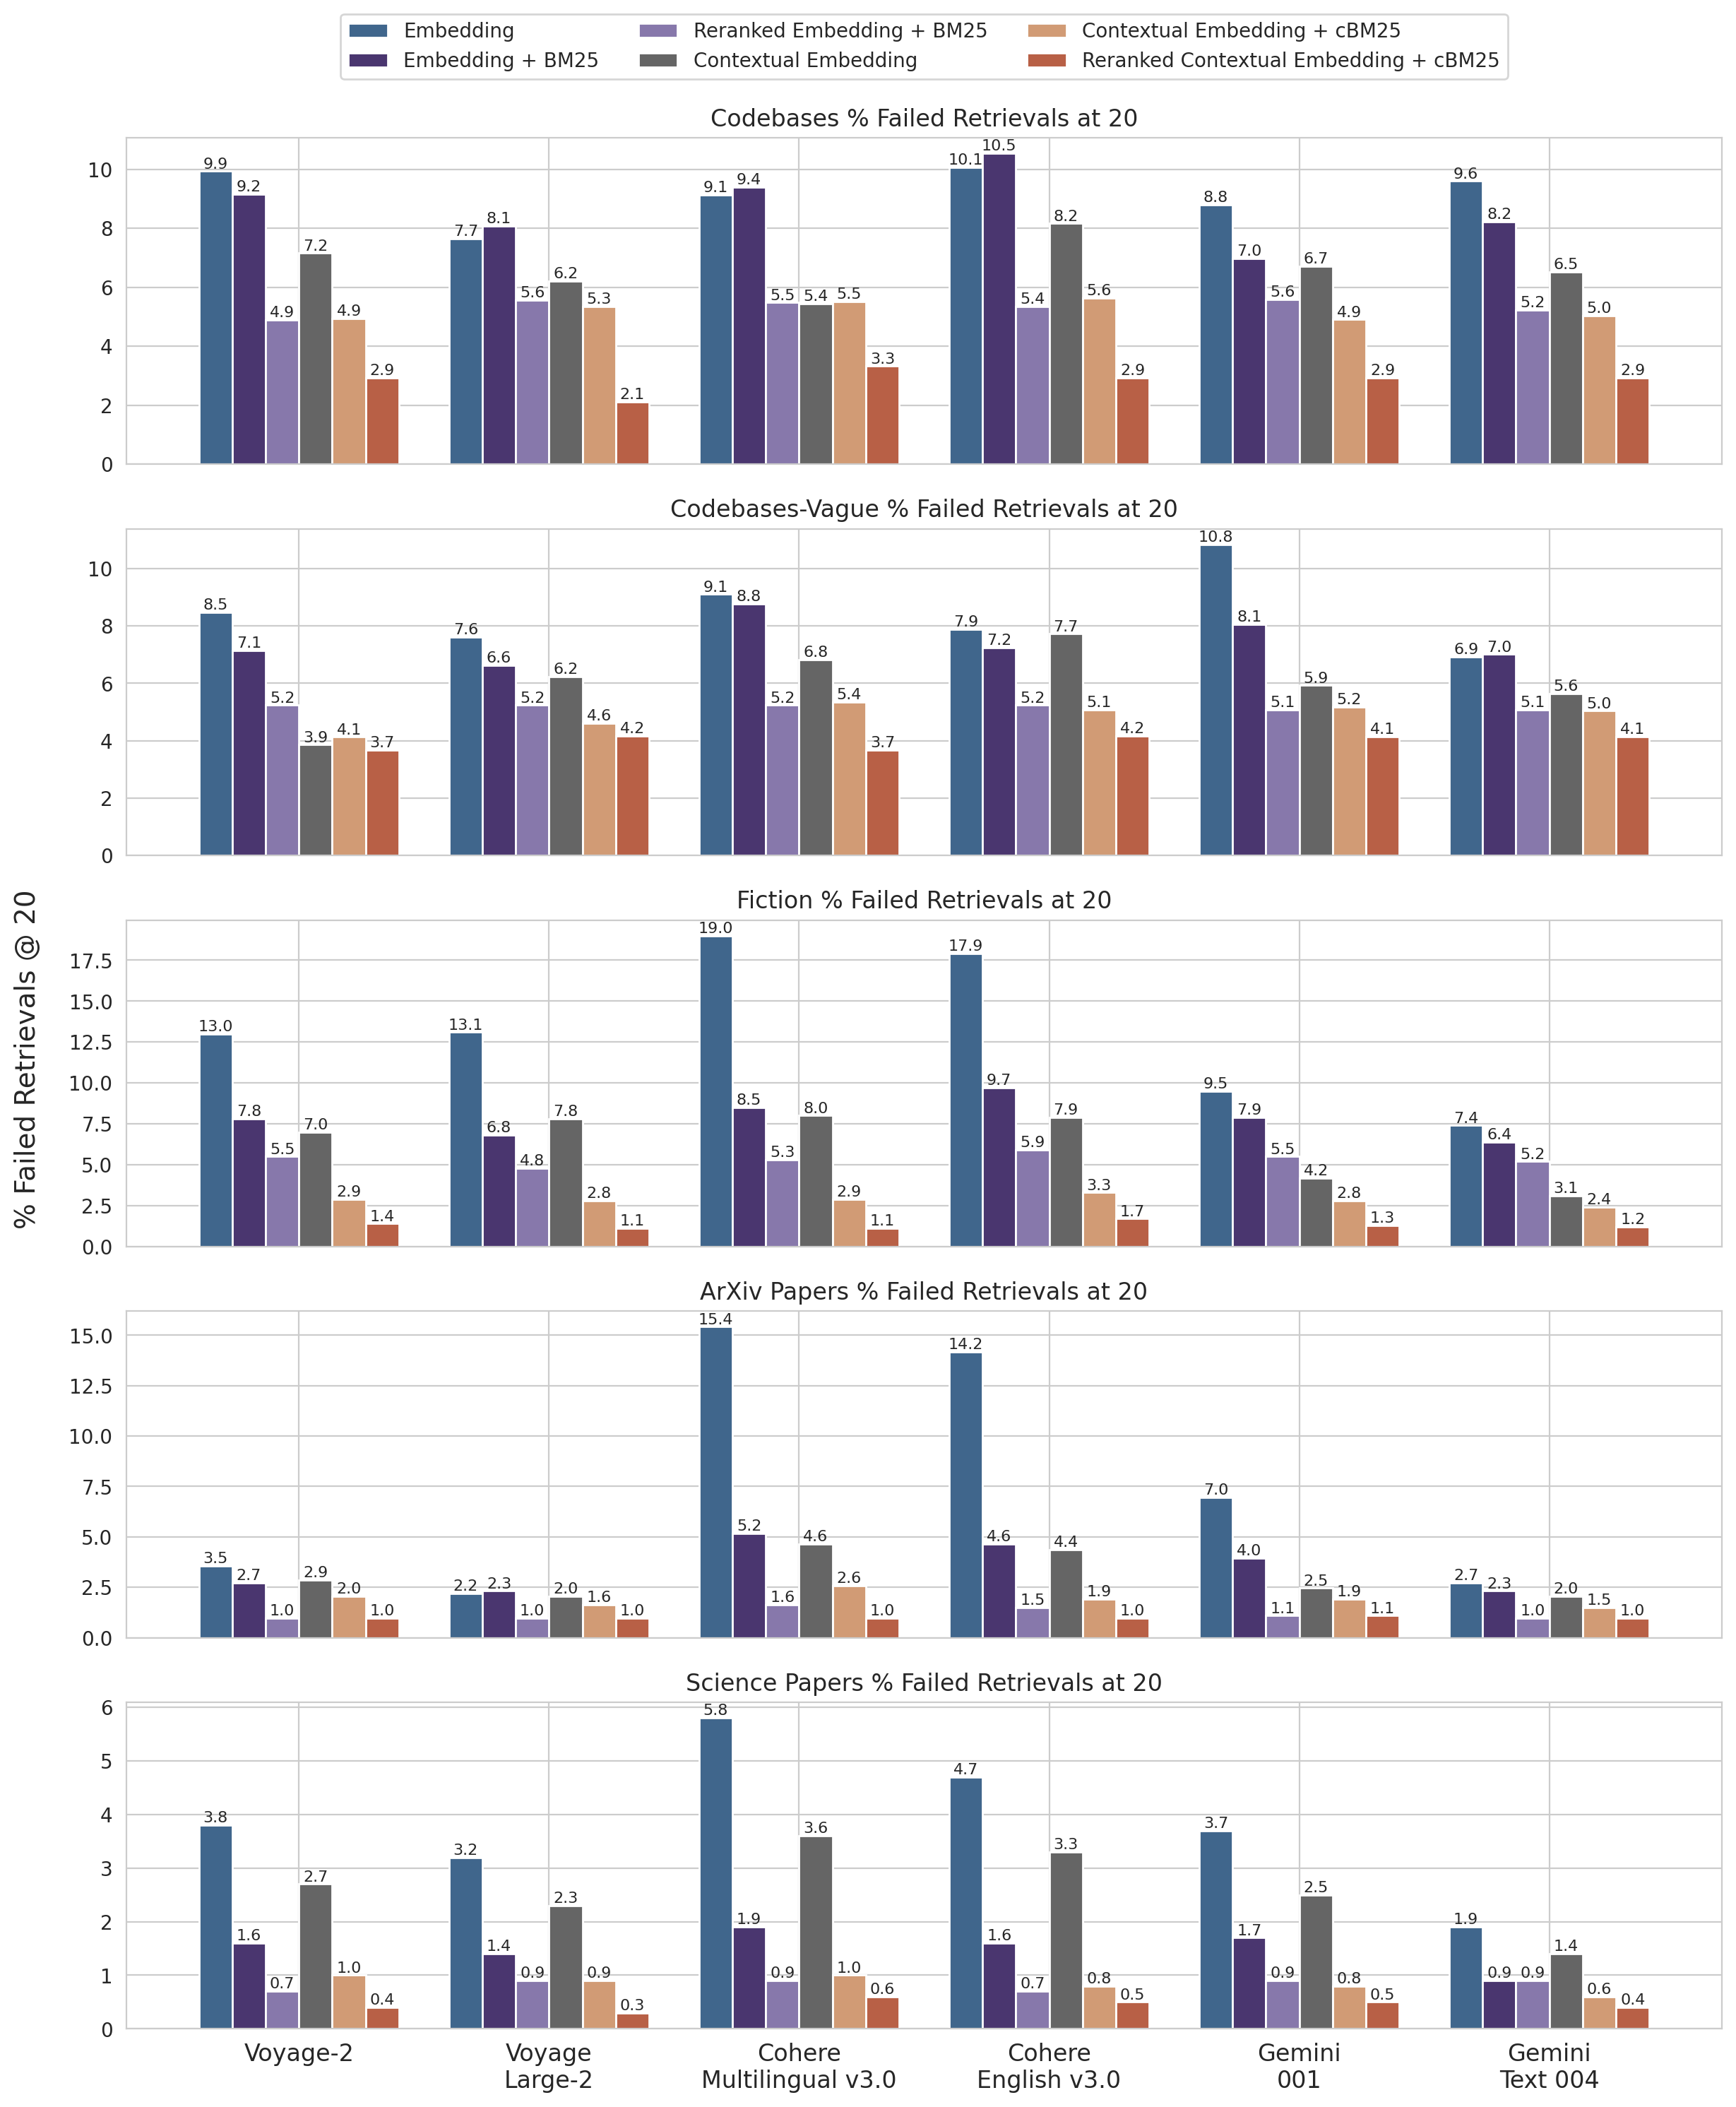
1 minus recall @ 20 results across data sets and embedding providers.
1 减去跨数据集和嵌入提供商的 recall @ 20 结果。
Acknowledgements
致谢
Research and writing by Daniel Ford.
由 Daniel Ford 进行研究和撰写。
Thanks to Orowa Sikder, Gautam Mittal, and Kenneth Lien for critical feedback, Samuel Flamini for implementing the cookbooks, Lauren Polansky for project coordination and Alex Albert, Susan Payne, Stuart Ritchie, and Brad Abrams for shaping this blog post.
感谢 Orowa Sikder、Gautam Mittal 和 Kenneth Lien 提供关键反馈,感谢 Samuel Flamini 实现 cookbooks,感谢 Lauren Polansky 负责项目协调,并感谢 Alex Albert、Susan Payne、Stuart Ritchie 和 Brad Abrams 为这篇博文提供打磨。