使用 MCP 进行代码执行:构建更高效的智能体
Code execution with MCP: Building more efficient agents
文章目录
The Model Context Protocol (MCP) is an open standard for connecting AI agents to external systems.
Model Context Protocol(MCP)是一种开放标准,用于将 AI 智能体(agent)连接到外部系统。
Connecting agents to tools and data traditionally requires a custom integration for each pairing, creating fragmentation and duplicated effort that makes it difficult to scale truly connected systems.
传统上,将智能体连接到工具和数据需要为每一对组合构建自定义集成,这造成了碎片化和重复劳动,使得真正互联的系统难以扩展。
MCP provides a universal protocol—developers implement MCP once in their agent and it unlocks an entire ecosystem of integrations.
MCP 提供了一种通用协议——开发者只需在智能体中实现一次 MCP,就能解锁整个集成生态系统。
Since launching MCP in November 2024, adoption has been rapid: the community has built thousands of MCP servers, SDKs are available for all major programming languages, and the industry has adopted MCP as the de-facto standard for connecting agents to tools and data.
自 2024 年 11 月发布 MCP 以来,其采用速度非常快:社区已经构建了数千个 MCP 服务器,SDK 覆盖所有主流编程语言,业界也已将 MCP 采纳为连接智能体与工具和数据的事实标准。
Today developers routinely build agents with access to hundreds or thousands of tools across dozens of MCP servers.
如今,开发者经常构建能够访问数十个 MCP 服务器中成百上千个工具的智能体。
However, as the number of connected tools grows, loading all tool definitions upfront and passing intermediate results through the context window slows down agents and increases costs.
然而,随着接入工具数量的增长,预先加载所有工具定义,并通过上下文窗口(context window)传递中间结果,会拖慢智能体并增加成本。
In this blog we'll explore how code execution can enable agents to interact with MCP servers more efficiently, handling more tools while using fewer tokens.
在这篇博客中,我们将探讨代码执行如何让智能体更高效地与 MCP 服务器交互,在处理更多工具的同时使用更少的 token。
Excessive token consumption from tools makes agents less efficient
工具带来的过度 token 消耗会降低智能体效率
As MCP usage scales, there are two common patterns that can increase agent cost and latency:
随着 MCP 使用规模扩大,有两种常见模式会增加智能体的成本和延迟:
Tool definitions overload the context window;
工具定义会使上下文窗口过载;
Intermediate tool results consume additional tokens.
中间工具结果会消耗额外的 token。
1. Tool definitions overload the context window
1. 工具定义会使上下文窗口过载
Most MCP clients load all tool definitions upfront directly into context, exposing them to the model using a direct tool-calling syntax.
大多数 MCP 客户端会预先将所有工具定义直接加载到上下文中,并以直接的工具调用语法把它们暴露给模型。
These tool definitions might look like:
这些工具定义可能看起来像:
gdrive.getDocument
     Description: Retrieves a document from Google Drive
     Parameters:
                documentId (required, string): The ID of the document to retrieve
                fields (optional, string): Specific fields to return
Returns: Document object with title, body content, metadata, permissions, etc.salesforce.updateRecord
Description: Updates a record in Salesforce
Parameters:
objectType (required, string): Type of Salesforce object (Lead, Contact, Account, etc.)
recordId (required, string): The ID of the record to update
data (required, object): Fields to update with their new values
Returns: Updated record object with confirmationTool descriptions occupy more context window space, increasing response time and costs.
工具描述会占用更多上下文窗口空间,从而增加响应时间和成本。
In cases where agents are connected to thousands of tools, they’ll need to process hundreds of thousands of tokens before reading a request.
当智能体连接到数千个工具时,它们在读取请求之前就需要处理数十万个 token。
2. Intermediate tool results consume additional tokens
2. 中间工具结果会消耗额外的 token
Most MCP clients allow models to directly call MCP tools.
大多数 MCP 客户端允许模型直接调用 MCP 工具。
For example, you might ask your agent: "Download my meeting transcript from Google Drive and attach it to the Salesforce lead."
例如,你可能会要求你的智能体:“从 Google Drive 下载我的会议转录文本,并将其附加到 Salesforce 潜在客户上。”
The model will make calls like:
模型会发出类似这样的调用:
TOOL CALL: gdrive.getDocument(documentId: "abc123")
        → returns "Discussed Q4 goals...\n[full transcript text]"
           (loaded into model context)

TOOL CALL: salesforce.updateRecord(
			objectType: "SalesMeeting",
			recordId: "00Q5f000001abcXYZ",
  			data: { "Notes": "Discussed Q4 goals...\n[full transcript text written out]" }
		)
(model needs to write entire transcript into context again)Every intermediate result must pass through the model.
每个中间结果都必须经过模型。
In this example, the full call transcript flows through twice.
在这个例子中,完整的通话转录内容会流经两次。
For a 2-hour sales meeting, that could mean processing an additional 50,000 tokens.
对于一场 2 小时的销售会议,这可能意味着额外处理 50,000 个 token。
Even larger documents may exceed context window limits, breaking the workflow.
更大的文档甚至可能超出上下文窗口限制,从而破坏工作流。
With large documents or complex data structures, models may be more likely to make mistakes when copying data between tool calls.
对于大型文档或复杂数据结构,模型在工具调用(tool use)之间复制数据时可能更容易出错。
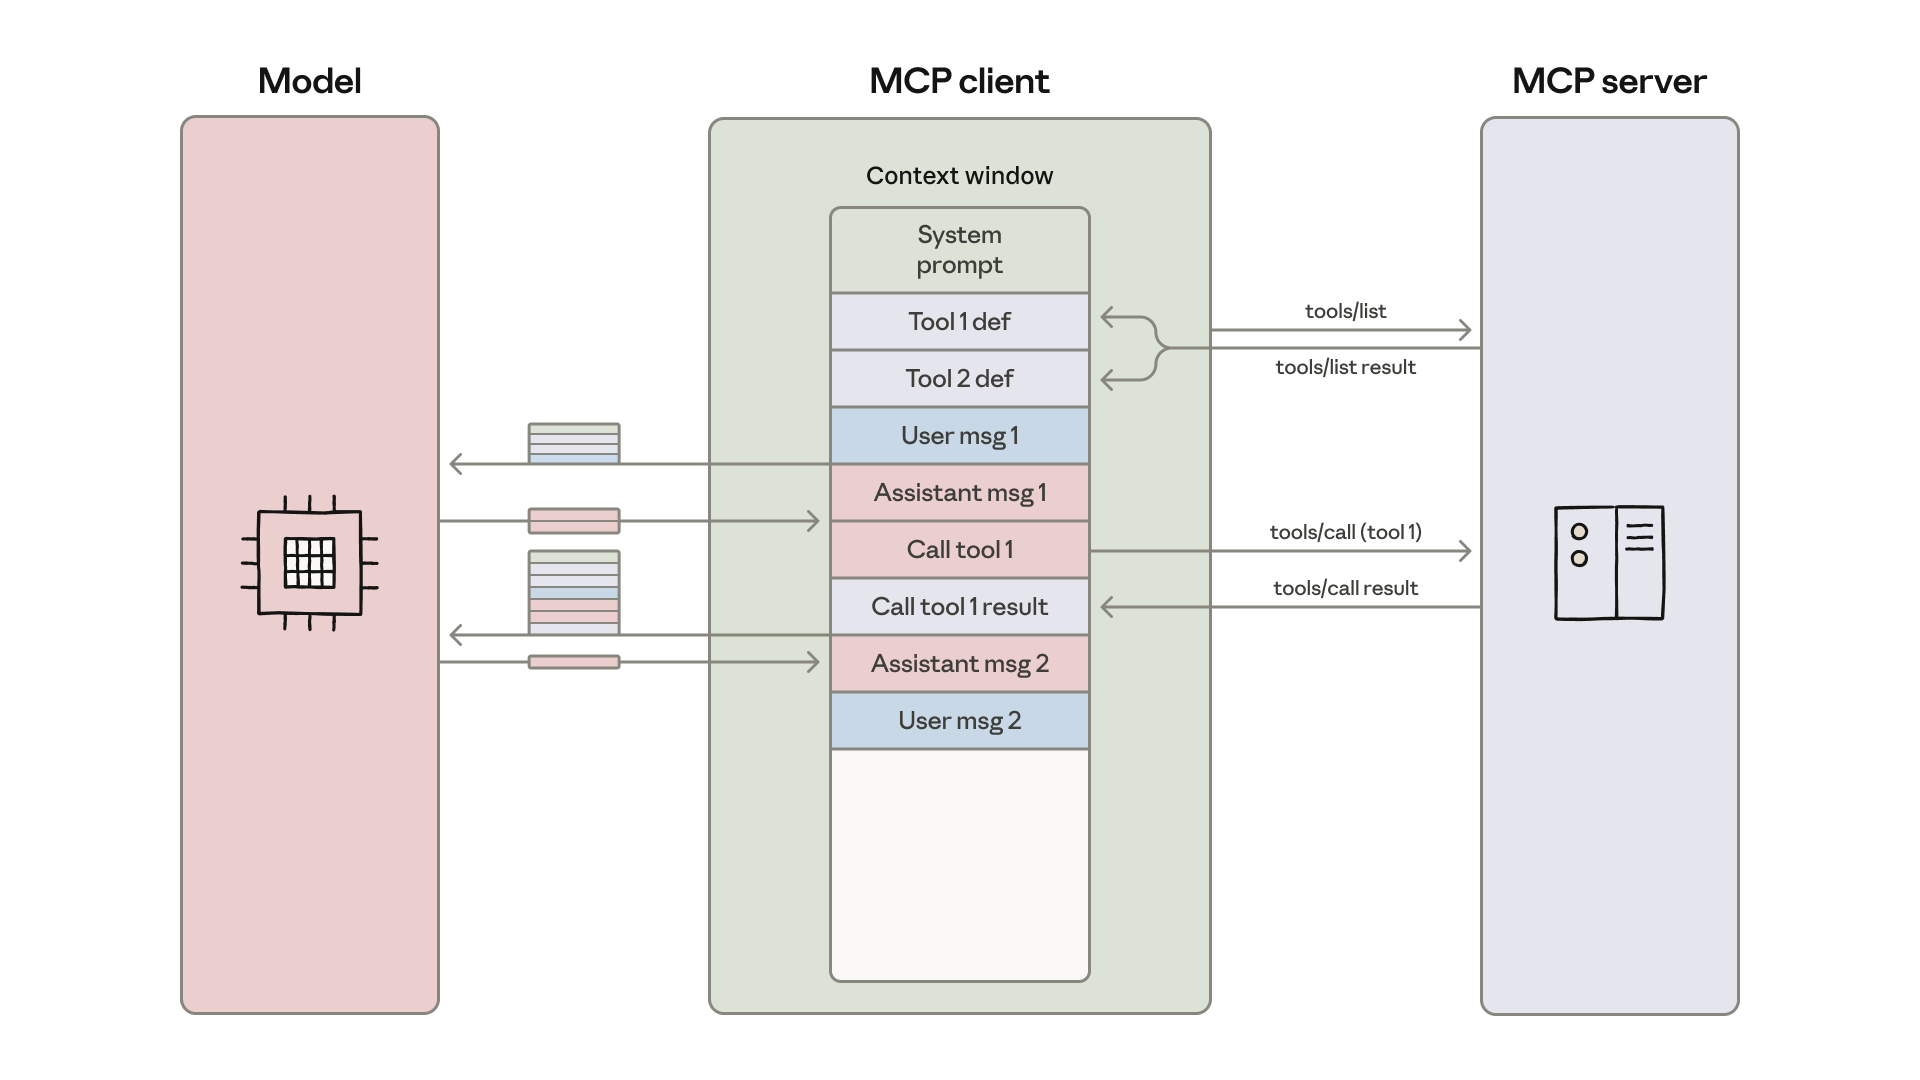
The MCP client loads tool definitions into the model's context window and orchestrates a message loop where each tool call and result passes through the model between operations.
MCP 客户端将工具定义加载到模型的上下文窗口中,并编排(orchestration)一个消息循环,其中每次工具调用和结果都会在操作之间经过模型。
Code execution with MCP improves context efficiency
使用 MCP 的代码执行可提升上下文效率。
With code execution environments becoming more common for agents, a solution is to present MCP servers as code APIs rather than direct tool calls.
随着代码执行环境(code execution environment)在智能体中越来越常见,一种解决方案是将 MCP servers 作为代码 API 呈现,而不是直接工具调用(tool calls)。
The agent can then write code to interact with MCP servers.
随后,智能体可以编写代码来与 MCP servers 交互。
This approach addresses both challenges: agents can load only the tools they need and process data in the execution environment before passing results back to the model.
这种方法同时解决了这两个挑战:智能体可以只加载所需的工具,并在将结果传回模型之前,在执行环境中处理数据。
There are a number of ways to do this.
实现这一点有多种方式。
One approach is to generate a file tree of all available tools from connected MCP servers.
一种方法是从已连接的 MCP servers 生成所有可用工具的文件树(file tree)。
Here's an implementation using TypeScript:
下面是一个使用 TypeScript 的实现:
servers
├── google-drive
│   ├── getDocument.ts
│   ├── ... (other tools)
│   └── index.ts
├── salesforce
│   ├── updateRecord.ts
│   ├── ... (other tools)
│   └── index.ts
└── ... (other servers)Then each tool corresponds to a file, something like:
然后,每个工具对应一个文件,类似这样:
// ./servers/google-drive/getDocument.ts
import { callMCPTool } from "../../../client.js";

interface GetDocumentInput {
  documentId: string;
}

interface GetDocumentResponse {
  content: string;
}

/* Read a document from Google Drive */
export async function getDocument(input: GetDocumentInput): Promise<GetDocumentResponse> {
  return callMCPTool<GetDocumentResponse>('google_drive__get_document', input);
}Our Google Drive to Salesforce example above becomes the code:
我们上面那个 Google Drive 到 Salesforce 的示例就变成了这样的代码:
// Read transcript from Google Docs and add to Salesforce prospect
import * as gdrive from './servers/google-drive';
import * as salesforce from './servers/salesforce';

const transcript = (await gdrive.getDocument({ documentId: 'abc123' })).content;
await salesforce.updateRecord({
  objectType: 'SalesMeeting',
  recordId: '00Q5f000001abcXYZ',
  data: { Notes: transcript }
});The agent discovers tools by exploring the filesystem: listing the ./servers/directory to find available servers (like google-drive and salesforce), then reading the specific tool files it needs (like getDocument.ts and updateRecord.ts) to understand each tool's interface.
智能体通过探索文件系统来发现工具:列出 ./servers/目录以找到可用的 servers(如 google-drive 和 salesforce),然后读取它需要的具体工具文件(如 getDocument.ts 和 updateRecord.ts)来了解每个工具的接口。
This lets the agent load only the definitions it needs for the current task.
这让智能体可以只加载当前任务所需的定义。
This reduces the token usage from 150,000 tokens to 2,000 tokens—a time and cost saving of 98.7%.
这使 token 用量从 150,000 tokens 减少到 2,000 tokens——节省了 98.7% 的时间和成本。
Cloudflare published similar findings, referring to code execution with MCP as “Code Mode."
Cloudflare 发布了类似的研究结果,将配合 MCP 的代码执行称为 “Code Mode”。
The core insight is the same: LLMs are adept at writing code and developers should take advantage of this strength to build agents that interact with MCP servers more efficiently.
核心洞见是一样的:LLM 擅长编写代码,开发者应该利用这一优势来构建能更高效地与 MCP servers 交互的智能体。
Benefits of code execution with MCP
使用 MCP 进行代码执行的优势
Code execution with MCP enables agents to use context more efficiently by loading tools on demand, filtering data before it reaches the model, and executing complex logic in a single step.
使用 MCP 进行代码执行,可以让智能体按需加载工具、在数据到达模型之前先做过滤,并在单一步骤中执行复杂逻辑,从而更高效地利用上下文。
There are also security and state management benefits to using this approach.
采用这种方法在安全性和状态管理方面也有好处。
Progressive disclosure
渐进式披露
Models are great at navigating filesystems.
模型非常擅长浏览文件系统。
Presenting tools as code on a filesystem allows models to read tool definitions on-demand, rather than reading them all up-front.
把工具以代码的形式呈现在文件系统上,可以让模型按需读取工具定义,而不是一次性全部读完。
Alternatively, a search_tools tool can be added to the server to find relevant definitions.
另一种做法是,在服务器中添加一个 search_tools 工具来查找相关定义。
For example, when working with the hypothetical Salesforce server used above, the agent searches for "salesforce" and loads only those tools that it needs for the current task.
例如,在使用前面假设的 Salesforce 服务器时,智能体搜索「salesforce」,只加载当前任务所需的那些工具。
Including a detail level parameter in the search_tools tool that allows the agent to select the level of detail required (such as name only, name and description, or the full definition with schemas) also helps the agent conserve context and find tools efficiently.
在 search_tools 工具中加入 detail level 参数,让智能体可以选择所需的详细程度(例如仅名称、名称与描述,或包含 schema 的完整定义),这也有助于智能体节省上下文并高效地找到工具。
Context efficient tool results
上下文高效的工具结果
When working with large datasets, agents can filter and transform results in code before returning them.
处理大型数据集时,智能体可以在返回结果之前用代码对结果进行过滤和转换。
Consider fetching a 10,000-row spreadsheet:
设想获取一个包含 10,000 行的电子表格:
// Without code execution - all rows flow through context
TOOL CALL: gdrive.getSheet(sheetId: 'abc123')
        → returns 10,000 rows in context to filter manually

// With code execution - filter in the execution environment
const allRows = await gdrive.getSheet({ sheetId: 'abc123' });
const pendingOrders = allRows.filter(row =>
  row["Status"] === 'pending'
);
console.log(`Found ${pendingOrders.length} pending orders`);
console.log(pendingOrders.slice(0, 5)); // Only log first 5 for reviewThe agent sees five rows instead of 10,000.
智能体看到的是五行,而不是 10,000 行。
Similar patterns work for aggregations, joins across multiple data sources, or extracting specific fields—all without bloating the context window.
类似的模式也适用于聚合、跨多个数据源的连接,或提取特定字段——这些都不会让上下文窗口膨胀。
More powerful and context-efficient control flow
更强大且更节省上下文的控制流
Loops, conditionals, and error handling can be done with familiar code patterns rather than chaining individual tool calls.
循环、条件分支和错误处理可以用熟悉的代码模式来实现,而不必串联一个个工具调用。
For example, if you need a deployment notification in Slack, the agent can write:
例如,如果你需要在 Slack 中发送部署通知,智能体可以编写:
let found = false;
while (!found) {
  const messages = await slack.getChannelHistory({ channel: 'C123456' });
  found = messages.some(m => m.text.includes('deployment complete'));
  if (!found) await new Promise(r => setTimeout(r, 5000));
}
console.log('Deployment notification received');This approach is more efficient than alternating between MCP tool calls and sleep commands through the agent loop.
这种方法比在智能体循环中交替使用 MCP 工具调用和 sleep 命令更高效。
Additionally, being able to write out a conditional tree that gets executed also saves on “time to first token” latency: rather than having to wait for a model to evaluate an if-statement, the agent can let the code execution environment do this.
此外,能够写出一个会被执行的条件树,也能节省「首 token 时间(time to first token)」延迟:智能体不必等待模型来求值一个 if 语句,而是可以让代码执行环境来完成这件事。
Privacy-preserving operations
隐私保护操作
When agents use code execution with MCP, intermediate results stay in the execution environment by default.
当智能体通过 MCP 使用代码执行时,中间结果默认保留在执行环境中。
This way, the agent only sees what you explicitly log or return, meaning data you don’t wish to share with the model can flow through your workflow without ever entering the model's context.
这样,智能体只能看到你显式记录或返回的内容,这意味着你不希望与模型共享的数据可以在你的工作流中流转,而永远不会进入模型的上下文。
For even more sensitive workloads, the agent harness can tokenize sensitive data automatically.
对于更敏感的工作负载,智能体框架(harness)可以自动对敏感数据进行 token 化。
For example, imagine you need to import customer contact details from a spreadsheet into Salesforce.
例如,假设你需要将客户联系方式从电子表格导入 Salesforce。
The agent writes:
智能体编写:
const sheet = await gdrive.getSheet({ sheetId: 'abc123' });
for (const row of sheet.rows) {
  await salesforce.updateRecord({
    objectType: 'Lead',
    recordId: row.salesforceId,
    data: {
      Email: row.email,
      Phone: row.phone,
      Name: row.name
    }
  });
}
console.log(`Updated ${sheet.rows.length} leads`);The MCP client intercepts the data and tokenizes PII before it reaches the model:
MCP 客户端会拦截数据,并在数据到达模型之前对 PII 进行 token 化:
// What the agent would see, if it logged the sheet.rows:
[
  { salesforceId: '00Q...', email: '[EMAIL_1]', phone: '[PHONE_1]', name: '[NAME_1]' },
  { salesforceId: '00Q...', email: '[EMAIL_2]', phone: '[PHONE_2]', name: '[NAME_2]' },
  ...
]Then, when the data is shared in another MCP tool call, it is untokenized via a lookup in the MCP client.
然后,当数据在另一个 MCP 工具调用中被共享时,它会通过 MCP 客户端中的查找被去 token 化。
The real email addresses, phone numbers, and names flow from Google Sheets to Salesforce, but never through the model.
真实的电子邮件地址、电话号码和姓名从 Google Sheets 流向 Salesforce,但绝不会经过模型。
This prevents the agent from accidentally logging or processing sensitive data.
这可以防止智能体意外记录或处理敏感数据。
You can also use this to define deterministic security rules, choosing where data can flow to and from.
你还可以用它来定义确定性的安全规则,选择数据可以流向哪里以及从哪里流入。
State persistence and skills
状态持久化与技能
Code execution with filesystem access allows agents to maintain state across operations.
具备文件系统访问能力的代码执行(code execution)允许智能体跨操作保持状态。
Agents can write intermediate results to files, enabling them to resume work and track progress:
智能体可以将中间结果写入文件,从而能够恢复工作并跟踪进度:
const leads = await salesforce.query({
  query: 'SELECT Id, Email FROM Lead LIMIT 1000'
});
const csvData = leads.map(l => `${l.Id},${l.Email}`).join('\n');
await fs.writeFile('./workspace/leads.csv', csvData);

// Later execution picks up where it left off
const saved = await fs.readFile('./workspace/leads.csv', 'utf-8');Agents can also persist their own code as reusable functions.
智能体还可以将自己的代码持久化为可复用函数。
Once an agent develops working code for a task, it can save that implementation for future use:
一旦智能体为某项任务开发出可运行的代码,就可以保存该实现以供将来使用:
// In ./skills/save-sheet-as-csv.ts
import * as gdrive from './servers/google-drive';
export async function saveSheetAsCsv(sheetId: string) {
  const data = await gdrive.getSheet({ sheetId });
  const csv = data.map(row => row.join(',')).join('\n');
  await fs.writeFile(`./workspace/sheet-${sheetId}.csv`, csv);
  return `./workspace/sheet-${sheetId}.csv`;
}

// Later, in any agent execution:
import { saveSheetAsCsv } from './skills/save-sheet-as-csv';
const csvPath = await saveSheetAsCsv('abc123');This ties in closely to the concept of Skills, folders of reusable instructions, scripts, and resources for models to improve performance on specialized tasks.
这与 Skills 的概念密切相关,Skills 是包含可复用指令、脚本和资源的文件夹,供模型提升在专门任务上的表现。
Adding a SKILL.md file to these saved functions creates a structured skill that models can reference and use.
向这些保存下来的函数中添加一个 SKILL.md 文件,就能创建一个结构化技能,供模型引用和使用。
Over time, this allows your agent to build a toolbox of higher-level capabilities, evolving the scaffolding that it needs to work most effectively.
随着时间推移,这使你的智能体能够构建一个更高层能力的工具箱,并逐步演化出它最有效工作所需的脚手架。
Note that code execution introduces its own complexity.
注意,代码执行会带来它自身的复杂性。
Running agent-generated code requires a secure execution environment with appropriate sandboxing, resource limits, and monitoring.
运行智能体生成的代码需要一个安全执行环境,并配备适当的沙箱(sandbox)、资源限制和监控。
These infrastructure requirements add operational overhead and security considerations that direct tool calls avoid.
这些基础设施要求会带来直接工具调用所没有的运维开销和安全考量。
The benefits of code execution—reduced token costs, lower latency, and improved tool composition—should be weighed against these implementation costs.
代码执行的好处——降低 token 成本、减少延迟、改进工具组合——应当与这些实现成本进行权衡。
Summary
总结
MCP provides a foundational protocol for agents to connect to many tools and systems.
MCP 为智能体连接众多工具和系统提供了一个基础协议(protocol)。
However, once too many servers are connected, tool definitions and results can consume excessive tokens, reducing agent efficiency.
然而,一旦连接了过多服务器,工具定义和结果可能会消耗过多 token,降低智能体效率。
Although many of the problems here feel novel—context management, tool composition, state persistence—they have known solutions from software engineering.
尽管这里的许多问题——上下文管理(context management)、工具组合(tool composition)、状态持久化(state persistence)——看起来新颖,但软件工程(software engineering)中已有已知的解决方案。
Code execution applies these established patterns to agents, letting them use familiar programming constructs to interact with MCP servers more efficiently.
代码执行将这些已确立的模式应用于智能体,使它们能够使用熟悉的编程结构来更高效地与 MCP 服务器交互。
If you implement this approach, we encourage you to share your findings with the MCP community.
如果你实现了这种方法,我们鼓励你与 MCP 社区分享你的发现。
Acknowledgments
致谢
This article was written by Adam Jones and Conor Kelly.
本文由 Adam Jones 和 Conor Kelly 撰写。
Thanks to Jeremy Fox, Jerome Swannack, Stuart Ritchie, Molly Vorwerck, Matt Samuels, and Maggie Vo for feedback on drafts of this post.
感谢 Jeremy Fox、Jerome Swannack、Stuart Ritchie、Molly Vorwerck、Matt Samuels 和 Maggie Vo 对本文草稿的反馈。