关于近期 Claude Code 质量报告的更新
An update on recent Claude Code quality reports
段落导航
Over the past month, we’ve been looking into reports that Claude’s responses have worsened for some users.
在过去一个月里,我们一直在调查有关部分用户认为 Claude 的回复变差的报告。
We’ve traced these reports to three separate changes that affected Claude Code, the Claude Agent SDK, and Claude Cowork.
我们已将这些报告追溯到三项分别影响了 Claude Code、Claude Agent SDK 和 Claude Cowork 的不同变更。
The API was not impacted.
API 没有受到影响。
All three issues have now been resolved as of April 20 (v2.1.116).
截至 4 月 20 日(v2.1.116),所有三个问题现在都已解决。
In this post, we explain what we found, what we fixed, and what we’ll do differently to ensure similar issues are much less likely to happen again.
在本文中,我们解释了我们发现了什么、修复了什么,以及我们将如何改变做法,以确保类似问题再次发生的可能性大大降低。
We take reports about degradation very seriously.
我们非常重视有关性能下降(degradation)的报告。
We never intentionally degrade our models, and we were able to immediately confirm that our API and inference layer were unaffected.
我们从未有意降低我们模型的能力,并且我们能够立即确认我们的 API 和推理层(inference layer)没有受到影响。
After investigation, we identified three different issues:
经过调查,我们确定了三个不同的问题:
On March 4, we changed Claude Code's default reasoning effort from high to medium to reduce the very long latency—enough to make the UI appear frozen—some users were seeing in high mode.
3 月 4 日,我们将 Claude Code 的默认推理强度(reasoning effort)从 high 改为 medium,以缩短部分用户在 high 模式下遇到的极长延迟——这种延迟足以让 UI 看起来像卡死。
This was the wrong tradeoff.
这是一个错误的权衡。
We reverted this change on April 7 after users told us they'd prefer to default to higher intelligence and opt into lower effort for simple tasks.
在用户告诉我们,他们更愿意默认使用更高智能水平、并在简单任务中选择较低投入后,我们于 4 月 7 日回滚了这项变更。
This impacted Sonnet 4.6 and Opus 4.6.
这影响了 Sonnet 4.6 和 Opus 4.6。
On March 26, we shipped a change to clear Claude's older thinking from sessions that had been idle for over an hour, to reduce latency when users resumed those sessions.
3 月 26 日,我们发布了一项改动,用于清除空闲超过一小时的会话中 Claude 较早的思考内容,以降低用户恢复这些会话时的延迟。
A bug caused this to keep happening every turn for the rest of the session instead of just once, which made Claude seem forgetful and repetitive.
一个 bug 导致该操作在会话剩余时间里每一轮都持续发生,而不是只执行一次,这让 Claude 显得健忘且重复。
We fixed it on April 10.
我们在 4 月 10 日修复了它。
This affected Sonnet 4.6 and Opus 4.6.
这影响了 Sonnet 4.6 和 Opus 4.6。
On April 16, we added a system prompt instruction to reduce verbosity.
4 月 16 日,我们添加了一条系统提示词(system prompt)指令以减少冗长。
In combination with other prompt changes, it hurt coding quality and was reverted on April 20.
它与其他提示词改动叠加后,损害了编码质量,并于 4 月 20 日被回滚。
This impacted Sonnet 4.6, Opus 4.6, and Opus 4.7.
这影响了 Sonnet 4.6、Opus 4.6 和 Opus 4.7。
Because each change affected a different slice of traffic on a different schedule, the aggregate effect looked like broad, inconsistent degradation.
由于每项改动影响的流量切片不同、生效时间也不同,累加后的效果看起来像是大范围且不稳定的退化。
While we began investigating reports in early March, they were challenging to distinguish from normal variation in user feedback at first, and neither our internal usage nor evals initially reproduced the issues identified.
虽然我们在 3 月初就开始调查相关报告,但起初很难将它们与用户反馈中的正常波动区分开来,而且我们的内部使用情况和我们自己的评测(eval)最初都未能复现所发现的问题。
This isn’t the experience users should expect from Claude Code.
这不是用户应该从 Claude Code 得到的体验。
As of April 23, we’re resetting usage limits for all subscribers.
自 4 月 23 日起,我们将为所有订阅者重置使用额度。
When we released Opus 4.6 in Claude Code in February, we set the default reasoning effort to high.
当我们在 2 月于 Claude Code 中发布 Opus 4.6 时,我们将默认推理强度设为 high。
Soon after, we received user feedback that Claude Opus 4.6 in high effort mode would occasionally think for too long, causing the UI to appear frozen and leading to disproportionate latency and token usage for those users.
不久之后,我们收到用户反馈:处于 high 推理强度模式的 Claude Opus 4.6 偶尔会思考过久,导致 UI 看起来像是卡住了,并让这些用户遭遇不成比例的延迟和 token 消耗。
In general, the longer the model thinks, the better the output.
一般来说,模型思考得越久,输出就越好。
Effort levels are how Claude Code lets users set that tradeoff—more thinking versus lower latency and fewer usage limit hits.
努力等级(effort level)是 Claude Code 让用户设定这一权衡的方式——更多思考,还是更低延迟与更少触及用量上限。
As we calibrate effort levels for our models, we take this tradeoff into account in order to pick points along the test-time-compute curve that give people the best range of options.
在为我们的模型校准努力等级时,我们会把这一权衡考虑在内,以便在测试时计算(test-time compute)曲线上挑选出能为人们提供最佳选项范围的点。
In the product layer, we then choose which point along this curve we set as our default, and that is the value we send to the Messages API as the effort parameter; we then make the other options available via /effort.
在产品层,我们再决定把这条曲线上的哪个点设为默认值,这就是我们作为 effort 参数发送给 Messages API 的值;随后我们通过 /effort 提供其他选项。
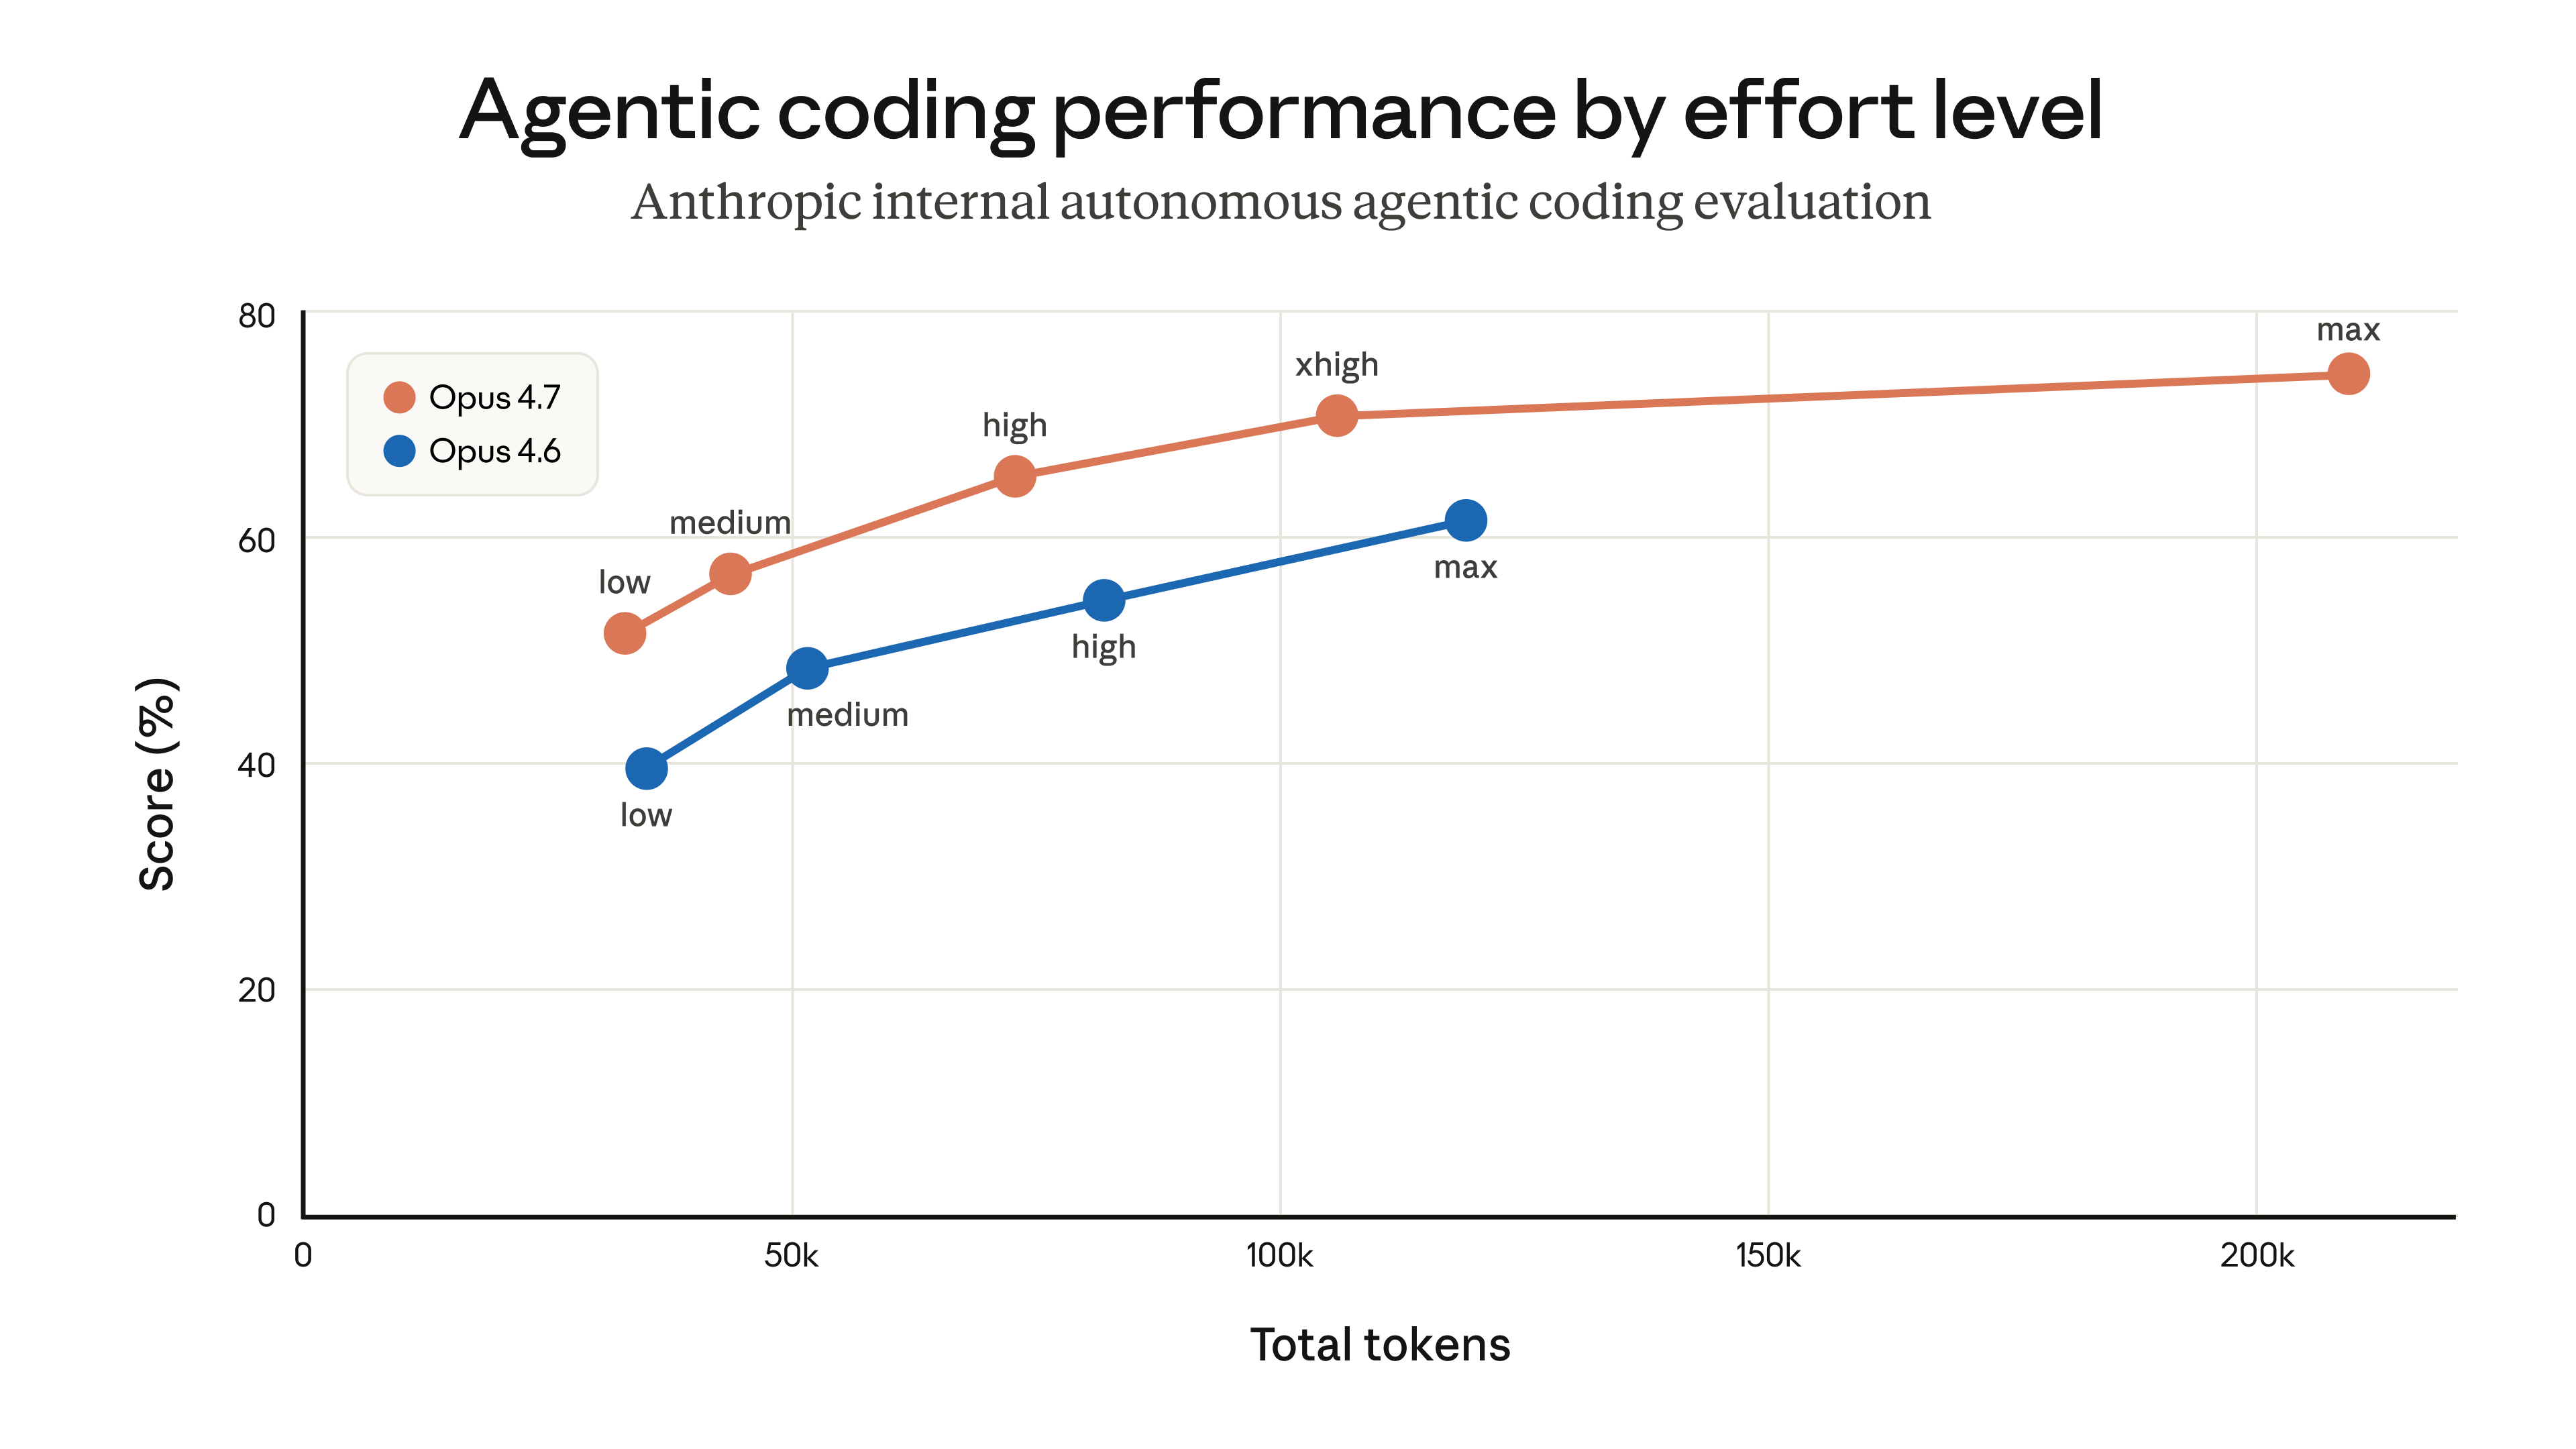
In our internal evals and testing, medium effort achieved slightly lower intelligence with significantly less latency for the majority of tasks.
在我们的内部评测和测试中,中档努力在大多数任务上以显著更低的延迟实现了略低的智能水平。
It also didn’t suffer from the same issues with occasional very long tail latencies for thinking, and it helped maximize users’ usage limits.
它也没有出现思考偶尔产生极长尾延迟的同类问题,并且有助于让用户的用量上限发挥最大价值。
As a result, we rolled out a change making medium the default effort, and explained the rationale via in-product dialog.
因此,我们发布了一项变更,将中档努力设为默认,并通过产品内对话框说明了理由。
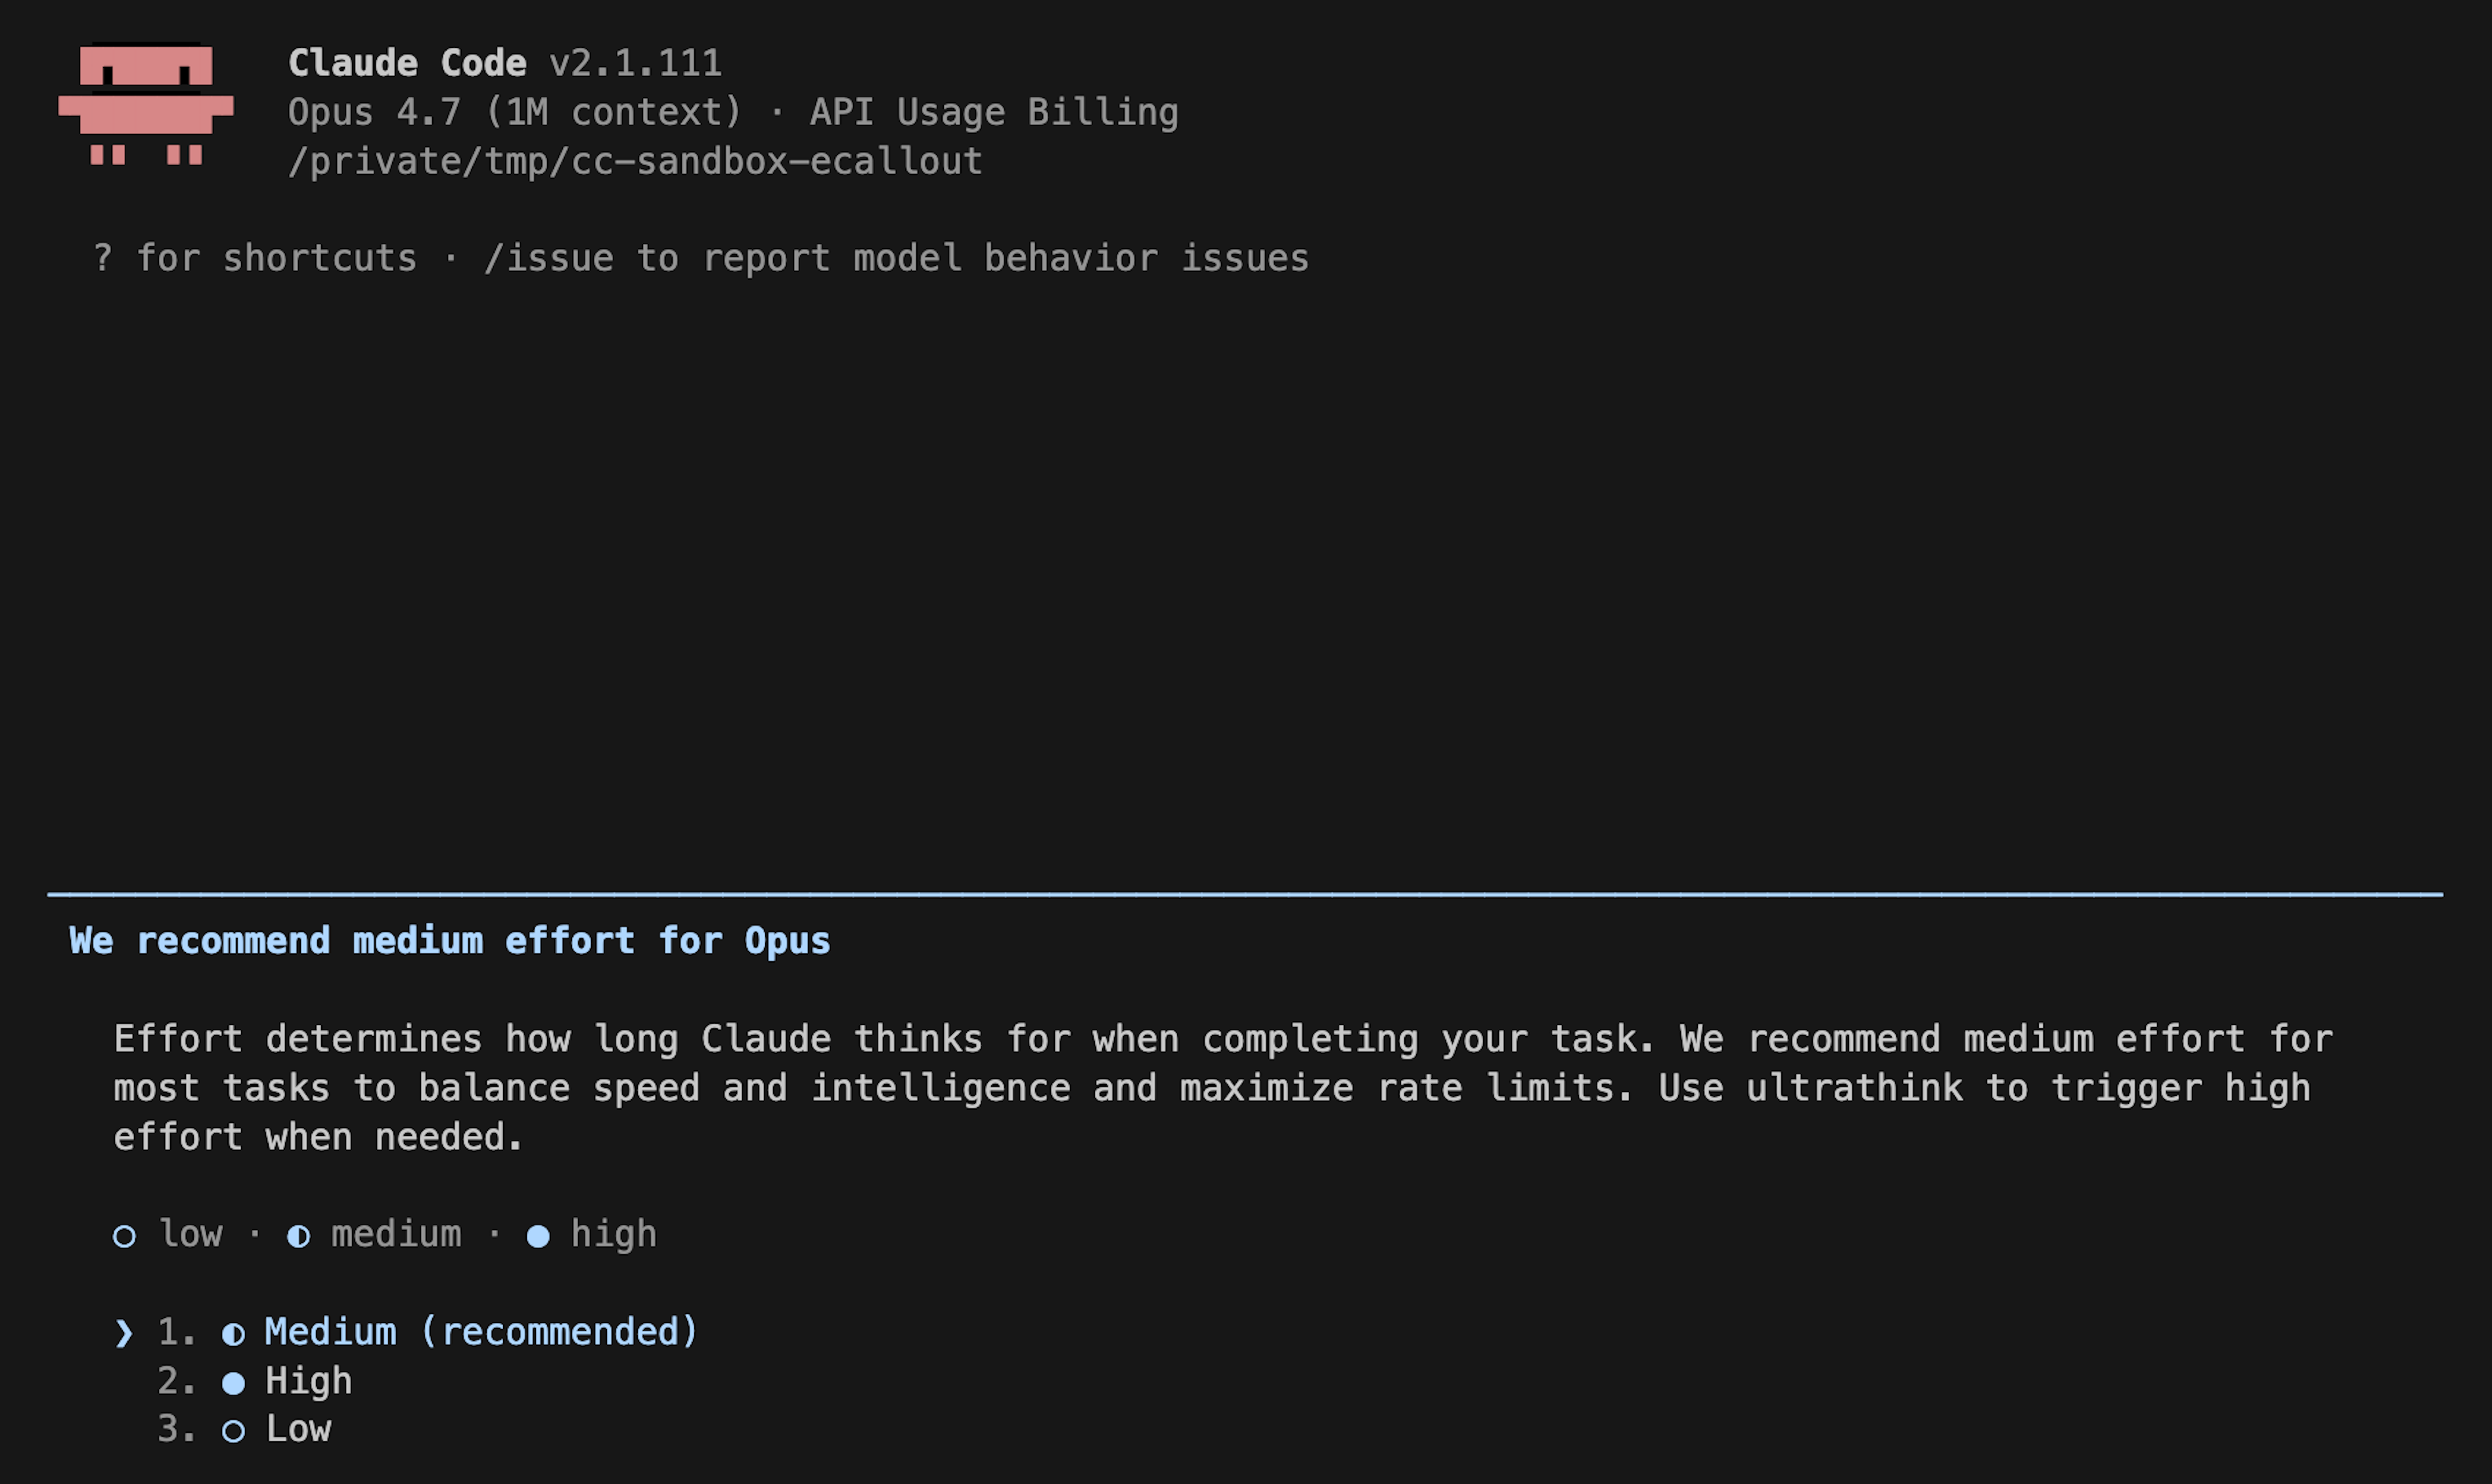
Soon after rolling out, users began reporting that Claude Code felt less intelligent.
发布后不久,用户开始反馈 Claude Code 感觉没那么聪明了。
We shipped a number of design iterations to make the current effort setting clearer in order to alert people they could change the default (notices on startup, an inline effort selector, and bringing back ultrathink), but most users retained the medium effort default.
我们发布了多轮设计迭代,让当前的努力设置更清晰,以提醒人们可以更改默认值(启动时的提示、内联的努力选择器,以及重新带回 ultrathink),但大多数用户仍保留了中档努力这一默认值。
After hearing feedback from more customers, we reversed this decision on April 7.
在听取更多客户的反馈后,我们在 4 月 7 日撤回了这一决定。
All users now default to xhigh effort for Opus 4.7, and high effort for all other models.
现在所有用户在 Opus 4.7 上默认使用 xhigh 努力等级,在其他所有模型上默认使用 high 努力等级。
When Claude reasons through a task, that reasoning is normally kept in the conversation history so that on every subsequent turn, Claude can see why it made the edits and tool calls it did.
当 Claude 对一项任务进行推理时,这些推理通常会保留在对话历史中,这样在之后的每一轮,Claude 都能看到自己当初为什么做那些编辑和工具调用。
On March 26, we shipped what was meant to be an efficiency improvement to this feature.
3 月 26 日,我们发布了一项本意是提升该功能效率的改进。
We use prompt caching to make back-to-back API calls cheaper and faster for users.
我们使用提示词缓存(prompt caching)来让用户连续多次 API 调用的成本更低、速度更快。
Claude writes the input tokens to the cache when it makes an API request, then after a period of inactivity the prompt is evicted from cache, making room for other prompts.
Claude 在发起 API 请求时会把输入 token 写入缓存,随后在一段无活动时间之后,该提示词会被从缓存中逐出,为其他提示词腾出空间。
Cache utilization is something we manage carefully (more on our approach).
缓存利用率是我们会谨慎管理的事项(关于我们的做法还有更多说明)。
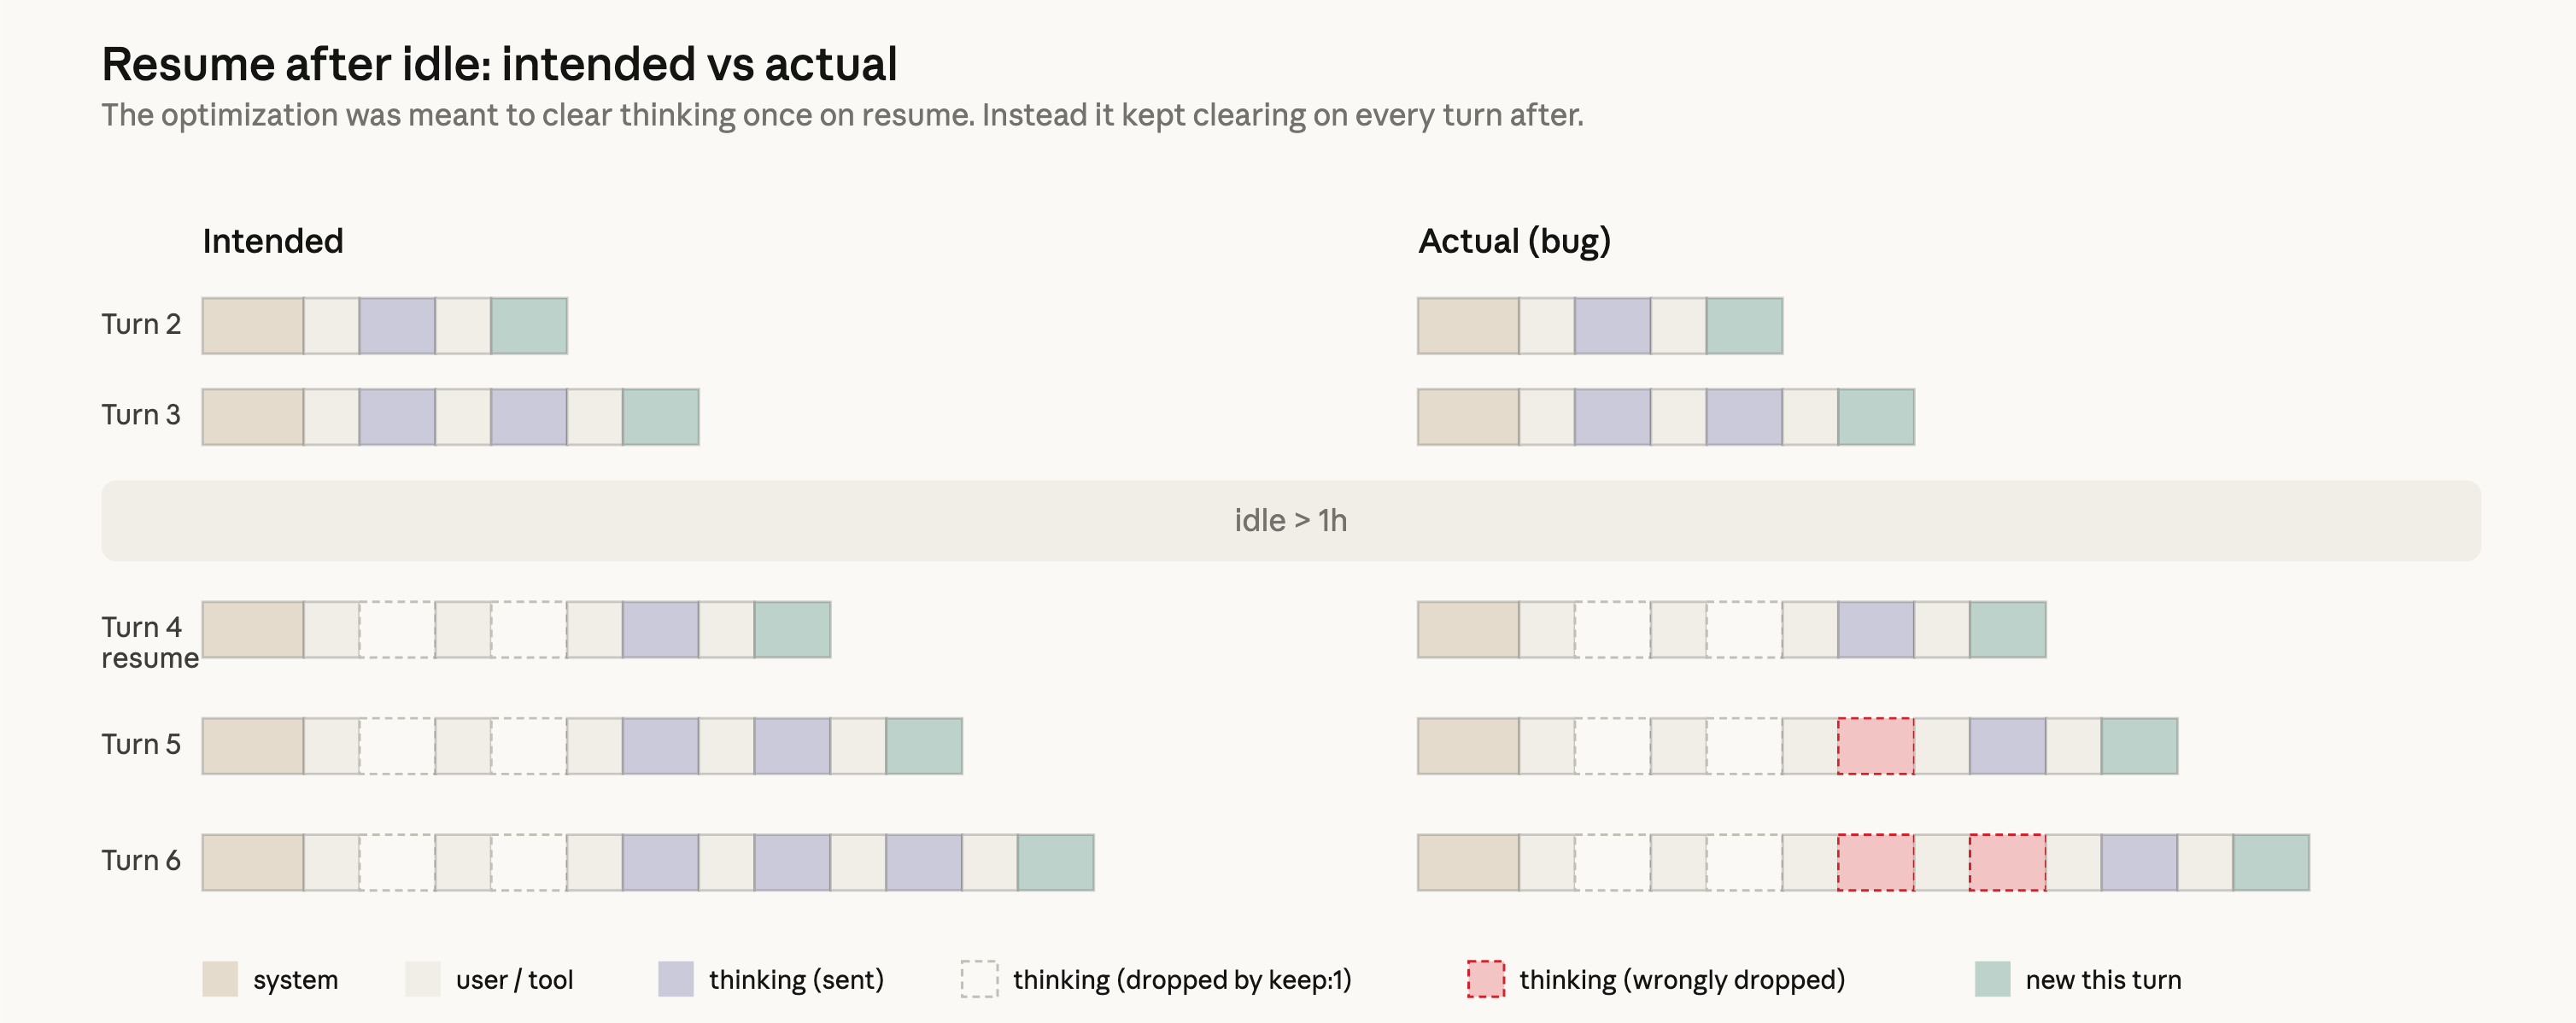
The design should have been simple: if a session has been idle for more than an hour, we could reduce users’ cost of resuming that session by clearing old thinking sections.
这个设计本应很简单:如果一个会话空闲超过一小时,我们就可以通过清除旧的思考内容,降低用户恢复该会话的成本。
Since the request would be a cache miss anyway, we could prune unnecessary messages from the request to reduce the number of uncached tokens sent to the API.
由于这个请求无论如何都会是缓存未命中(cache miss),我们可以从请求中裁剪掉不必要的消息,以减少发送给 API 的未缓存 token 数量。
We’d then resume sending full reasoning history.
之后我们再恢复发送完整的推理历史。
To do this we used the clear_thinking_20251015 API header along with keep:1.
为此,我们使用了 clear_thinking_20251015 API 请求头以及 keep:1。
The implementation had a bug.
这个实现有一个 bug。
Instead of clearing thinking history once, it cleared it on every turn for the rest of the session.
它不是只清除一次思考历史,而是在该会话剩余的每一轮都清除一次。
After a session crossed the idle threshold once, each request for the rest of that process told the API to keep only the most recent block of reasoning and discard everything before it.
一旦某个会话越过空闲阈值,该进程后续的每个请求都会告诉 API 只保留最近的一段推理内容,并丢弃它之前的所有内容。
This compounded: if you sent a follow-up message while Claude was in the middle of a tool use, that started a new turn under the broken flag, so even the reasoning from the current turn was dropped.
问题还会叠加:如果你在 Claude 正在进行工具调用时发送一条追问消息,这会在错误标志生效的状态下开启新一轮,于是连当前这一轮的推理内容也被丢弃了。
Claude would continue executing, but increasingly without memory of why it had chosen to do what it was doing.
Claude 会继续执行,但越来越不记得自己为什么选择做正在做的事。
This surfaced as the forgetfulness, repetition, and odd tool choices people reported.
这就表现为用户所报告的健忘、重复以及奇怪的工具选择。
Because this would continuously drop thinking blocks from subsequent requests, those requests also resulted in cache misses.
因为这会在后续请求中持续丢弃思考块,那些请求也会导致缓存未命中。
We believe this is what drove the separate reports of usage limits draining faster than expected.
我们认为,正是这一点导致了另外那些关于用量限额消耗速度快于预期的报告。
Two unrelated experiments made it challenging for us to reproduce the issue at first: an internal-only server-side experiment related to message queuing; and an orthogonal change in how we display thinking suppressed this bug in most CLI sessions, so we didn’t catch it even when testing external builds.
两个互不相关的实验让我们一开始难以复现该问题:一个仅限内部的、与消息排队相关的服务端实验;以及我们在思考内容展示方式上的一项正交改动,它在大多数 CLI 会话中掩盖了这个 bug,以至于我们即使测试外部构建版本时也没有发现它。
This bug was at the intersection of Claude Code’s context management, the Anthropic API, and extended thinking.
这个 bug 处在 Claude Code 的上下文管理、Anthropic API 和扩展思考(extended thinking)的交汇处。
The changes it introduced made it past multiple human and automated code reviews, as well as unit tests, end-to-end tests, automated verification, and dogfooding.
它引入的改动通过了多轮人工和自动化代码审查,也通过了单元测试、端到端测试、自动化验证和内部试用(dogfooding)。
Combined with this only happening in a corner case (stale sessions) and the difficulty of reproducing the issue, it took us over a week to discover and confirm the root cause.
再加上它只发生在一个边缘情况(陈旧会话)下,且问题难以复现,我们花了一周多才发现并确认根因。
As part of the investigation, we back-tested Code Review against the offending pull requests using Opus 4.7.
作为调查的一部分,我们用 Opus 4.7 针对涉事的 PR 对 Code Review 进行了回溯测试。
When provided the code repositories necessary to gather complete context, Opus 4.7 found the bug, while Opus 4.6 didn't.
在提供了为收集完整上下文所必需的代码仓库后,Opus 4.7 找到了这个 bug,而 Opus 4.6 没有。
To prevent this from happening again, we are now landing support for additional repositories as context for code reviews.
为防止此类问题再次发生,我们正在落地对更多仓库的支持,将其作为代码审查的上下文。
We fixed this bug on April 10 in v2.1.101.
我们在 4 月 10 日的 v2.1.101 中修复了这个 bug。
Our latest model, Claude Opus 4.7, has a notable behavioral quirk relative to its predecessor: as we wrote about at launch, it tends to be quite verbose.
我们最新的模型 Claude Opus 4.7 相比前代有一个值得注意的行为怪癖:正如我们在发布时写到的,它倾向于相当冗长。
This makes it smarter on hard problems, but it also produces more output tokens.
这让它在难题上更聪明,但也会产生更多输出 token。
A few weeks before we released Opus 4.7, we started tuning Claude Code in preparation.
在发布 Opus 4.7 的几周前,我们就开始着手调优 Claude Code 做准备。
Each model behaves slightly differently, and we spend time before each release optimizing the harness and product for it.
每个模型的行为都略有不同,我们在每次发布前都会花时间针对它优化框架(harness)和产品。
We have a number of tools to reduce verbosity: model training, prompting, and improving thinking UX in the product.
我们有多种手段来减少冗长:模型训练、提示词调优,以及改进产品中的思考体验。
Ultimately we used all of these, but one addition to the system prompt caused an outsized effect on intelligence in Claude Code:
最终这些手段我们都用上了,但系统提示词中的一处新增内容对 Claude Code 的智能程度产生了格外大的影响:
“Length limits: keep text between tool calls to ≤25 words.
“长度限制:工具调用之间的文本保持在 ≤25 个词。
Keep final responses to ≤100 words unless the task requires more detail.”
最终回复保持在 ≤100 个词,除非任务需要更多细节。”
After multiple weeks of internal testing and no regressions in the set of evaluations we ran, we felt confident about the change and shipped it alongside Opus 4.7 on April 16.
经过数周的内部测试,且我们运行的那组评测没有出现回归后,我们对这一改动很有信心,并在 4 月 16 日随 Opus 4.7 一起发布。
As part of this investigation, we ran more ablations (removing lines from the system prompt to understand the impact of each line) using a broader set of evaluations.
作为本次调查的一部分,我们使用更广泛的评测集合运行了更多消融实验(ablation)(从系统提示词中删除某些行,以了解每一行的影响)。
One of these evaluations showed a 3% drop for both Opus 4.6 and 4.7.
其中一项评测显示,Opus 4.6 和 4.7 都出现了 3% 的下降。
We immediately reverted the prompt as part of the April 20 release.
作为 4 月 20 日发布的一部分,我们立即回滚了该提示词。
We are going to do several things differently to avoid these issues: we’ll ensure that a larger share of internal staff use the exact public build of Claude Code (as opposed to the version we use to test new features); and we'll make improvements to our Code Review tool that we use internally, and ship this improved version to customers.
为了避免这些问题,我们将在几个方面做出改变:我们会确保更多内部员工使用 Claude Code 的公开构建版本本身(而不是我们用来测试新功能的版本);我们还会改进内部使用的 Code Review 工具,并将改进后的版本交付给客户。
We’re also adding tighter controls on system prompt changes.
我们还将对系统提示词的变更施加更严格的控制。
We will run a broad suite of per-model evals for every system prompt change to Claude Code, continuing ablations to understand the impact of each line, and we have built new tooling to make prompt changes easier to review and audit.
对于 Claude Code 的每一次系统提示词变更,我们都会运行一整套针对各模型的评测,并继续通过消融实验了解每一行的影响;我们还构建了新工具,让提示词变更更易于审查和审计。
We've additionally added guidance to our CLAUDE.md to ensure model-specific changes are gated to the specific model they're targeting.
此外,我们在 CLAUDE.md 中增加了指引,确保针对特定模型的变更只作用于它们所针对的那个模型。
For any change that could trade off against intelligence, we'll add soak periods, a broader eval suite, and gradual rollouts so we catch issues earlier.
对于任何可能以智能为代价的变更,我们都会加入观察期(soak period)、更广泛的评测套件和逐步发布,以便更早发现问题。
We recently created @ClaudeDevs on X to give us the room to explain product decisions and the reasoning behind them in depth.
我们最近在 X 上创建了 @ClaudeDevs,以便有空间深入解释产品决策及其背后的理由。
We'll share the same updates in centralized threads on GitHub.
我们也会在 GitHub 的集中式讨论帖中同步这些更新。
Finally, we’d like to thank our users: the people who used the /feedback command to share their issues with us (or who posted specific, reproducible examples online) are the ones who ultimately allowed us to identify and fix these problems.
最后,我们要感谢我们的用户:正是那些使用 /feedback 命令向我们反馈问题的人(或在网上发布具体、可复现示例的人),最终让我们得以定位并修复这些问题。
Today we are resetting usage limits for all subscribers.
今天,我们将为所有订阅用户重置用量限制。
We’re immensely grateful for your feedback and for your patience.
我们非常感谢你们的反馈与耐心。