在 Claude 开发者平台上推出高级工具调用
Introducing advanced tool use on the Claude Developer Platform
文章目录
The future of AI agents is one where models work seamlessly across hundreds or thousands of tools.
AI 智能体(AI agents)的未来,是模型能够无缝地使用数百甚至数千种工具。
An IDE assistant that integrates git operations, file manipulation, package managers, testing frameworks, and deployment pipelines.
一个 IDE 助手,集成了 git 操作、文件操作、包管理器、测试框架和部署流水线。
An operations coordinator that connects Slack, GitHub, Google Drive, Jira, company databases, and dozens of MCP servers simultaneously.
一个运营协调器,可同时连接 Slack、GitHub、Google Drive、Jira、公司数据库和数十个 MCP 服务器。
To build effective agents, they need to work with unlimited tool libraries without stuffing every definition into context upfront.
要构建有效的智能体,它们需要能够使用无限的工具库,而不是预先将每个定义都塞入上下文(context)。
Our blog article on using code execution with MCP discussed how tool results and definitions can sometimes consume 50,000+ tokens before an agent reads a request.
我们关于使用 MCP 进行代码执行的博客文章讨论了,工具结果和定义有时会在智能体读取请求之前消耗 50,000+ 个 token。
Agents should discover and load tools on-demand, keeping only what's relevant for the current task.
智能体应该按需发现并加载工具,只保留与当前任务相关的内容。
Agents also need the ability to call tools from code.
智能体还需要能够从代码中调用工具。
When using natural language tool calling, each invocation requires a full inference pass, and intermediate results pile up in context whether they're useful or not.
在使用自然语言工具调用时,每次调用都需要一次完整的推理过程,而中间结果无论是否有用都会堆积在上下文中。
Code is a natural fit for orchestration logic, such as loops, conditionals, and data transformations.
代码天然适合用于编排(orchestration)逻辑,例如循环、条件判断和数据转换。
Agents need the flexibility to choose between code execution and inference based on the task at hand.
智能体需要能够根据手头任务,灵活地在代码执行和推理之间进行选择。
Agents also need to learn correct tool usage from examples, not just schema definitions.
智能体还需要从示例中学习正确的工具用法,而不仅仅是 schema 定义。
JSON schemas define what's structurally valid, but can't express usage patterns: when to include optional parameters, which combinations make sense, or what conventions your API expects.
JSON schema 定义了结构上有效的内容,但无法表达使用模式:何时包含可选参数、哪些组合有意义,或者你的 API 期望什么约定。
Today, we're releasing three features that make this possible:
今天,我们发布了三项功能,让这一切成为可能:
Tool Search Tool, which allows Claude to use search tools to access thousands of tools without consuming its context window
Tool Search Tool,它允许 Claude 使用搜索工具来访问数千种工具,而无需消耗其上下文窗口(context window)
Programmatic Tool Calling, which allows Claude to invoke tools in a code execution environment reducing the impact on the model’s context window
编程式工具调用(Programmatic Tool Calling),它允许 Claude 在代码执行环境中调用工具,从而减少对模型上下文窗口的影响
Tool Use Examples, which provides a universal standard for demonstrating how to effectively use a given tool
工具调用示例(Tool Use Examples),它提供了一个通用标准,用于演示如何有效使用给定的工具
In internal testing, we’ve found these features have helped us build things that wouldn’t have been possible with conventional tool use patterns.
在内部测试中,我们发现这些功能帮助我们构建了采用传统工具调用模式无法实现的东西。
For example, Claude for Excel uses Programmatic Tool Calling to read and modify spreadsheets with thousands of rows without overloading the model’s context window.
例如,Claude for Excel 使用编程式工具调用读取和修改有数千行的电子表格,而不会使模型的上下文窗口过载。
Based on our experience, we believe these features open up new possibilities for what you can build with Claude.
基于我们的经验,我们相信这些功能为你用 Claude 构建东西开辟了新的可能性。
Tool Search Tool
工具搜索工具(Tool Search Tool)
The challenge
挑战
MCP tool definitions provide important context, but as more servers connect, those tokens can add up.
MCP 工具定义提供了重要的上下文,但随着接入的服务器越来越多,这些 token 会不断累积。
Consider a five-server setup:
以一个接入五个服务器的配置为例:
GitHub: 35 tools (~26K tokens)
GitHub:35 个工具(约 26K 个 token)
Slack: 11 tools (~21K tokens)
Slack:11 个工具(约 21K 个 token)
Sentry: 5 tools (~3K tokens)
Sentry:5 个工具(约 3K 个 token)
Grafana: 5 tools (~3K tokens)
Grafana:5 个工具(约 3K 个 token)
Splunk: 2 tools (~2K tokens)
Splunk:2 个工具(约 2K 个 token)
That's 58 tools consuming approximately 55K tokens before the conversation even starts.
那就是 58 个工具,在对话还没开始之前就消耗大约 55K token。
Add more servers like Jira (which alone uses ~17K tokens) and you're quickly approaching 100K+ token overhead.
再加上像 Jira 这样的更多服务器(仅它自己就要用约 17K token),你很快就会逼近 100K+ token 的开销。
At Anthropic, we've seen tool definitions consume 134K tokens before optimization.
在 Anthropic,我们见过在优化之前工具定义消耗 134K token 的情况。
But token cost isn't the only issue.
但 token 成本并不是唯一的问题。
The most common failures are wrong tool selection and incorrect parameters, especially when tools have similar names like notification-send-user vs. notification-send-channel.
最常见的失败是工具选择错误和参数不正确,尤其是当工具名称相似时,比如 notification-send-user 与 notification-send-channel。
Our solution
我们的解决方案
Instead of loading all tool definitions upfront, the Tool Search Tool discovers tools on-demand.
Tool Search Tool 不预先加载所有工具定义,而是按需发现工具。
Claude only sees the tools it actually needs for the current task.
Claude 只会看到当前任务实际需要的工具。
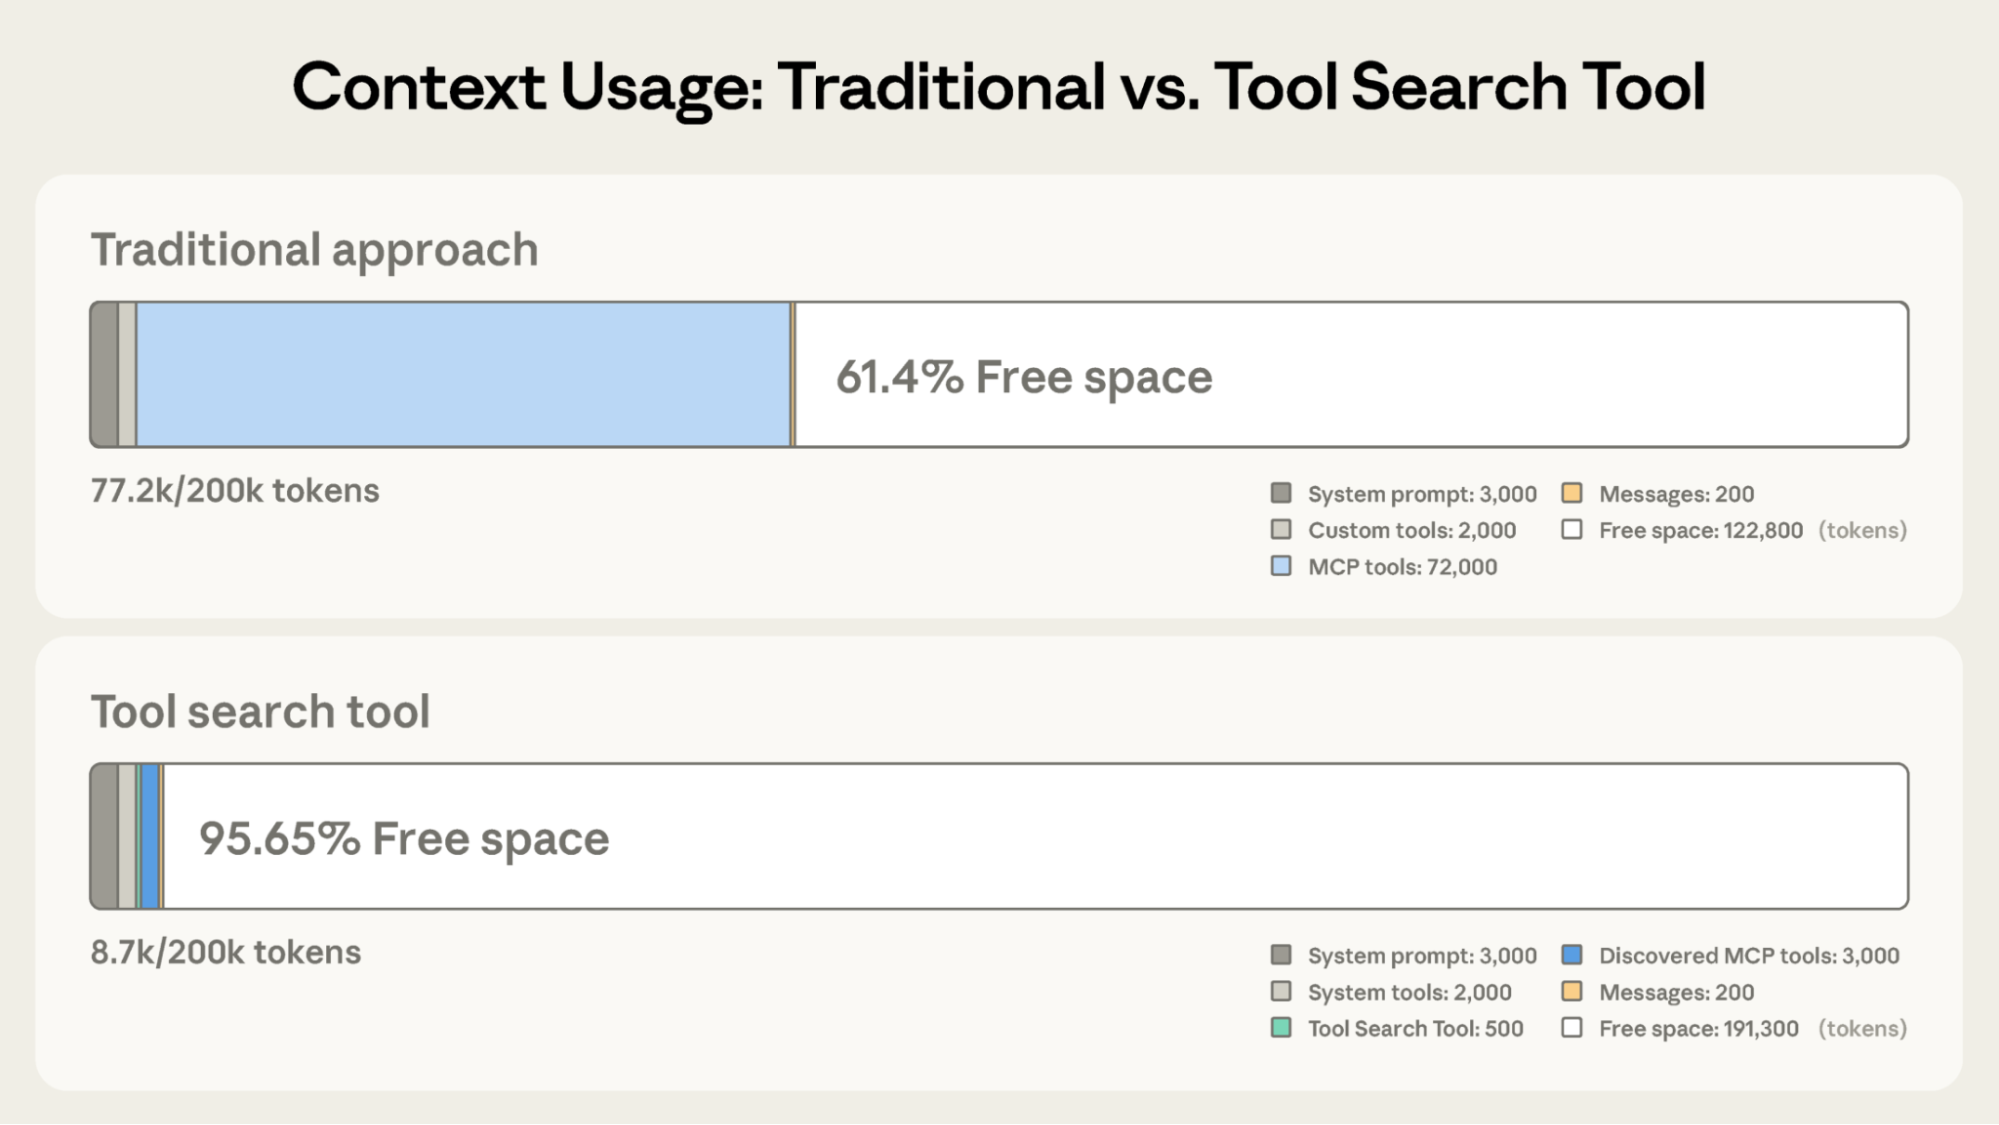
Tool Search Tool preserves 191,300 tokens of context compared to 122,800 with Claude’s traditional approach.
与 Claude 传统方式保留的 122,800 token 相比,Tool Search Tool 保留了 191,300 token 的上下文。
Traditional approach:
传统方式:
All tool definitions loaded upfront (~72K tokens for 50+ MCP tools)
所有工具定义预先加载(50+ 个 MCP 工具约 72K token)
Conversation history and system prompt compete for remaining space
对话历史和系统提示词争夺剩余空间
Total context consumption: ~77K tokens before any work begins
上下文总消耗:任何工作开始前约 77K token
With the Tool Search Tool:
使用 Tool Search Tool 时:
Only the Tool Search Tool loaded upfront (~500 tokens)
只有 Tool Search Tool 预先加载(约 500 token)
Tools discovered on-demand as needed (3-5 relevant tools, ~3K tokens)
工具按需发现(3-5 个相关工具,约 3K token)
Total context consumption: ~8.7K tokens, preserving 95% of context window
总上下文消耗:约 8.7K tokens,保留了 95% 的上下文窗口。
This represents an 85% reduction in token usage while maintaining access to your full tool library.
这代表了 token 使用量减少了 85%,同时保持对完整工具库的访问。
Internal testing showed significant accuracy improvements on MCP evaluations when working with large tool libraries.
内部测试显示,在处理大型工具库时,MCP 评测(eval)的准确率有显著提升。
Opus 4 improved from 49% to 74%, and Opus 4.5 improved from 79.5% to 88.1% with Tool Search Tool enabled.
启用 Tool Search Tool 后,Opus 4 从 49% 提升至 74%,Opus 4.5 从 79.5% 提升至 88.1%。
How the Tool Search Tool works
Tool Search Tool 的工作原理。
The Tool Search Tool lets Claude dynamically discover tools instead of loading all definitions upfront.
Tool Search Tool 允许 Claude 动态发现工具,而不是预先加载所有定义。
You provide all your tool definitions to the API, but mark tools with defer_loading: true to make them discoverable on-demand.
你将所有工具定义提供给 API,但用 defer_loading: true 标记工具,使其可按需发现。
Deferred tools aren't loaded into Claude's context initially.
延迟加载的工具最初不会加载到 Claude 的上下文中。
Claude only sees the Tool Search Tool itself plus any tools with defer_loading: false (your most critical, frequently-used tools).
Claude 只能看到 Tool Search Tool 本身,以及任何带有 defer_loading: false 的工具(即你最关键的、最常用的工具)。
When Claude needs specific capabilities, it searches for relevant tools.
当 Claude 需要特定能力时,它会搜索相关工具。
The Tool Search Tool returns references to matching tools, which get expanded into full definitions in Claude's context.
Tool Search Tool 返回对匹配工具的引用,这些引用会在 Claude 的上下文中展开为完整定义。
For example, if Claude needs to interact with GitHub, it searches for "github," and only github.createPullRequest and github.listIssues get loaded—not your other 50+ tools from Slack, Jira, and Google Drive.
例如,如果 Claude 需要与 GitHub 交互,它会搜索 "github",然后只有 github.createPullRequest 和 github.listIssues 被加载——而不是来自 Slack、Jira 和 Google Drive 的其他 50 多个工具。
This way, Claude has access to your full tool library while only paying the token cost for tools it actually needs.
这样,Claude 既能访问完整的工具库,又只需为它实际需要的工具付出 token 开销。
Prompt caching note: Tool Search Tool doesn't break prompt caching because deferred tools are excluded from the initial prompt entirely.
关于提示词缓存(prompt caching)的说明:Tool Search Tool 不会破坏提示词缓存,因为延迟加载的工具被完全排除在初始提示词之外。
They're only added to context after Claude searches for them, so your system prompt and core tool definitions remain cacheable.
只有当 Claude 搜索它们之后,它们才会被加入上下文,因此你的系统提示词和核心工具定义仍然可被缓存。
Implementation:
实现方式:
{
  "tools": [
    // Include a tool search tool (regex, BM25, or custom)
    {"type": "tool_search_tool_regex_20251119", "name": "tool_search_tool_regex"},

    // Mark tools for on-demand discovery
    {
      "name": "github.createPullRequest",
      "description": "Create a pull request",
      "input_schema": {...},
      "defer_loading": true
    }
    // ... hundreds more deferred tools with defer_loading: true
  ]
}For MCP servers, you can defer loading entire servers while keeping specific high-use tools loaded:
对于 MCP 服务器,你可以延迟加载整个服务器,同时保持某些高频使用的工具处于已加载状态:
{
  "type": "mcp_toolset",
  "mcp_server_name": "google-drive",
  "default_config": {"defer_loading": true}, # defer loading the entire server
  "configs": {
    "search_files": {
"defer_loading": false
    }  // Keep most used tool loaded
  }
}The Claude Developer Platform provides regex-based and BM25-based search tools out of the box, but you can also implement custom search tools using embeddings or other strategies.
Claude Developer Platform 开箱即用地提供基于正则表达式和基于 BM25 的搜索工具,但你也可以使用嵌入(embedding)或其他策略来实现自定义搜索工具。
When to use the Tool Search Tool
何时使用 Tool Search Tool
Like any architectural decision, enabling the Tool Search Tool involves trade-offs.
与任何架构决策一样,启用 Tool Search Tool 都涉及权衡取舍。
The feature adds a search step before tool invocation, so it delivers the best ROI when the context savings and accuracy improvements outweigh additional latency.
该功能在工具调用前增加了一个搜索步骤,因此当上下文节省与准确率提升超过额外延迟时,它的 ROI 最高。
Use it when:
在以下情况使用:
Tool definitions consuming >10K tokens
工具定义消耗超过 10K token
Experiencing tool selection accuracy issues
遇到工具选择准确率问题
Building MCP-powered systems with multiple servers
构建由 MCP 驱动的多服务器系统
10+ tools available
可用工具达 10 个以上
Less beneficial when:
以下情况下收益较低:
Small tool library (<10 tools)
工具库较小(少于 10 个工具)
All tools used frequently in every session
所有工具在每次会话中都被频繁使用
Tool definitions are compact
工具定义较为紧凑
Programmatic Tool Calling
Programmatic Tool Calling
The challenge
挑战
Traditional tool calling creates two fundamental problems as workflows become more complex:
随着工作流变得越来越复杂,传统工具调用会产生两个根本性问题:
Context pollution from intermediate results: When Claude analyzes a 10MB log file for error patterns, the entire file enters its context window, even though Claude only needs a summary of error frequencies.
中间结果带来的上下文污染:当 Claude 分析一个 10MB 的日志文件以寻找错误模式时,整个文件都会进入它的上下文窗口,尽管 Claude 只需要错误频率的摘要。
When fetching customer data across multiple tables, every record accumulates in context regardless of relevance.
当跨多个表获取客户数据时,无论是否相关,每条记录都会累积到上下文中。
These intermediate results consume massive token budgets and can push important information out of the context window entirely.
这些中间结果会消耗大量 token 预算,并可能把重要信息完全挤出上下文窗口。
Inference overhead and manual synthesis: Each tool call requires a full model inference pass.
推理开销与人工综合:每次工具调用都需要一次完整的模型推理。
After receiving results, Claude must "eyeball" the data to extract relevant information, reason about how pieces fit together, and decide what to do next—all through natural language processing.
收到结果后,Claude 必须“用眼睛看”数据来提取相关信息,推理各个部分如何组合在一起,并决定下一步做什么——而这一切都通过自然语言处理完成。
A five tool workflow means five inference passes plus Claude parsing each result, comparing values, and synthesizing conclusions.
一个包含五个工具的工作流意味着五次推理,外加 Claude 解析每个结果、比较数值并综合得出结论。
This is both slow and error-prone.
这既慢又容易出错。
Our solution
我们的解决方案
Programmatic Tool Calling enables Claude to orchestrate tools through code rather than through individual API round-trips.
Programmatic Tool Calling 让 Claude 能够通过代码来编排工具,而不是通过一次次单独的 API 往返调用。
Instead of Claude requesting tools one at a time with each result being returned to its context, Claude writes code that calls multiple tools, processes their outputs, and controls what information actually enters its context window.
Claude 不再一次请求一个工具、并把每个结果返回到其上下文中,而是编写代码来调用多个工具、处理它们的输出,并控制哪些信息真正进入其上下文窗口。
Claude excels at writing code and by letting it express orchestration logic in Python rather than through natural language tool invocations, you get more reliable, precise control flow.
Claude 擅长编写代码,让它用 Python 而不是自然语言工具调用来表达编排逻辑,你就能获得更可靠、更精确的控制流。
Loops, conditionals, data transformations, and error handling are all explicit in code rather than implicit in Claude's reasoning.
循环、条件判断、数据转换和错误处理都在代码中显式表达,而不是隐含在 Claude 的推理中。
Example: Budget compliance check
示例:预算合规检查
Consider a common business task: "Which team members exceeded their Q3 travel budget?"
考虑一个常见的业务任务:「哪些团队成员超出了他们的 Q3 差旅预算?」
You have three tools available:
你有三个可用工具:
get_team_members(department) - Returns team member list with IDs and levels
get_team_members(department) - 返回包含 ID 和级别的团队成员列表
get_expenses(user_id, quarter) - Returns expense line items for a user
get_expenses(user_id, quarter) - 返回某个用户的费用明细行项目
get_budget_by_level(level) - Returns budget limits for an employee level
get_budget_by_level(level) - 返回某个员工级别的预算限额
Traditional approach:
传统做法:
Fetch team members → 20 people
获取团队成员 → 20 人
For each person, fetch their Q3 expenses → 20 tool calls, each returning 50-100 line items (flights, hotels, meals, receipts)
对每个人,获取其 Q3 费用 → 20 次工具调用,每次返回 50-100 条明细条目(机票、酒店、餐饮、收据)
Fetch budget limits by employee level
按员工级别获取预算上限
All of this enters Claude's context: 2,000+ expense line items (50 KB+)
所有这一切都会进入 Claude 的上下文:2,000+ 条费用明细条目(50 KB+)
Claude manually sums each person's expenses, looks up their budget, compares expenses against budget limits
Claude 手动汇总每个人的费用,查找其预算,并将费用与预算上限进行比较
More round-trips to the model, significant context consumption
与模型之间的往返次数更多,上下文消耗显著
With Programmatic Tool Calling:
使用 Programmatic Tool Calling 时:
Instead of each tool result returning to Claude, Claude writes a Python script that orchestrates the entire workflow.
不再是每个工具结果都返回给 Claude,而是由 Claude 编写一个 Python 脚本,编排整个工作流。
The script runs in the Code Execution tool (a sandboxed environment), pausing when it needs results from your tools.
该脚本在 Code Execution tool(一个沙箱环境)中运行,在需要你的工具返回结果时暂停。
When you return tool results via the API, they're processed by the script rather than consumed by the model.
当你通过 API 返回工具结果时,这些结果由脚本处理,而不是被模型消耗。
The script continues executing, and Claude only sees the final output.
脚本继续执行,而 Claude 只看到最终输出。
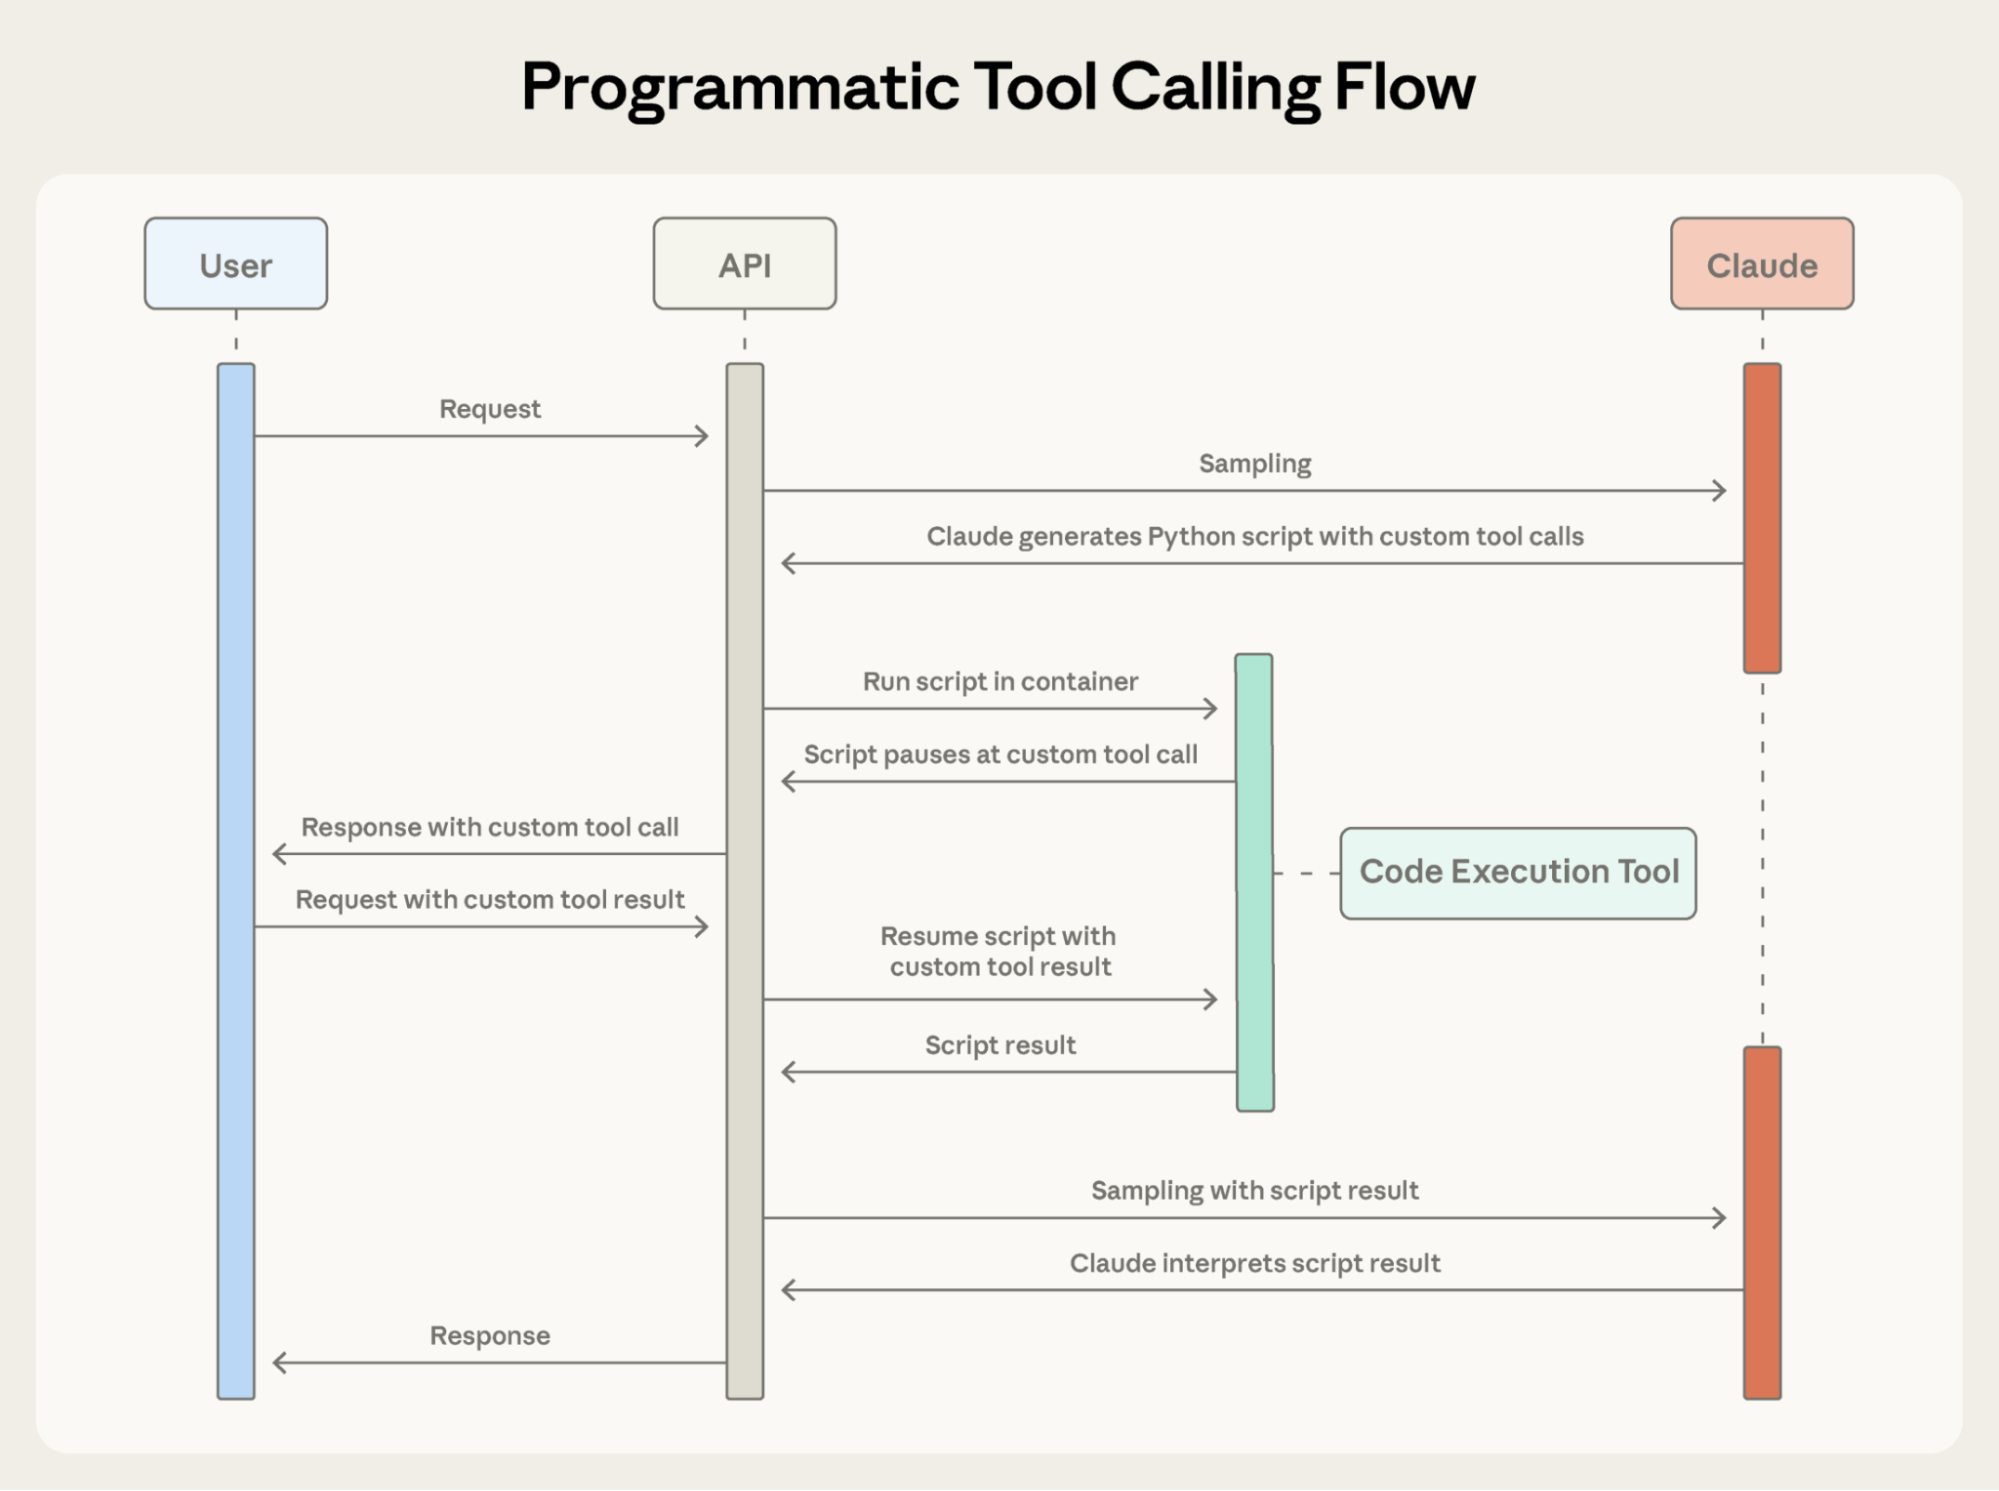
Programmatic Tool Calling enables Claude to orchestrate tools through code rather than through individual API round-trips, allowing for parallel tool execution.
Programmatic Tool Calling 使 Claude 能够通过代码而非单次 API 往返来编排工具,从而实现工具的并行执行。
Here's what Claude's orchestration code looks like for the budget compliance task:
以下是 Claude 用于预算合规任务的编排代码:
team = await get_team_members("engineering")

# Fetch budgets for each unique level
levels = list(set(m["level"] for m in team))
budget_results = await asyncio.gather(*[
    get_budget_by_level(level) for level in levels
])

# Create a lookup dictionary: {"junior": budget1, "senior": budget2, ...}
budgets = {level: budget for level, budget in zip(levels, budget_results)}

# Fetch all expenses in parallel
expenses = await asyncio.gather(*[
    get_expenses(m["id"], "Q3") for m in team
])

# Find employees who exceeded their travel budget
exceeded = []
for member, exp in zip(team, expenses):
    budget = budgets[member["level"]]
    total = sum(e["amount"] for e in exp)
    if total > budget["travel_limit"]:
        exceeded.append({
            "name": member["name"],
            "spent": total,
            "limit": budget["travel_limit"]
        })

print(json.dumps(exceeded))Claude's context receives only the final result: the two to three people who exceeded their budget.
Claude 的上下文只接收最终结果:两到三个超出预算的人。
The 2,000+ line items, the intermediate sums, and the budget lookups do not affect Claude’s context, reducing consumption from 200KB of raw expense data to just 1KB of results.
2,000 多个明细项、中间求和结果以及预算查询都不会影响 Claude 的上下文,将消耗量从 200KB 的原始费用数据减少到仅 1KB 的结果。
The efficiency gains are substantial:
效率提升非常显著:
Token savings: By keeping intermediate results out of Claude's context, PTC dramatically reduces token consumption.
Token 节省:通过将中间结果排除在 Claude 的上下文之外,PTC 大幅降低了 token 消耗。
Average usage dropped from 43,588 to 27,297 tokens, a 37% reduction on complex research tasks.
平均用量从 43,588 降至 27,297 token,在复杂研究任务上减少了 37%。
Reduced latency: Each API round-trip requires model inference (hundreds of milliseconds to seconds).
延迟降低:每次 API 往返都需要模型推理(数百毫秒到数秒)。
When Claude orchestrates 20+ tool calls in a single code block, you eliminate 19+ inference passes.
当 Claude 在单个代码块中编排 20 次以上的工具调用时,你就省去了 19 次以上的推理过程。
The API handles tool execution without returning to the model each time.
API 负责处理工具执行,无需每次都返回模型。
Improved accuracy: By writing explicit orchestration logic, Claude makes fewer errors than when juggling multiple tool results in natural language.
准确率提升:通过编写显式的编排逻辑,Claude 比用自然语言应付多个工具结果时犯的错误更少。
Internal knowledge retrieval improved from 25.6% to 28.5%; GIA benchmarks from 46.5% to 51.2%.
内部知识检索从 25.6% 提升至 28.5%;GIA 基准从 46.5% 提升至 51.2%。
Production workflows involve messy data, conditional logic, and operations that need to scale.
生产工作流涉及杂乱的数据、条件逻辑以及需要规模化的操作。
Programmatic Tool Calling lets Claude handle that complexity programmatically while keeping its focus on actionable results rather than raw data processing.
Programmatic Tool Calling 让 Claude 以编程方式处理这种复杂性,同时将注意力集中在可操作的结果上,而非原始数据处理。
How Programmatic Tool Calling works
Programmatic Tool Calling 的工作原理
1. Mark tools as callable from code
1. 将工具标记为可从代码调用
Add code_execution to tools, and set allowed_callers to opt-in tools for programmatic execution:
在 tools 中添加 code_execution,并将 allowed_callers 设置为让工具选择启用程序化执行:
{
  "tools": [
    {
      "type": "code_execution_20250825",
      "name": "code_execution"
    },
    {
      "name": "get_team_members",
      "description": "Get all members of a department...",
      "input_schema": {...},
      "allowed_callers": ["code_execution_20250825"] # opt-in to programmatic tool calling
    },
    {
      "name": "get_expenses",
 	...
    },
    {
      "name": "get_budget_by_level",
	...
    }
  ]
}The API converts these tool definitions into Python functions that Claude can call.
API 会将这些工具定义转换为 Claude 可以调用的 Python 函数。
2. Claude writes orchestration code
2. Claude 编写编排代码
Instead of requesting tools one at a time, Claude generates Python code:
Claude 不再逐个请求工具,而是生成 Python 代码:
{
  "type": "server_tool_use",
  "id": "srvtoolu_abc",
  "name": "code_execution",
  "input": {
    "code": "team = get_team_members('engineering')\n..." # the code example above
  }
}
3. Tools execute without hitting Claude's context
3. 工具的执行不会进入 Claude 的上下文
When the code calls get_expenses(), you receive a tool request with a caller field:
当代码调用 get_expenses() 时,你会收到一个带有 caller 字段的工具请求:
{
  "type": "tool_use",
  "id": "toolu_xyz",
  "name": "get_expenses",
  "input": {"user_id": "emp_123", "quarter": "Q3"},
  "caller": {
    "type": "code_execution_20250825",
    "tool_id": "srvtoolu_abc"
  }
}You provide the result, which is processed in the Code Execution environment rather than Claude's context.
你提供结果,该结果在 Code Execution 环境中处理,而非在 Claude 的上下文中处理。
This request-response cycle repeats for each tool call in the code.
对于代码中的每次工具调用,这个请求-响应循环都会重复一次。
4. Only final output enters context
4. 只有最终输出会进入上下文
When the code finishes running, only the results of the code are returned to Claude:
当代码运行结束后,只有代码的结果会返回给 Claude:
{
  "type": "code_execution_tool_result",
  "tool_use_id": "srvtoolu_abc",
  "content": {
    "stdout": "[{\"name\": \"Alice\", \"spent\": 12500, \"limit\": 10000}...]"
  }
}This is all Claude sees, not the 2000+ expense line items processed along the way.
这就是 Claude 看到的全部内容,而不是过程中处理过的 2000 多个费用明细项。
When to use Programmatic Tool Calling
何时使用 Programmatic Tool Calling
Programmatic Tool Calling adds a code execution step to your workflow.
Programmatic Tool Calling 会在你的工作流中增加一个代码执行步骤。
This extra overhead pays off when the token savings, latency improvements, and accuracy gains are substantial.
当 token 节省、延迟改善和准确率提升足够可观时,这份额外开销就是值得的。
Most beneficial when:
以下情况下最有益:
Processing large datasets where you only need aggregates or summaries
处理只需要聚合结果或摘要的大型数据集
Running multi-step workflows with three or more dependent tool calls
运行包含三个或更多相互依赖的工具调用的多步工作流
Filtering, sorting, or transforming tool results before Claude sees them
在 Claude 看到工具结果之前对其进行过滤、排序或转换
Handling tasks where intermediate data shouldn't influence Claude's reasoning
处理中间数据不应影响 Claude 推理的任务
Running parallel operations across many items (checking 50 endpoints, for example)
跨大量条目执行并行操作(例如检查 50 个端点)
Less beneficial when:
在以下情况下收益较小:
Making simple single-tool invocations
进行简单的单工具调用
Working on tasks where Claude should see and reason about all intermediate results
处理需要 Claude 看到并推理所有中间结果的任务
Running quick lookups with small responses
执行响应较小的快速查询
Tool Use Examples
Tool Use Examples
The challenge
挑战
JSON Schema excels at defining structure–types, required fields, allowed enums–but it can't express usage patterns: when to include optional parameters, which combinations make sense, or what conventions your API expects.
JSON Schema 擅长定义结构——类型、必填字段、允许的枚举(enums)——但它无法表达使用模式:何时包含可选参数、哪些组合有意义,或者你的 API 期望什么约定。
Consider a support ticket API:
设想一个支持工单 API:
{
  "name": "create_ticket",
  "input_schema": {
    "properties": {
      "title": {"type": "string"},
      "priority": {"enum": ["low", "medium", "high", "critical"]},
      "labels": {"type": "array", "items": {"type": "string"}},
      "reporter": {
        "type": "object",
        "properties": {
          "id": {"type": "string"},
          "name": {"type": "string"},
          "contact": {
            "type": "object",
            "properties": {
              "email": {"type": "string"},
              "phone": {"type": "string"}
            }
          }
        }
      },
      "due_date": {"type": "string"},
      "escalation": {
        "type": "object",
        "properties": {
          "level": {"type": "integer"},
          "notify_manager": {"type": "boolean"},
          "sla_hours": {"type": "integer"}
        }
      }
    },
    "required": ["title"]
  }
}The schema defines what's valid, but leaves critical questions unanswered:
该模式(schema)定义了什么是有效的,但留下了关键问题未解答:
Format ambiguity: Should due_date use "2024-11-06", "Nov 6, 2024", or "2024-11-06T00:00:00Z"?
格式歧义:due_date 应该使用 "2024-11-06"、"Nov 6, 2024" 还是 "2024-11-06T00:00:00Z"?
ID conventions: Is reporter.id a UUID, "USR-12345", or just "12345"?
ID 约定:reporter.id 是 UUID、"USR-12345" 还是只是 "12345"?
Nested structure usage: When should Claude populate reporter.contact?
嵌套结构用法:Claude 应在何时填充 reporter.contact?
Parameter correlations: How do escalation.level and escalation.sla_hours relate to priority?
参数关联:escalation.level 和 escalation.sla_hours 与优先级有何关系?
These ambiguities can lead to malformed tool calls and inconsistent parameter usage.
这些歧义可能导致工具调用格式错误以及参数使用不一致。
Our solution
我们的解决方案
Tool Use Examples let you provide sample tool calls directly in your tool definitions.
Tool Use Examples 让你可以直接在工具定义中提供示例工具调用。
Instead of relying on schema alone, you show Claude concrete usage patterns:
你不必只依赖 schema,而是向 Claude 展示具体的使用模式:
{
    "name": "create_ticket",
    "input_schema": { /* same schema as above */ },
    "input_examples": [
      {
        "title": "Login page returns 500 error",
        "priority": "critical",
        "labels": ["bug", "authentication", "production"],
        "reporter": {
          "id": "USR-12345",
          "name": "Jane Smith",
          "contact": {
            "email": "jane@acme.com",
            "phone": "+1-555-0123"
          }
        },
        "due_date": "2024-11-06",
        "escalation": {
          "level": 2,
          "notify_manager": true,
          "sla_hours": 4
        }
      },
      {
        "title": "Add dark mode support",
        "labels": ["feature-request", "ui"],
        "reporter": {
          "id": "USR-67890",
          "name": "Alex Chen"
        }
      },
      {
        "title": "Update API documentation"
      }
    ]
}From these three examples, Claude learns:
从这三个示例中,Claude 学会了:
Format conventions: Dates use YYYY-MM-DD, user IDs follow USR-XXXXX, labels use kebab-case
格式约定:日期使用 YYYY-MM-DD,用户 ID 遵循 USR-XXXXX,标签使用 kebab-case
Nested structure patterns: How to construct the reporter object with its nested contact object
嵌套结构模式:如何构造 reporter 对象及其嵌套的 contact 对象
Optional parameter correlations: Critical bugs have full contact info + escalation with tight SLAs; feature requests have reporter but no contact/escalation; internal tasks have title only
可选参数关联:关键 bug 具有完整的 contact info + 带有严格 SLA 的 escalation;功能请求有 reporter 但没有 contact/escalation;内部任务只有 title
In our own internal testing, tool use examples improved accuracy from 72% to 90% on complex parameter handling.
在我们自己的内部测试中,Tool Use Examples 将复杂参数处理的准确率从 72% 提升到 90%。
When to use Tool Use Examples
何时使用 Tool Use Examples
Tool Use Examples add tokens to your tool definitions, so they’re most valuable when accuracy improvements outweigh the additional cost.
Tool Use Examples 会向你的工具定义添加 token,因此当准确率提升超过额外成本时,它们最有价值。
Most beneficial when:
最有益的情况:
Complex nested structures where valid JSON doesn't imply correct usage
复杂的嵌套结构,此时 JSON 合法并不意味着用法正确
Tools with many optional parameters and inclusion patterns matter
具有大量可选参数且包含模式很重要的工具
APIs with domain-specific conventions not captured in schemas
带有 schema 未涵盖的领域特定约定的 API
Similar tools where examples clarify which one to use (e.g., create_ticket vs create_incident)
相似的工具,示例可说明该用哪一个(例如 create_ticket 与 create_incident)
Less beneficial when:
收益较低的情况:
Simple single-parameter tools with obvious usage
用法明确的简单单参数工具
Standard formats like URLs or emails that Claude already understands
Claude 已经理解的标准格式,如 URL 或 email
Validation concerns better handled by JSON Schema constraints
更适合由 JSON Schema 约束来处理的校验问题
Best practices
最佳实践
Building agents that take real-world actions means handling scale, complexity, and precision simultaneously.
构建能够执行真实世界操作的智能体,意味着要同时应对规模、复杂度和精度。
These three features work together to solve different bottlenecks in tool use workflows.
这三项功能协同工作,解决工具调用工作流中不同的瓶颈。
Here's how to combine them effectively.
以下是如何有效地将它们组合起来。
Layer features strategically
有策略地分层使用各项功能
Not every agent needs to use all three features for a given task.
并非每个智能体在给定任务中都需要用到全部三项功能。
Start with your biggest bottleneck:
从你最大的瓶颈入手:
Context bloat from tool definitions → Tool Search Tool
工具定义导致的上下文膨胀 → Tool Search Tool
Large intermediate results polluting context → Programmatic Tool Calling
大量中间结果污染上下文 → Programmatic Tool Calling
Parameter errors and malformed calls → Tool Use Examples
参数错误和格式错误的调用 → Tool Use Examples
This focused approach lets you address the specific constraint limiting your agent's performance, rather than adding complexity upfront.
这种聚焦的做法让你能解决限制智能体性能的具体约束,而不是一开始就增加复杂度。
Then layer additional features as needed.
然后按需叠加其他功能。
They're complementary: Tool Search Tool ensures the right tools are found, Programmatic Tool Calling ensures efficient execution, and Tool Use Examples ensure correct invocation.
它们是互补的:Tool Search Tool 确保找到正确的工具,Programmatic Tool Calling 确保高效执行,Tool Use Examples 确保正确调用。
Set up Tool Search Tool for better discovery
设置 Tool Search Tool 以获得更好的发现效果
Tool search matches against names and descriptions, so clear, descriptive definitions improve discovery accuracy.
工具搜索会匹配名称和描述,因此清晰、具有描述性的定义能提高发现的准确性。
// Good
{
    "name": "search_customer_orders",
    "description": "Search for customer orders by date range, status, or total amount. Returns order details including items, shipping, and payment info."
}

// Bad
{
    "name": "query_db_orders",
    "description": "Execute order query"
}Add system prompt guidance so Claude knows what's available:
添加系统提示词指引,让 Claude 知道有哪些可用内容:
You have access to tools for Slack messaging, Google Drive file management,
Jira ticket tracking, and GitHub repository operations. Use the tool search
to find specific capabilities.Keep your three to five most-used tools always loaded, defer the rest.
将你最常用的三到五个工具保持始终加载,其余工具延迟加载。
This balances immediate access for common operations with on-demand discovery for everything else.
这样既能为常见操作提供即时访问,又能按需发现其他所有工具。
Set up Programmatic Tool Calling for correct execution
设置 Programmatic Tool Calling 以确保正确执行
Since Claude writes code to parse tool outputs, document return formats clearly.
由于 Claude 会编写代码来解析工具输出,因此要清晰地记录返回格式。
This helps Claude write correct parsing logic:
这有助于 Claude 编写正确的解析逻辑:
{
    "name": "get_orders",
    "description": "Retrieve orders for a customer.
Returns:
    List of order objects, each containing:
    - id (str): Order identifier
    - total (float): Order total in USD
    - status (str): One of 'pending', 'shipped', 'delivered'
    - items (list): Array of {sku, quantity, price}
    - created_at (str): ISO 8601 timestamp"
}See below for opt-in tools that benefit from programmatic orchestration:
请参阅下文,了解可从程序化编排中受益的可选启用工具:
Tools that can run in parallel (independent operations)
可并行运行的工具(独立操作)
Operations safe to retry (idempotent)
可安全重试的操作(幂等)
Set up Tool Use Examples for parameter accuracy
设置 Tool Use Examples 以保证参数准确性
Craft examples for behavioral clarity:
为行为清晰性精心设计示例:
Use realistic data (real city names, plausible prices, not "string" or "value")
使用真实数据(真实城市名称、合理价格,而不是 "string" 或 "value")
Show variety with minimal, partial, and full specification patterns
用最小、部分和完整规范模式展示多样性
Keep it concise: 1-5 examples per tool
保持简洁:每个工具 1-5 个示例
Focus on ambiguity (only add examples where correct usage isn't obvious from schema)
聚焦歧义(仅在正确用法无法从 schema 中明显看出时才添加示例)
Getting started
快速开始
These features are available in beta.
这些功能以 beta 形式提供。
To enable them, add the beta header and include the tools you need:
要启用它们,请添加 beta header 并包含你需要的工具:
client.beta.messages.create(
    betas=["advanced-tool-use-2025-11-20"],
    model="claude-sonnet-4-5-20250929",
    max_tokens=4096,
    tools=[
        {"type": "tool_search_tool_regex_20251119", "name": "tool_search_tool_regex"},
        {"type": "code_execution_20250825", "name": "code_execution"},
        # Your tools with defer_loading, allowed_callers, and input_examples
    ]
)For detailed API documentation and SDK examples, see our:
有关详细的 API 文档和 SDK 示例,请参见我们的:
Documentation and cookbook for Tool Search Tool
Tool Search Tool 的文档与实操手册(cookbook)
Documentation and cookbook for Programmatic Tool Calling
Programmatic Tool Calling 的文档与实操手册
Documentation for Tool Use Examples
Tool Use Examples 的文档
These features move tool use from simple function calling toward intelligent orchestration.
这些特性将工具调用从简单的函数调用推向智能编排。
As agents tackle more complex workflows spanning dozens of tools and large datasets, dynamic discovery, efficient execution, and reliable invocation become foundational.
随着智能体处理横跨数十个工具和大型数据集的更复杂工作流,动态发现、高效执行和可靠调用成为基础性能力。
We're excited to see what you build.
我们很期待看到你构建出的成果。
Acknowledgements
致谢
Written by Bin Wu, with contributions from Adam Jones, Artur Renault, Henry Tay, Jake Noble, Noah Picard, Sam Jiang, and the Claude Developer Platform team.
作者 Bin Wu,贡献者包括 Adam Jones、Artur Renault、Henry Tay、Jake Noble、Noah Picard、Sam Jiang 以及 Claude Developer Platform 团队。
This work builds on foundational research by Chris Gorgolewski, Daniel Jiang, Jeremy Fox and Mike Lambert.
这项工作建立在 Chris Gorgolewski、Daniel Jiang、Jeremy Fox 和 Mike Lambert 的基础研究之上。
We also drew inspiration from across the AI ecosystem, including Joel Pobar's LLMVM, Cloudflare's Code Mode and Code Execution as MCP.
我们还从整个 AI 生态系统中汲取了灵感,包括 Joel Pobar 的 LLMVM、Cloudflare 的 Code Mode 以及 Code Execution as MCP。
Special thanks to Andy Schumeister, Hamish Kerr, Keir Bradwell, Matt Bleifer and Molly Vorwerck for their support.
特别感谢 Andy Schumeister、Hamish Kerr、Keir Bradwell、Matt Bleifer 和 Molly Vorwerck 的支持。